Tag Archives: Machine learning

Folly and opportunity

Yup, a setting that has both. You see yesterday I offered the quote “I made mention of Deeper Machine Learning. This is awesome, it is not AI (AI does not yet exist) but it got me thinking. You see, we now see mention of AI in construction. This is about to go bad, really bad and Trusting these buildings will become folly soon enough. I will try to explain that soon enough” and that soon is now. To see this we need to make a few sidesteps, but it will be clear soon enough. For this I selected ‘Building a smarter future: The impact of big data and AI in construction’ (at https://www.pbctoday.co.uk/news/digital-construction-news/big-data-and-ai-in-construction-trimble/132005/) there are several sources, but this one got a few things really right and that matters to me. They give you “Because computers can be programmed to analyse questions and situations using thousands of parameters in the time it takes most of us to type them in, they’re an incredible tool that we can use to do complex calculations in a fraction of the time it takes any human, and because they approach every situation with logic, they can make the most rational decisions even when we can’t. Artificial intelligence in construction simply takes that to the next level, applying machine learning, which allows those same computers to learn from situations they’ve encountered before and to adjust their results accordingly.” I do not fully agree, but they give a better explanation then most others and they made the big good one by giving us ‘applying machine learning’ this is correct. 

Why is this what?
That is the setting, you see to see this I will need to take you on a little time travel. That is after you realise that machine learning depends on data, loads of it. But in all this the right category is also important. We are about to overlap best practice and best results onto the cheaper way, the cutting corners way. We might rely on movies like the towering inferno (1974) where the movie based on two books namely the Glass inferno and the tower. In the movie we see the bastardly electrical engineer who cut corners (played by Richard Chamberlain) and the architect played by Paul Newman. There we see the little conversation that the electrical engineer Roger Simmons kept to building codes and that the demands by the architect Doug Roberts were outlandish and to cost driving and fair enough, the building burns down on opening night.

Children of Mediocrates
The previous one was a story, fiction. But reality is not. In the 90’s captains of industry shook hands with politicians and a lacking drive was introduced. Almost like the philosopher Mediocrates who introduced a new life lesson ‘Meh, good enough’. I was actually in some of those meetings where we were told. “What if the strive of excellence is not 100%, but 80%. What had is it to be still really good. How much easier is it to build your bonus when we expect a 80% line?” I was there, I heard it all and I was told to adhere to it all. And yes the bonus for me was easier and I was merely in customer service, but it felt wrong. 

Nowadays
So back to today when we look at the application of what some call AI (a wrong term). The data it relies on cannot tell the difference because best practice and cutting corners are all the same thing and it will set a flawed recommendation and the larger folly is that the people in control of that data will not distinguish between the two fronts either. They are to young to tell, or they cannot tell the difference, because those filling their pockets are no longer around. It is a recipe for disaster and when was the last time when construction disasters went without casualties? 

This is the setting I see coming and there is also an opportunity. You see, those cutting corners did not protect the original path. As such these patents and IP points are now open and unprotected. As such these options are there for the clever people to create new innovation patents based on the open original patents, the ones the cutting corners people let be and there should be a fair amount of them all over the field. This is merely because best practice was too expensive for them and now those options are open. An example here might be the Reinforced autoclaved aerated concrete (RAAC). We are now seeing all the issues and the hundreds of buildings that have them. It was an invention in the 1990’s, making the timeline fit. And now we see “Concerns were amplified in 2023 following reports of an earlier roofing collapse at a British primary school, which fell without warning in 2018” Now, one does not mean the other, but there is a premise that fits and as such we see the larger danger. Consider that this all gained popularity in the 50’s. So how many new patents were created based on this idea, and what was left behind and unprotected? I will let you do the math, but whomever has those innovation patents will have the option to fill there pockets with the best practice approach whilst too many are merely in it to make a buck. As such the folly of hiding behind AI is about to hit a lot of people squarely in the face, all whilst the clever people will be able to turn a coin as they have the patents and they will be the only player to be considered soon enough.

Hiding behind hyper words suddenly gives others a chance to become serious players where the big boys never wanted them. How is that for poetic justice?

Enjoy the day, most of the week is still in front of you.
 

Leave a comment

Filed under Finance, IT, Politics, Science

As ideas evolve

This is a story with a few sides. The most prominent side is based on the continuation of Ludum Scriptor, which I wrote 2 days ago (at https://lawlordtobe.com/2023/09/08/ludum-scriptor/) there is set out a new premise, one that could have larger benefits. You see, as I was evolving certain ideas. One of them was to give football and fantasy football a new tool to provide their thoughts for progressing their game.

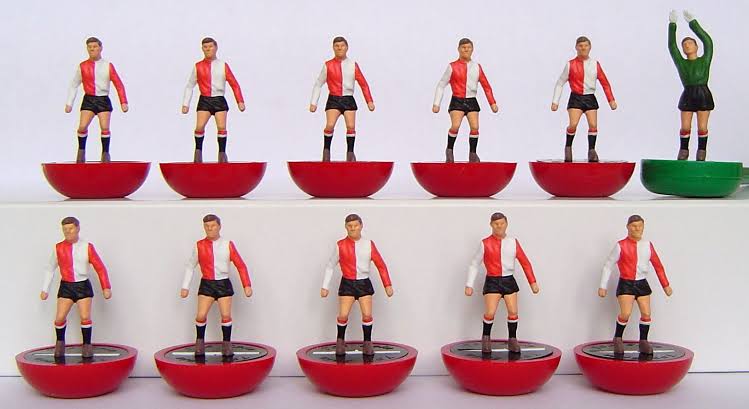
An old game for football addicts was Subutteo. We forgot about the old ideas, but they were good ideas. Now consider that with Deeper Machine Learning we an create any football game and as they are virtual and not based on plastic, they will look a lot more like the players. Any team in the world. Football, NFL, NBA, NHL and that list goes on. People can write and blog about their teams, they can write it in any way they want and that was when the wheels went in overdrive. You see, player cards and all kinds of other means could be made available for bloggers all over the world. And that list does not stop, not for some time. You see Deeper Machine learning as a tool for something like I wrote can do more and YOUR imagination can only drive it further.

Why Microsoft will fail
That was my premise and I kept on referring to a chihuahua stating ‘Try Azure, Azure smells nice’ was only to some degree a joke. But someone on LinkedIn gave me an idea.

You see being on par for a year gets you 1 (or 1365), but the smallest increase gets you to 37.7, 37 times the one you were one year later. And then there is the decrease. Even when you consider 0.99365. You end up with a mere 0.03, that is the difference between the innovator and the copycat. Microsoft lost out sixfold and they will lose out more and more. They are buying all kinds of firms, but like in the 90’s it is a recipe for disaster and innovators will walk out, they nearly always do. You see, in the end it will bite their bottom line and soon their board of directors will make knee jerk decisions making matters worse. When I stated I would make my IP public domain before I allow Microsoft access to it I was not kidding. Microsoft is as I personally see it becoming the larger problem in any equation and it does not stop there. I made mention of Deeper Machine Learning. This is awesome, it is not AI (AI does not yet exist) but it got me thinking. You see, we now see mention of AI in construction. This is about to go bad, really bad and Trusting these buildings will become folly soon enough. I will try to explain that soon enough. 

The evolution
I looked at the idea before I figured out that there were 600 million bloggers. I have no idea there are on the Vlogger side, but I expect that we are looking at interesting numbers. There are millions of fantasy football fans, hundreds of millions of sports fans and giving them space to expose that idea to them will offer more and more space others would like to try that option. We are in all effect dipping our toes in the water and all these numbers does not mean success, lets be clear about it. My idea remains that, an idea that could be liked by a lot of people, all that considering that others have done close to nothing, makes my idea stellar to say the least. 

When you consider that and when you consider creating ML and DML tools aiding people will create evolution of their work and optionally more people considering this. Not all people are creative, they merely think that their writing is not enough, these tools will enable those on the fence and that is already a win for the exploring team. What matters is that on the end of the weekend I came up with more, all whilst others seemingly came up empty. A nice end to the weekend. I have been considering additions to the field of Vloggers and also places where vloggers can propagate their work. Bloggers have their own space and for that I have additional ideas too. An active field where we switch the awakening to the pro-active, but that is for another day. I did my cerebral activity to keep me happy, time for some Ravioli.

Enjoy Sunday.

Leave a comment

Filed under Finance, Gaming, IT, sport

Eric Winter is a god

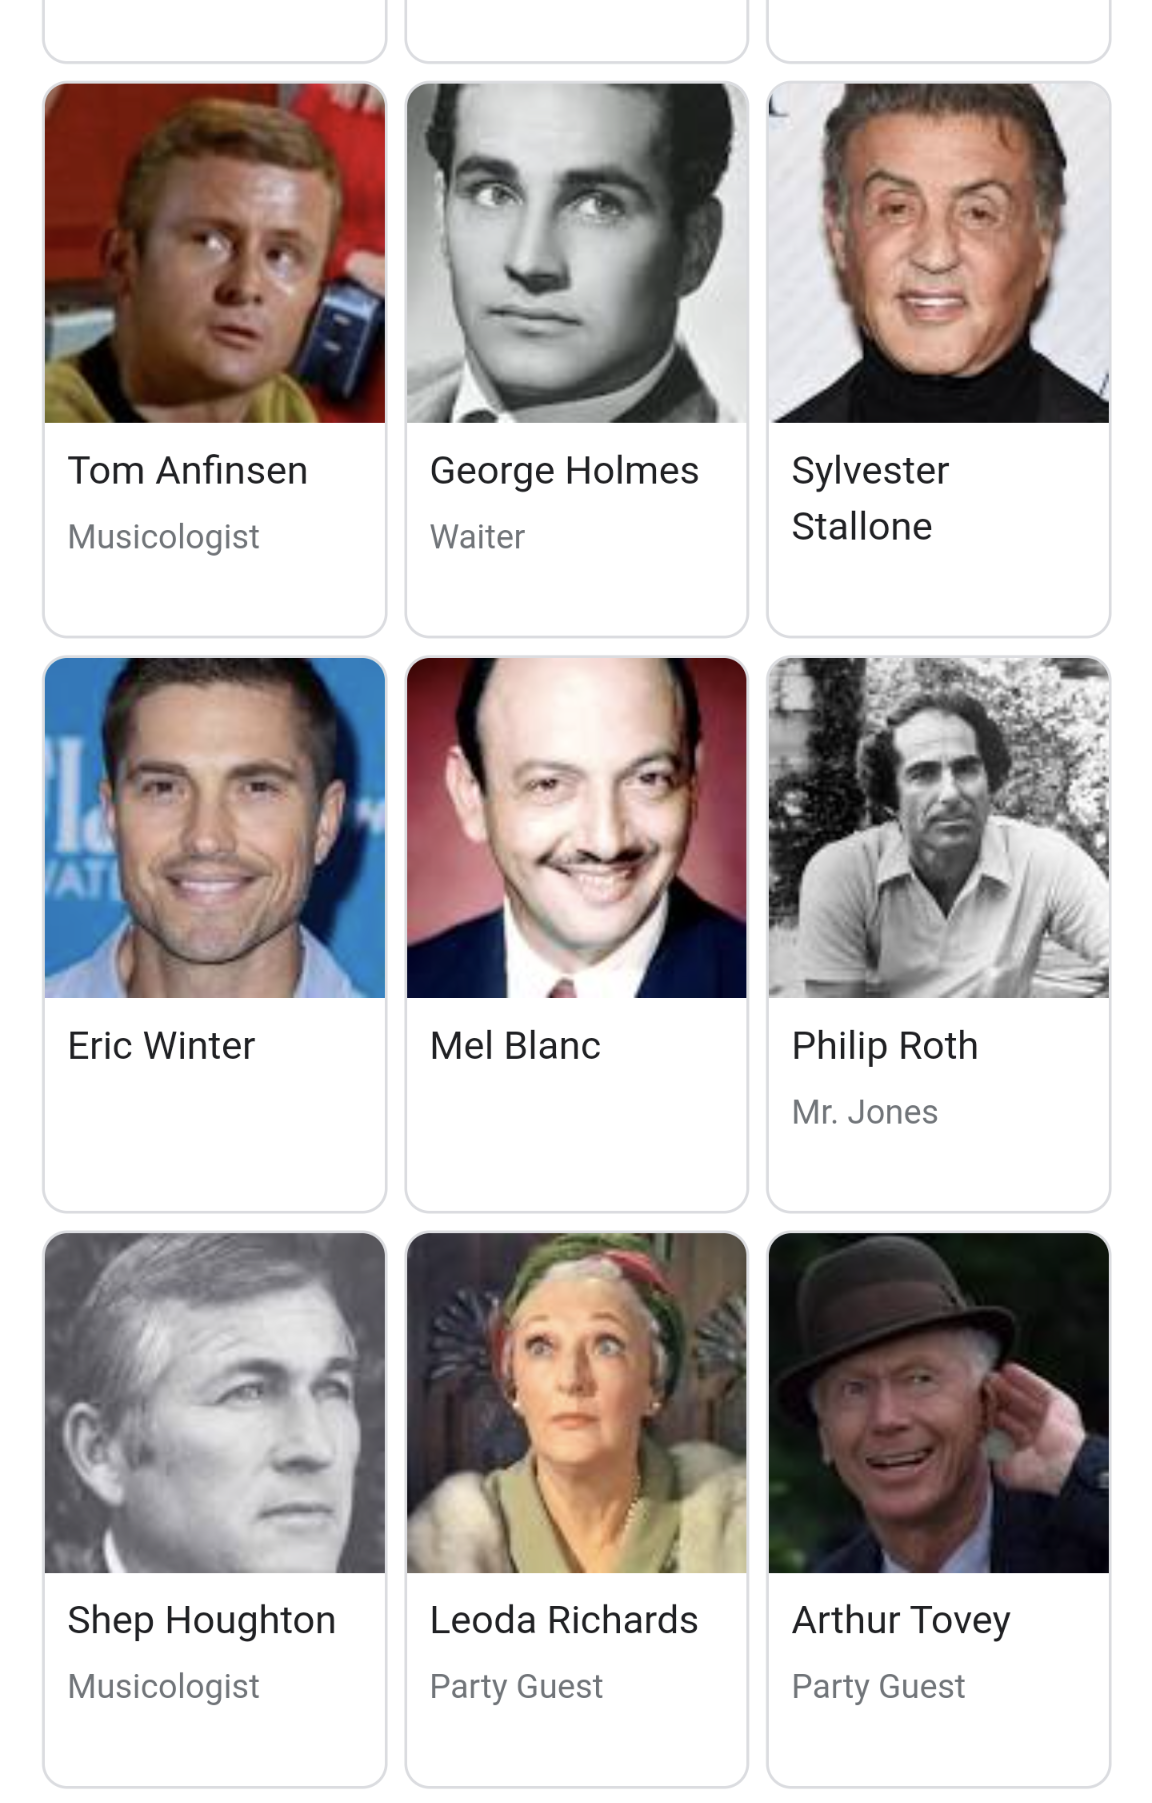
Yup, we are going there. It might not be correct, but that is where the evidence is leading us. You see I got hooked on the Rookie and watched seasons one through four in a week. Yet the name Eric Winter was bugging me and I did not know why. The reason was simple. He also starred in the PS4 game ‘Beyond two souls’ which I played in 2013. I liked that game and his name stuck somehow. Yet when I looked for his name I got

This got me curious, two of the movies I saw and Eric would have been too young to be in them and there is the evidence, presented by Google. Eric Winter born on July 17th 1976 played alongside Barbara Streisand 4 years before he was born, evidence of godhood. 

And when we look at the character list, there he is. 

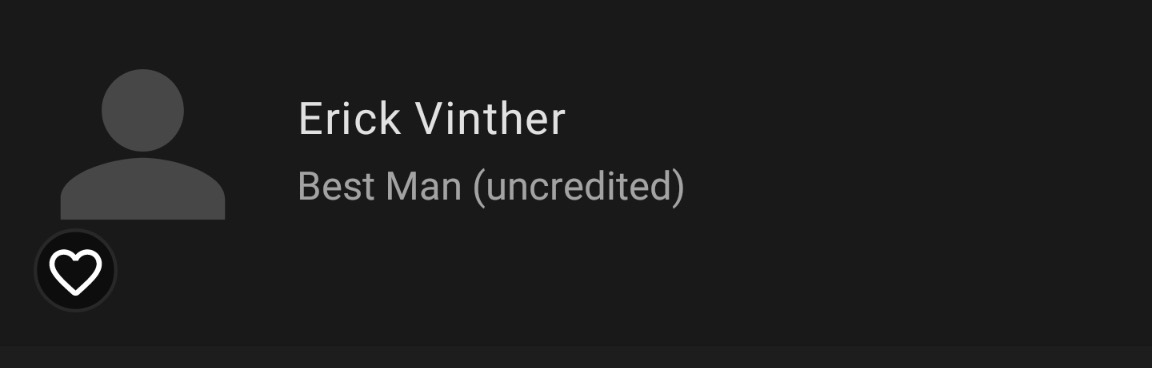
Yet when we look at a real movie reference like IMDB.com we will get 

Yes, that is the real person who was in the movie. We can write this up as a simple error, but that is not the path we are trodding on. You see, people are all about AI and ChatGPT but the real part is that AI does not exist (not yet anyway). This is machine learning and deeper machine learning and this is prone to HUMAN error. If there is only 1% error and we are looking at about 500,000 movies made, that implies that the movie reference alone will contain 5,000 errors. Now consider this on data of al kinds and you might start to see the picture shape. When it comes to financial data and your advisor is not Sam Bankman-Fried, but Samual Brokeman-Fries (a fast-food employee), how secure are your funds then? To be honest, whenever I see some AI reference I got a little pissed off. AI does not exist and it was called into existence by salespeople too cheap and too lazy to do their job and explain Deeper Machine Learning to people (my view on the matter) and things do not end here. One source gives us “The primary problem is that while the answers that ChatGPT produces have a high rate of being incorrect, they typically look like they might be good and the answers are very easy to produce,” another source gives us issues with capacity, plagiarism and cheating, racism, sexism, and bias, as well as accuracy problems and the shady way it was trained. That is the kicker. An AI does not need to be trained and it would compare the actors date of birth with the release of the movie making The Changeling and What’s up Doc? falling into the net of inaccuracy. This is not happening and the people behind ChatGPT are happy to point at you for handing them inaccurate data, but that is the point of an AI and its shallow circuits to find the inaccuracies and determine the proper result (like a movie list without these two mentions). 

And now we get the source Digital Trends (at https://www.digitaltrends.com/computing/the-6-biggest-problems-with-chatgpt-right-now/) who gave us “ChatGPT is based on a constantly learning algorithm that not only scrapes information from the internet but also gathers corrections based on user interaction. However, a Time investigative report uncovered that OpenAI utilised a team in Kenya in order to train the chatbot against disturbing content, including child sexual abuse, bestiality, murder, suicide, torture, self-harm, and incest. According to the report, OpenAI worked with the San Francisco firm, Sama, which outsourced the task to its four-person team in Kenya to label various content as offensive. For their efforts, the employees were paid $2 per hour.” I have done data cleaning for years and I can tell you that I cost a lot more then $2 per hour. Accuracy and cutting costs, give me one real stage where that actually worked? Now the error at Google was a funny one and you know in the stage of Melissa O’Neil a real Canadian telling Eric Winter that she had feelings for him (punking him in an awesome way). We can see that this is a simple error, but these are the errors that places like ChatGPT is facing too and as such the people employing systems like ChatGPT, which over time as Microsoft is staging this in Azure (it already seems to be), this stage will get you all in a massive amount of trouble. It might be speculative, but consider the evidence out there. Consider the errors that you face on a regular base and consider how high paid accountants mad marketeers lose their job for rounding errors. You really want to rely on a $2 per hour person to keep your data clean? For this merely look at the ABC article on June 9th 2023 where we were given ‘Lawyers in the United States blame ChatGPT for tricking them into citing fake court cases’. Accuracy anyone? Consider that against a court case that was fake, but in reality they were court cases that were actually invented by the artificial intelligence-powered chatbot. 

In the end I liked my version better, Eric Winter is a god. Equally not as accurate as reality, but more easily swallowed by all who read it, it was the funny event that gets you through the week. 

Have a fun day.

3 Comments

Filed under Finance, IT, Science

Prototyping rhymes with dotty

This is the setting we faced when we see ‘ChatGPT: US lawyer admits using AI for case research’ (at https://www.bbc.com/news/world-us-canada-65735769). You see as I have stated before, AI does not yet exist. Whatever is now is data driven, unverified data driven no less, so even in machine learning and even deeper machine learning data is key. So when I read “A judge said the court was faced with an “unprecedented circumstance” after a filing was found to reference example legal cases that did not exist.” I see a much larger failing. You might see it too when you read “The original case involved a man suing an airline over an alleged personal injury. His legal team submitted a brief that cited several previous court cases in an attempt to prove, using precedent, why the case should move forward. But the airline’s lawyers later wrote to the judge to say they could not find several of the cases that were referenced in the brief.” You see, a case reference is ‘12-10576 – Worlds, Inc. v. Activision Blizzard, Inc. et al’. This is not new, it has been a case for decades, so when we take note of “the airline’s lawyers later wrote to the judge to say they could not find several of the cases” we can tell that the legal team of the man is screwed. You see they were unprepared as such the airline wins. A simple setting, not an unprecedented circumstance. The legal team did not do its job and the man could sue his own legal team now. As well as “Mr Schwartz added that he “greatly regrets” relying on the chatbot, which he said he had never used for legal research before and was “unaware that its content could be false”.” The joke is close to complete. You see a law student learns in his (or her) first semester what sources to use. I learned that Austlii and Jade were the good sources, as well as a few others. The US probably has other sources to check. As such relying on ChatGPT is massively stupid. It does not has any record of courts, or better stated ChatGPT would need to have the data on EVERY court case in the US and the people who do have it are not handing it out. It is their IP, their value. And until ChatGPT gets all that data it cannot function. The fact that it relied on non-existing court cases implies that the data is flawed, unverified and not fit for anything. Like any software solution 2-5 years before it hits the Alpha status. And that legal team is not done with the BS paragraph. We see that with “He has vowed to never use AI to “supplement” his legal research in future “without absolute verification of its authenticity”.” Why is it BS? He used supplement in the first, which implies he had more sources and the second is clear, AI does not (yet) exist. It is a sales hype for lazy sales people who cannot sell Machine Learning and Deeper Machine Learning. 

And the screw ups kept on coming. With “Screenshots attached to the filing appear to show a conversation between Mr Schwarz and ChatGPT. “Is varghese a real case,” reads one message, referencing Varghese v. China Southern Airlines Co Ltd, one of the cases that no other lawyer could find. ChatGPT responds that yes, it is – prompting “S” to ask: “What is your source”.

After “double checking”, ChatGPT responds again that the case is real and can be found on legal reference databases such as LexisNexis and Westlaw.” The natural question is the verification part to check Westlaw and LexisNexis which are real and good sources. So either would spew out the links with searches like ‘Varghese’ or ‘Varghese v. China Southern Airlines Co Ltd’, with saved links and printed results. Any first year law student could get you that. It seems that this was not done. This is not on ChatGPT, this is on lazy researchers not doing their job and that is clearly in the limelight here. 

So when we get to “Both lawyers, who work for the firm Levidow, Levidow & Oberman, have been ordered to explain why they should not be disciplined at an 8 June hearing.” I merely wonder whether they still have a job after that and I reckon that it is plainly clear no one will ever hire them again. 

So how does prototyping rhyme with dotty? It does not, but if you rely on ChatGPT you should have seen that coming a mile away. 

Enjoy your first working day after the weekend.

1 Comment

Filed under IT, Law, Media, Science

And the lesson is?

That is at times the issue and it does at times get help from people, managers mainly that belief that the need for speed rectifies everything, which of course is delusional to say the least. So, last week there was a news flash that was speeding across the retina’s of my eyes and I initially ignored it, mainly because it was Samsung and we do not get along. But then Tom’s guide (at https://www.tomsguide.com/news/samsung-accidentally-leaked-its-secrets-to-chatgpt-three-times) and I took a closer look. The headline ‘Samsung accidentally leaked its secrets to ChatGPT — three times!’ was decently satisfying. The rest “Samsung is impressed by ChatGPT but the Korean hardware giant trusted the chatbot with much more important information than the average user and has now been burned three times” seemed icing on the cake, but I took another look at the information. You see, to all ChatGPT is seen as an artificial-intelligence (AI) chatbot developed by OpenAI. But I think it is something else. You see, AI does not exist, as such I see it as an ‘Intuitive advanced Deeper Learning Machine response system’, this is not me dissing OpenAI, this system when it works is what some would call the bees knees (and I would be agreeing), but it is data driven and that is where the issues become slightly overbearing. In the first you need to learn and test the responses on data offered. It seems to me that this is where speed driven Samsung went wrong. And Tom’s guide partially agrees by giving us “unless users explicitly opt out, it uses their prompts to train its models. The chatbot’s owner OpenAI urges users not to share secret information with ChatGPT in conversations as it’s “not able to delete specific prompts from your history.” The only way to get rid of personally identifying information on ChatGPT is to delete your account — a process that can take up to four weeks” and this response gives me another thought. Whomever owns OpenAI is setting a data driven stage where data could optionally be captured. More important the NSA and likewise tailored organisations (DGSE, DCD et al) could find the logistics of these accounts, hack the cloud and end up with TB’s of data, if not Petabytes and here we see the first failing and it is not a small one. Samsung has been driving innovation for the better part of a decade and as such all that data could be of immense value to both Russia and China and do not for one moment think that they are not all over the stage of trying to hack those cloud locations. 

Of course that is speculation on my side, but that is what most would do and we don’t need an egg timer to await actions on that front. The final quote that matters is “after learning about the security slip-ups, Samsung attempted to limit the extent of future faux pas by restricting the length of employees’ ChatGPT prompts to a kilobyte, or 1024 characters of text. The company is also said to be investigating the three employees in question and building its own chatbot to prevent similar mishaps. Engadget has contacted Samsung for comment” and it might be merely three employees. Yet in that case the party line failed, management oversight failed and Common Cyber Sense was nowhere to be seen. As such there is a failing and I am fairly certain that these transgressions go way beyond Samsung, how far? No one can tell. 

Yet one thing is certain. Anyone racing to the ChatGPT tally will take shortcuts to get there first and as such companies will need to reassure themselves that proper mechanics, checks and balances are in place. The fact that deleting an account takes 4 weeks implies that this is not a simple cloud setting and as such whomever gets access to that will end up with a lot more than they bargained for.

I see it as a lesson for all those who want to be at the starting signal of new technology on day one, all whilst most of that company has no idea what the technology involves and what was set to a larger stage like the loud, especially when you consider (one source) “45% of breaches are cloud-based. According to a recent survey, 80% of companies have experienced at least one cloud security incident in the last year, and 27% of organisations have experienced a public cloud security incident—up 10% from last year” and in that situation you are willing to set your data, your information and your business intelligence to a cloud account? Brave, stupid but brave.

Enjoy the day

Leave a comment

Filed under IT, Science

Advanced Ignorance

Yes, this is about AI, the big issue is that it does not exist (not yet anyway), the sales bozo’s are giving you some talk about how it exists and yes the naysayers are right, but they are confusing one version of AI with another. Well part 1, Artificial Intelligence does not exist, it really does not and there is no alternative to this. What you see is machine learning and deeper machine learning and these two parts are AWESOME. They really are, but there is a hidden snag. These two elements rely on data and they are therefor dependent on Human Error and there is plenty. This is seen even today at Google. Now, things happen and errors are seen and at some point they will be corrected for, but until that happens, the machine learning part fails and it will fail a few times.

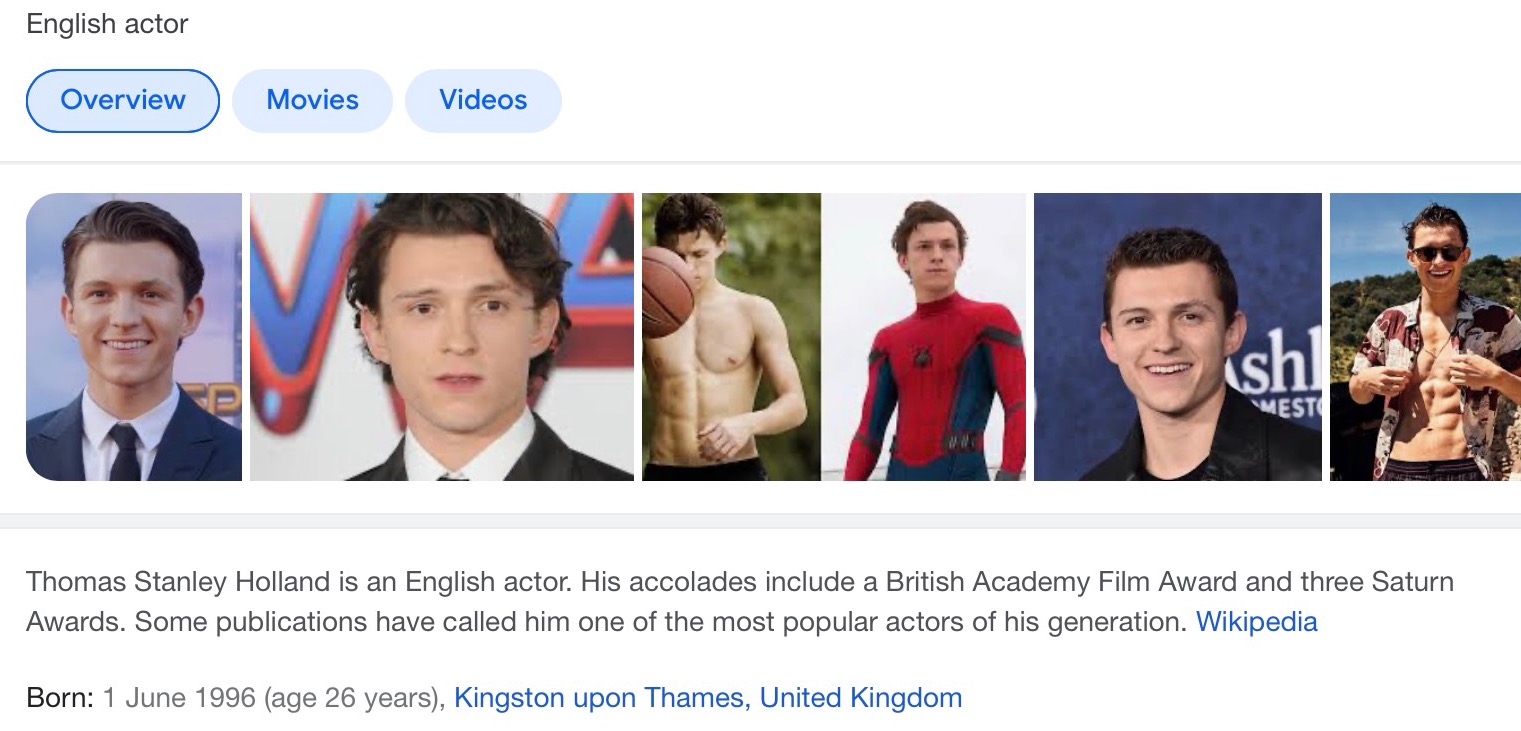
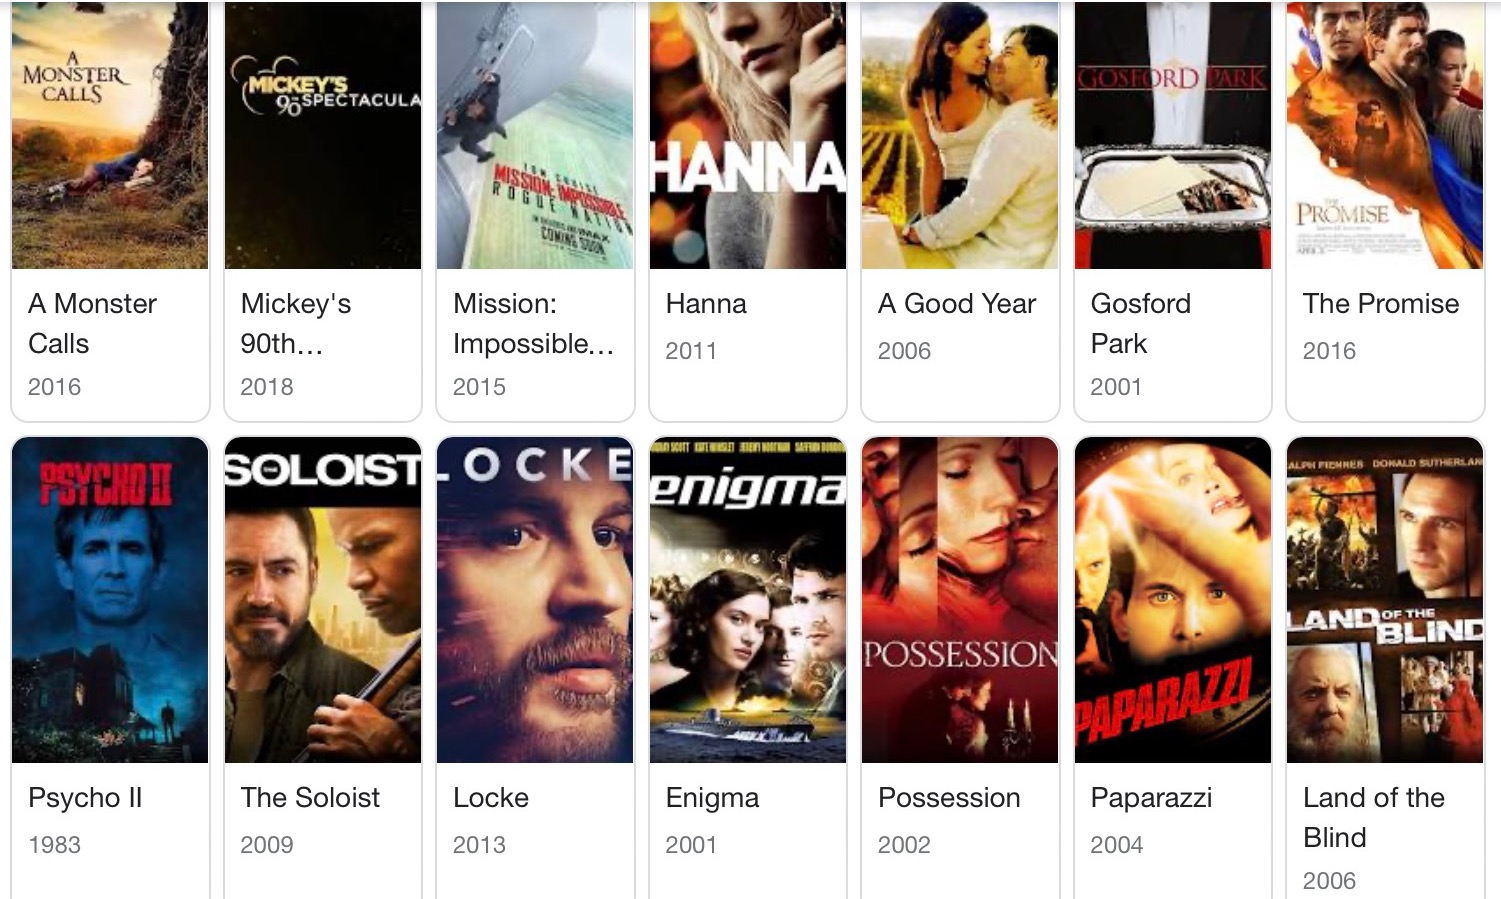
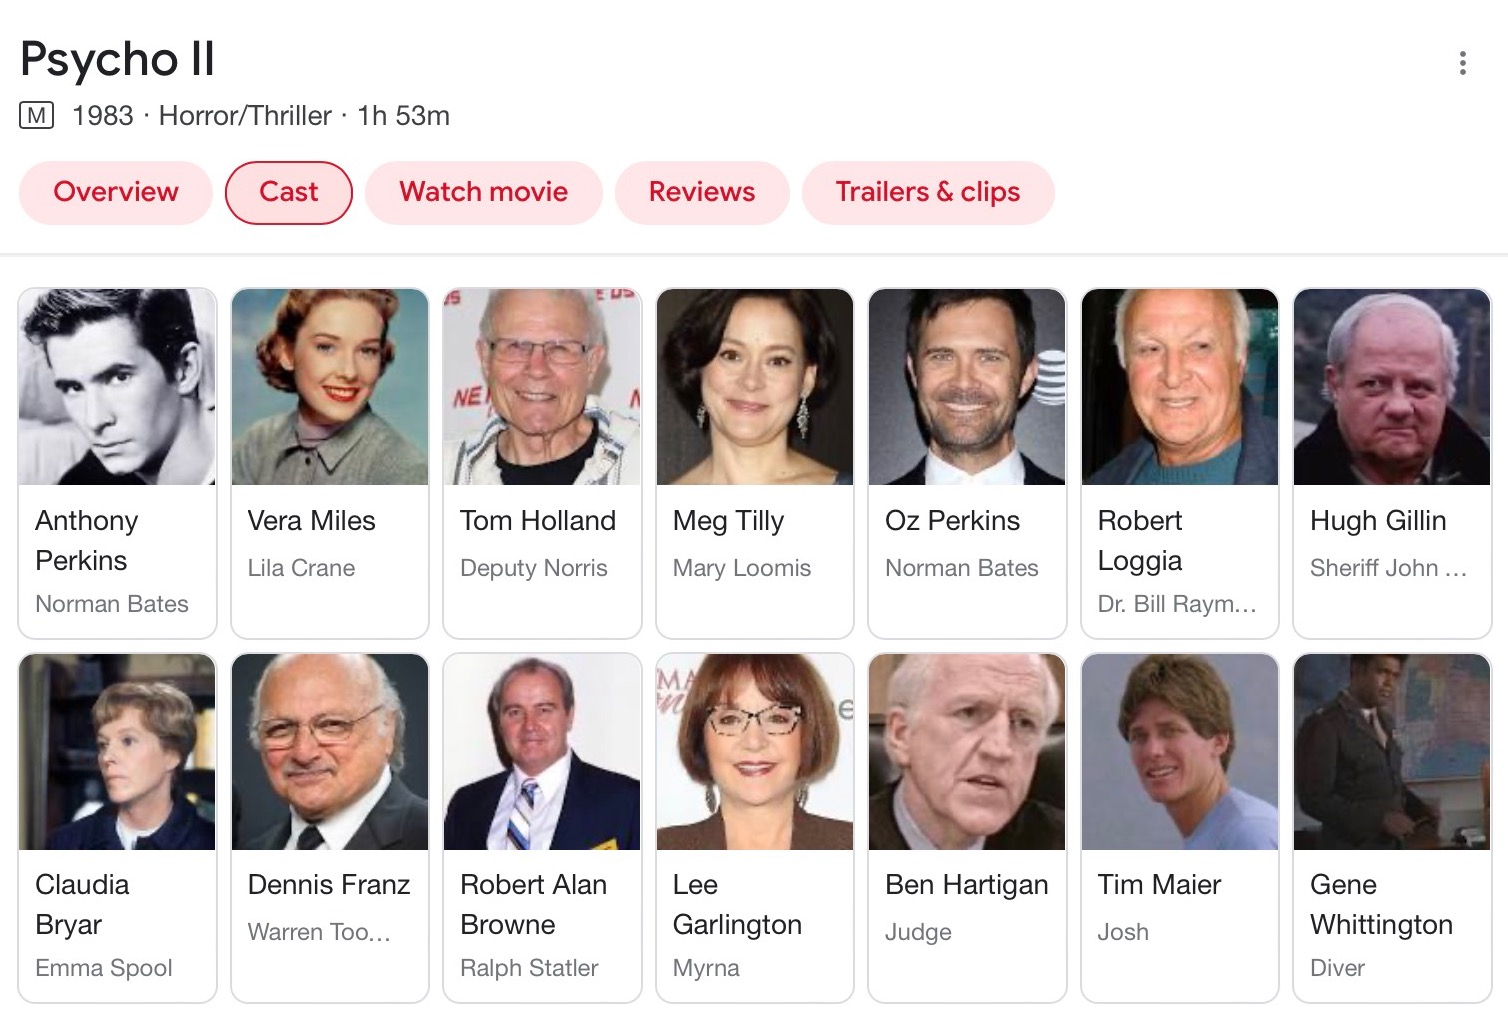
To illustrate this, lets take a look at a British Hollywood giant, namely the actor Tom Holland. Now, there is nothing wrong with this youthful young lad. As image 1 shows above. As you can see he was born June 1st 1996, on the same day as my mother, just a few decades later. He is from (read the pic) and so on, so far so good. I actually had to check something, as such I needed to see his movies. (See below).

Now we get to the good stuff, he did Psycho 2, 13 years before he was born. That makes him a temporal god, which is odd as far as I can tell I am the only one who travelled through time at present, but OK. If I can do it, so could he. And that is where we see the stage, it is seen in the picture below. 

As you can see, there was ANOTHER actor named Tom Holland and he did Psycho 2. But the learning machines never picked it up because the rule to check for errors and movies a person before that person was born did not occur to the software engineer at Google who did this part. Errors will creep in, they always do and there you see the failing of today’s AI when you get one and you might not see it, you will not notice it, because they are rare, but in AI no errors are allowed, they change the outcome of the algorithm and that breaks the AI sooner and sooner. 

This is why I do not trust any AI at present, the minimum stage for AI is nowhere near reaching. It is coming, but I reckon it is t least a decade away. Mainly because ONLY IBM has at present a quantum computer that is required for this and their computer is not ready yet, so at present it is all a version of machine learning which relies on data and it relies on people making the formulas and people are flawed, very very flawed. 

So when you see another AI BS story, feel free to steer clear, AI does not exist and the salesperson who relies on ‘his’ AI story cannot be trusted, he is selling you something that does not yet exist.

Leave a comment

Filed under IT, Media, Science

The theory of new

Before I connect to the story of today which BBC gives us is something from my past. In the 80’s I learned that there are 4 basic stances. Attack, defend, avoid and evade. The last two are not the same. In one we deflect here the attacker goes in the other we avoid where the opponent is expecting to be. It helped me in many of the stages I ever faced. It is the basic of being, that is how I saw it anyway. So these matters were in my mind when an article hit my eyes. It was ‘US-China chip war: America is winning’ (at. https://www.bbc.com/news/world-asia-pacific-64143602), are they? Really?

You see the article gives us “These tiny fragments of silicon are at the heart of a $500bn industry that is expected to double by 2030. And whoever controls the supply chains – a tangled network of companies and countries that make the chips – holds the key to being an unrivalled superpower.” I cannot disagree, but the setting is folly. You see for the most in the last 30 years that industry tried to be everywhere and there is a stage where we see them in many places. But is that a good thing, or can that truly be pushed everywhere? Think of it, think of the stage from let’s say 1996 and now 2023. Electronics got to drown everything else. 

Now lets look at the simple image below

It is an abacus, and it comes from Persia about 600BC, there is enough speculation that they got it from somewhere else and that story goes back to the age of Mesopotamia. What is important is that a person truly versatile in this device can get to a result faster than anyone with a calculator and there is the solution, or perhaps the direction of the solution. The second strap is not what is out today, but what was out yesterday. In the older days we had Microsoft laptops, they outgrew their usefulness, or so that was what Microsoft wanted us to believe. The laptops were too slow, but guess what, those laptops became decently powerful Unix/Linux servers and that was a mere 10 years ago. The old PS3 could be broken into a Linux system, which was surprisingly powerful. They got a new lease on life and that is what we need to do, we need to consider other directions. Yes we see all the bla bla bla on AI and on what a powerful system can do, but guess what? AI does not exist. Machine learning does and deeper machine learning exists too and they are awesome. AI needs a lot more and these parts do not yet exist. In the first a real quantum computer is required and IBM is the closest to getting one. Once they get a handle on shallow circuits and the power is upped, that is when the system exists where a real AI could be, the second part is still a decade (at least) away. A Dutch physicist did find the Ypsilon particle and that is essential to get the shallow circuit truly going, but it is a decade away. You see chips are binary. It is either yer or no and an AI needs the Ypsilon particle. It is Yes, No, Neither or Both and these last two will evolve systems into closer to true AI and we are not there yet. So how does it all fill together? 

That is the core and we see part of that with “The manufacture of semiconductors is complex, specialist and deeply integrated. An iPhone has chips that are designed in the US, manufactured in Taiwan, Japan or South Korea, then assembled in China. India, which is investing more in the industry, could play a bigger role in the future.” This is true, or at least it sounds true, but the real issue is what can be replaced with a chip? You think it is ludicrous, but is it? Do we need them? It is a serious question. You see any new technology is derived from the limits of others and as power is more and more an issue in many places, the idea of exploring the field of mechanical computer is not the craziest. What did we overlook? What did we reject because an American told us that their chip was better? They did it before with VHS, Betamax was highly superior, but VHS had the numbers, it is the only reason they won. So what else did we reject? If an abacus can equal a person with a calculator. A system with a time advantage of 3000 years, what else is possible? We forget to look behind us (which is where I found billions in IP) what else is there and what else could be done? And this is not done overnight, this will take years, decades perhaps but it would result in a new technology stream, one not founded on electronics and guess what, when the power falls away, so do your chips. So is my idea weird? Yes. Is it preposterous? Perhaps. Is it invalid? No! There is enough evidence all over the field and seeking replacement systems is not the weirdest idea, not in this day and age. 

Consider one other system, in the old days (a little past WW2) someone invented the Knijpkap (squeeze cat) the torch had a small dynamo inside which sounded like a purring cat when operated. 

The interesting part is that it needed no battery. So how many torches do you know that have no battery? What happens when batteries are not available? We can add a recharging battery to hold that power, or not. But one device completely without battery. So what happens when we adjust this to other means? These are two simple applications, now consider one where whomever invents it reuses a mechanical computer to take the load away (and revenue) for electronic ones? That will be the exercise and it is not an easy one. It takes one with serious brains and a decade at their disposal. But I reckon the spoils will be so worth it in the end. 

Leave a comment

Filed under Finance, Politics, Science

When one door closes

Yes, that is the stage I find myself in. However I could say when one door closes someone gets to open the window. Yet, even as I am eager to give you that story now, I will await the outcome of Twitter (who blocked my account) and the outcome there will support the article. Which is nice because it makes for an entertaining story. It did however make me wonder on a few parts. You see AI does not exist. It is machine learning and deeper learning and that is an issue for the following reasons.

Deep learning requires large amounts of data. Furthermore, the more powerful and accurate models will need more parameters, which, in turn, require more data. Once trained, deep learning models become inflexible and cannot handle multitasking.

This leads to: 

Massive Data Requirement. As deep learning systems learn gradually, massive volumes of data are necessary to train them. This gives us a rather large setting, as people are more complex, it will require more data to train them and the educational result is as many say an inflexible setting. I personally blame the absence of shallow circuits, but what do I know? There is also the larger issue of paraphrasing. There is an old joke. The joke goes “Why can a program like SAP never succeed?” “Because it is about a stupid person with stress, anxiety and pain” until someone teaches that system that SAP is also a medical term for Stress, Anxiety and Pain” and until we understand that ‘sap’ in the urban dictionary as a stupid person, or a foolish and gullible person the joke falls flat. 

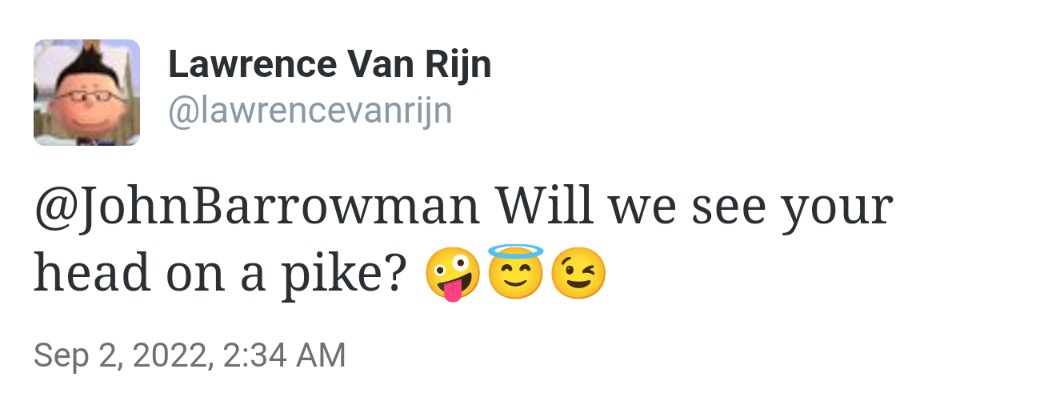
And that gets me to my setting (I could not wait that long). The actor John Barrowman hinted that he will be in the new Game of Thrones series (House of the Dragon), he did this by showing an image of the flag of House Stark. 

I could not resist and asked him whether we will see his head on a pike and THAT got thrown from Twitter (or taken from the throne of Twitter). Yet ANYONE who followed Game of Thrones will know that Sean Bean’s head was placed on a pike at the end of season 1, as such I thought it was funny and when you think if it, it is. But that got me banned. So was this John Barrowman who felt threatened? I doubt that, but I cannot tell because the reason of why this tweet caused the block is currently unknown. If it is machine learning and deeper learning we see its failure. Putting ones head on a pike could be threatening behaviour, but it came from a previous tweet and the investigator didn’t get it, the system didn’t get it or the actor didn’t do his homework. I leave it up to you to figure it out. Optionally my sense of humour sucks, that to is an option. But if you see the emoji’s after the text you could figure it out. 

High Processing Power. Another issue with deep learning is that it demands a lot of computational power. This is another side. With each iteration of data the demand increases. If you did statistics in the 90’s you would know that CLUSTER analyses had a few setbacks, the memory needs being one of them, it resulted in the creation of QUICKCLUSTER something that could manage a lot more data. So why use the cluster example?

Cluster analyses is a way of grouping cases of data based on the similarity of responses to several variables. There are two types of measure: similarity coefficients and dissimilarity coefficients. And especially in the old days, memory was hard to get and it needs to be done in memory. And here we see the first issue. ‘the similarity of responses to several variables’ and here we determine the variables of response. But in the SAP example, the response is depending on someone with medical knowledge and one with urban knowledge of English, and if these are two different people, the joke quickly falls flat, especially when these two elements do not exchange information. In my example of John Barrowman WE ALL assume that he does his homework (he has done this in so many instances, so why not now), so we are willing to blame the algorithm, but did that algorithm see the image John Barrowman gave us all, does the algorithm know the ins and outs of Game of Thrones? All elements and I would jest (yes, I cannot stop) that these are all elements of dissimilarity, as such 50% of the cluster fails right of the bat and that gets us to…

Struggles With Real-Life Data. Yes, deeper learning struggles with real life data because it is given in the width of the field of observation. For example, if we were to ask a plumber, a butcher and a veterinarian to describe the uterus of any animal we get three very different answers and there is every chance that the three people do not understand the explanation of the other two. A real life example of real life settings and that is before paraphrasing comes into play, it merely makes the water a lot more muddy.

Black Box Problems. And here the plot thickens. You see at the most basic level, “black box” just means that, for deep neural networks, we don’t know how all the individual neurons work together to arrive at the final output. A lot of times it isn’t even clear what any particular neuron is doing on its own. Now I tend to call this: “A precise form of fuzzy logic” and I could be wrong on many counts, but that is how I see it. You see why did deeper learning learn it like this? It is an answer we will not ever get. It becomes too complex and now consider “a black box exists due to bizarre decisions made by intermediate neurons on the way to making the network’s final decision. It’s not just complex, high-dimensional non-linear mathematics; the black box is intrinsically due to non-intuitive intermediate decisions.” There is no right, no wrong. It is how it is and that is how I see what I now face, the person or system just doesn’t get it for whatever reason and a real AI could have seen a few more angles and as it grows it will see all the angles and get the right conclusion faster and faster. A system on machine learning or deeper learning will never get it, it will get more and more wrong because it is adjusted by a person and if that person misses the point the system will miss the point too, like a place like Gamespot, all flawed because a conclusion came based on flawed information. This is why we have no AI, because the elements of shallow circuits and quantum computing are still in their infancy. But salespeople do not care, the term AI sells and they need sales. This is why things go wrong, no one will muzzle the salespeople.

In the end shit happens, that is the setting but the truth of the matter is that too many people embrace AI, a technology that does not exist, they call it AI, but it is a fraction of AI and as such it is flawed, but that s a side they do not want to hear. It is a technology in development. This is what you get when the ‘fake it until you make it’ is in charge. A flaw that evolves into a larger flaw until that system buckles.

But it gave me something to write about, so it is not all a loss, merely that my Twitter peeps will have to do without me for a little while. 

Leave a comment

Filed under IT, movies, Science

Altering Image

This happens, sometimes it is within ones self that change is pushed, in other cases it is outside information or interference. In my case it is outside information. Now, let’s be clear. This is based on personal feelings, apart from the article not a lot is set in papers. But it is also in part my experience with data and thee is a hidden flaw. There is a lot of media that I do not trust and I have always been clear about that. So you might have issues with this article.

It all started when I saw yesterday’s article called ‘‘Risks posed by AI are real’: EU moves to beat the algorithms that ruin lives’ (at https://www.theguardian.com/technology/2022/aug/07/ai-eu-moves-to-beat-the-algorithms-that-ruin-lives). There we see: “David Heinemeier Hansson, a high-profile tech entrepreneur, lashed out at Apple’s newly launched credit card, calling it “sexist” for offering his wife a credit limit 20 times lower than his own.” In this my first question becomes ‘Based on what data?’ You see Apple is (in part) greed driven, as such if she has a credit history and a good credit score, she would get the same credit. But the article gives us nothing of that, it goes quickly towards “artificial intelligence – now widely used to make lending decisions – was to blame. “It does not matter what the intent of individual Apple reps are, it matters what THE ALGORITHM they’ve placed their complete faith in does. And what it does is discriminate. This is fucked up.”” You see, the very first issue is that AI does not (yet) exist. We might see all the people scream AI, but there is no such thing as AI, not yet. There is machine learning, there is deeper machine learning and they are AWESOME! But the algorithm is not AI, it is a human equation, made by people, supported by predictive analytics (another program in place) and that too is made by people. Lets be clear, this predictive analytics c an be as good as it is, but it relies on data it has access to. To give a simple example. In that same example in a place like Saudi Arabia, Scandinavians would be discriminated against as well, no matter what gender. The reason? The Saudi system will not have the data on Scandinavians compared to Saudi’s requesting the same options. It all requires data and that too is under scrutiny, especially in the era 1998-2015, too much data was missing on gender, race, religion and a few other matters. You might state that this is unfair, but remember, it comes from programs made by people addressing the needs of bosses in Fintech. So a lot will not add up ad whilst everyone screams AI, these bosses laugh, because there is no AI. And the sentence “While Apple and its underwriters Goldman Sachs were ultimately cleared by US regulators of violating fair lending rules last year, it rekindled a wider debate around AI use across public and private industries” does not help. What legal setting was in play? What was submitted to the court? What decided on “violating fair lending rules last year”? No one has any clear answers and they are not addressed in this article either. So when we get to “Part of the problem is that most AI models can only learn from historical data they have been fed, meaning they will learn which kind of customer has previously been lent to and which customers have been marked as unreliable. “There is a danger that they will be biased in terms of what a ‘good’ borrower looks like,” Kocianski said. “Notably, gender and ethnicity are often found to play a part in the AI’s decision-making processes based on the data it has been taught on: factors that are in no way relevant to a person’s ability to repay a loan.”” We have two defining problems. In the first, there is no AI. In the second “AI models can only learn from historical data they have been fed” I believe that there is a much bigger problem. There is a stage of predictive analytics, and there is a setting of (deeper) machine learning and they both need data, that part if correct, no data, no predictions. But how did I get there?

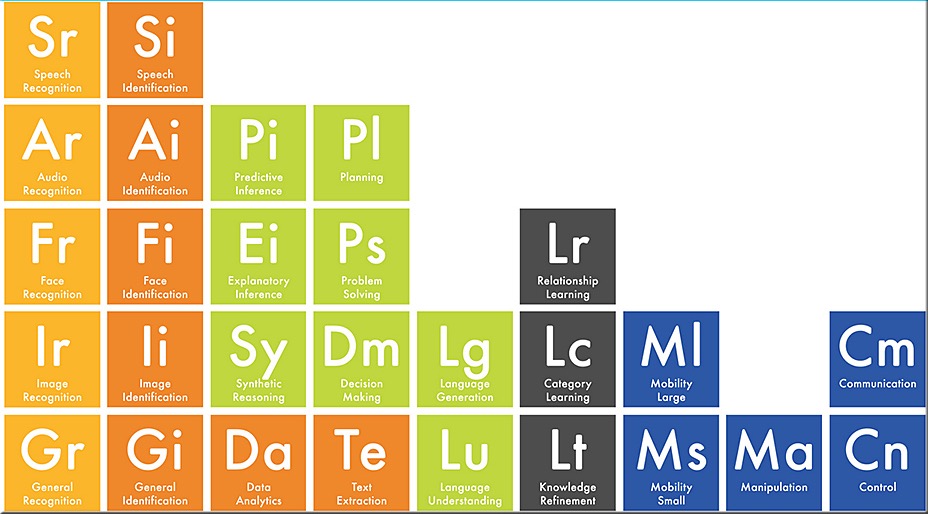
That is seen in the image above. I did not make it, I found it and it shows a lot more clearly what is in play. In most Fintech cases it is all about the Sage (funny moment). Predictive inference, Explanatory inference, and decision making. A lot of it is covered in machine learning, but it goes deeper. The black elements as well as control and manipulation (blue) are connected. You see an actual AI can combine predictive analytics and extrapolation, and do that for each category (races, gender, religion) all elements that make the setting, but data is still a part of that trajectory and until shallow circuits are more perfect than they are now (due to the Ypsilon particle I believe). You see a Dutch physicist found the Ypsilon particle (if I word this correctly) it changes our binary system into something more. These particles can be nought, zero, one or both and that setting is not ready, it allows the interactions to a much better process that will lead to an actual AI, when the IBM quantum systems get these two parts in order they become true quantum behemoth and they are on track, but it is a decade away. It does not hurt to set a larger AI setting sooner rather than too late, but at present it is founded on a lot of faulty assumptions. And it might be me, but look around on all these people throwing AI around. What is actual AI? And perhaps it is also me, the image I showed you is optionally inaccurate and lacks certain parts, I accept that, but it drives me insane when we see more and more AI talk whilst it does not exist. I saw one decent example “For example, to master a relatively simple computer game, which could take an average person 15 minutes to learn, AI systems need up to 924 hours. As for adaptability, if just one rule is altered, the AI system has to learn the entire game from scratch” this time is not learning, it is basically staging EVERY MOVE in that game, like learning chess, we learn the rules, the so called AI will learn all 10(111) and 10(123) positions (including illegal moves) in Chess. A computer can remember them all, but if one move was incorrectly programmed (like the night), the program needs to relearn all the moves from start. When the Ypsilon particle and shallow circuits are added the equation changes a lot. But that time is not now, not for at least a decade (speculated time). So in all this the AI gets blamed for predictive analytics and machine learning and that is where the problem starts, the equation was never correct or fair and the human element in all this is ‘ignored’ because we see the label AI, but the programmer is part of the problem and that is a larger setting than we realise. 

Merely my view on the setting.


Leave a comment

Filed under Finance, IT, Media, Science

IP intoxication

Yup, this just happened to me. I will try to be as clear as possible, yet I cannot say too much. It all started as I was contemplating new RPG IP, not entirely new, it was to be added to the RPG game that I have been giving visibility to on this blog. As I was considering parts in the economy to interact with the play world my thoughts skipped to Brendan Fraser. I was rethinking some parts of Encino Man (with Sean Astin aka Rudy), as well as The Mummy (with Rachel Weisz as Evelyn Carnahan). At some point the mint was drawing a line and even as additional IP came to mind, I ignored it as this would be Ubisoft territory. But the line became and as such my mind saw an interaction that has NEVER EVER been done in RPG gaming before. It would be optionally the stage for Sony, but it seems that streamers (Amazon Luna) had a much better grasp of the option. To get this added in a game would imply that the game would require module of machine learning and deeper learning. Now that is not so odd. A multitude of RPG games have some kind of NPC AI in play (to coin a phrase), but to add this to the character as a side setting has to my knowledge never been done before and the added options would give it more traction towards gamers. There are a few more sides, I discussed that in part in ‘Mummy and Daddy’ (at https://lawlordtobe.com/2021/03/19/mummy-and-daddy/), so well over a year ago (March 19th 2021). There I made mention of “it is basically, to some degree the end of the linear quest person, it is a stage never seen before and I believe that whomever makes that game to the degree we see will make that developer a nice future stage as a new larger development house, and as Micro$oft learns that they lost out again, perhaps they will take the word of gamers against that of business analyst claiming to be gamers.” Additional sides that connect and in this not only has it never been done before, it seems that whomever adds this to their RPG will have additional sides that Bethesda (the company that Microsoft paid $7,500,000,000 for) comes up short on. It feels intoxicating. To have several options in a game that none of the others ever did or contemplated. And now I see that there is more to it all. There is in part a side that touches towards IP Bundle 3 I have, something that could bring Amazon billions (but with a small amount of risk). Yet I never considered it as a side of a game, well to some degree. So as the mind is connecting idea to idea, evolve IP into IP+ and a multitude of IP’s I merely wonder why the others (Google and Amazon) are not on this page already. Google seems to driven to advertise its nest security, Amazon is doing whatever (clothing stores and trying to buy EA), but as I watch the news, and the deeper news that the news will not give us, I see an absence of true innovation in games. In a sense I wonder what is wrong with me, you see I have never been this ahead of any envelope before. 

I tried to explain it in the past. You see there is a side where gaming is, most games are in that ‘light’ circle and the bar is set to the edge. Now there is an area outside the gaming area and that is the area of what is possible, this is where innovation is. the really good games (like Horizon: Forbidden West) are in part there, and they are not alone. The real AAA games are in part there, they are coding there now because it is what will be possible tomorrow, the darker circle is what future games will see as ‘current technology’ that is how games have evolved and that has not changed. I went a step beyond that, I went where tomorrow games are currently not and I set out a slice of gaming heaven and decided to add this to the upcoming technology. There are two dangers. The first is that it has a danger of being delusional. The second is that not all technology can get there. The second one is simple. I see the streamers as a stepping stone to what will be possible in for example the PlayStation 6. A (for the lack of a better term) a hybrid streamer. A fat client client/server application in gaming. One that needs a real power player, but that is not possible UNTIL there is a national deployed 5G network. I believe Amazon Luna and Google Stadia need to get to that point, it is what is required in the evolution of gaming. So there are these two dangers, but is the first danger mine? I do not believe that to be as my mind can clearly see the parts required, but that is the hidden danger of a delusional mind. In my defence I have been involved in gaming since 1984 (connections to Mirrorsoft and Virgin Interactive Entertainment, Virgin Games at the time), so I have been around since the very beginning of games. My mind has seen a mountain of true innovator and innovations. As such I feel I am awake and on top of it. But the hidden trap is there and as such, one can never stop to question your own abilities to avoid falling into the first trap.

But for now I feel intoxicated, and not a drop of alcohol in me, innovation can be that overwhelming. This is why the previous article remains under construction. It has a lot to do with Texas, the ATF and the NRA. I wrote about that before as well and interesting enough the media seems to avoid that side to a much larger degree, with the one or two exceptions I mentioned in a previous article. I wonder why that is. Do you not?  Well time to sign off, snore like a sawmill and get ready for the new day which is already here.

1 Comment

Filed under Gaming, IT, Science