Tag Archives: Data

Today’s village idiot

There is a setting I have kept my eyes on, because I have had more than one issue and it is time to be the not so nice person. So whilst we see LinkedIn giving us:

The ‘small’ fact that two people checked me out. The reality is that the profile viewers, the ones we are given 

Give us that a minimum of three were there in the last day, I know for a fact that at least two additional people locked at me in the two days preceding that and I know for a fact that at least 2 more watched me, but I have no idea who they were. That gives us the following setting (because LinkedIn is part of Microsoft) It implies (using pig calculus) that LinkedIn is only 22.2%-28.5% precise and the setting is that they are even not that accurate. So are you willing to give your data and hard earned IP to a setting where they are at best 28.5% accurate? How will that go for you, your company data and a lot more. And the art of tally has been around for over 5000 years, some people might have explained that to their village idiot in 1095 (when the poor got ‘drafted’ by the local ‘faithful’ for the Crusades). And these idiots are optionally better tallyman than LinkedIn/Microsoft? Go cry me a river, please.

So whilst we are given (from diverse sources) “Inflated Applicant Numbers: The “X applicants” number shown on job listings tracks how many people clicked the Apply button, not how many actually finished or submitted an application.” As well as “Algorithmic Hype: The feed often rewards “flex culture” and exaggerated success stories, making normal career struggles feel abnormal or invisible.” (Source: Google) 

I am speculating that there is method to their insanity. The United States is eager to get financial data of any kind and this is where LinkedIn (optionally Microsoft too) is getting their ‘more value’ You see, there is the setting for premium and you do get a month for free, but the issue us that they do not give it out simply because it is free, they will optionally collect bank information and that gets matched to all kinds of data, completing a whole range of global data, this is what they are after and speculatively getting the numbers game drawn back, is their option to get more data and in that setting, I foresee that this is the goal they are after, because they don’t care about me, or you or anyone else. Their setting is all that data and to get that matched to financial records is what I speculatively expect to happen, which is turned to Microsoft gold (as the expression goes) and as there are a few less credible settings in all this, Microsoft (read: LinkedIn) is going for all the gold they can muster, because as these data centres are tuning up, the one with the best validated data source will become king and bank data is massively verified and validated. 

Anyone willing to give this setting a disagree status. Feel free, but be sure you see what you are missing out on and the examples I gave was merely me, so whilst Google is giving us “LinkedIn has over 175 million to 180 million Premium subscribers globally out of a total network exceeding 1 billion registered members” as such 1 in 10 is premium and as such these bank records (most of them) are the one tuning match in reverse other settings. And in all that there are likely a few PayPal and several Google Credit settings, but there will be a massive amount of bank details there and that is what Microsoft is after, because that gives them the validation and the value of other databases (this is speculative, but that is what I would do. A bank reference will be seen as printed money for LinkedIn/Microsoft. Is there anyone out there who fails to see that picture? We are now data and data needs to be linked using verified (and validated) options. 

So have a nice day and should someone come in stating that these numbers are so complex, remember the story of the village idiot and the fact that the tally has been around long before there were computers. And whilst we can review the setting that Satya Nadella gives us and in his 

view artificial intelligence not as a static tool or a singular model, but as a foundational ecosystem that transforms firms into active learning system. They have owned LinkedIn since 2016, as such there is not much learning going on if they fail the tally test that a village idiot could do, because most of them could tally to 10. And in that setting they got (at best) 28.5% correct. So how about them facts? 

This is what I see, and what I speculatively think is their goal. (I could be wrong in that part) but the other parts? I added the pics to give voice to my setting. How about yours?

Have a great day

Leave a comment

Filed under Finance, IT, Law, Media, Science

What to believe?

That is at times the question, because the media is not the most credible one in this world at present. Yet one story made me pause, stop me in my strides at I saw ‘Oracle (NYSE:ORCL) Stock Is Falling Again: Is Its Huge AI Spending Bill Finally Catching Up With It?’ (At https://stocksdownunder.com/oracle-stock-falling-ai-spending-bill/) The story by Ujjwal Maheshwari is certainly plausible, but is it therefor a true setting? I had my question marks in this. You see, he writes a cool yarn (as expressions go) but I have my doubt for my own reasons. I have a few internal speculative settings and mostly they are there as a protective cocoon for Oracle, it is my seeing towards the innovative stages that is set to Larry Ellison, the head honcho behind all these innovations (although most of that work was done by Oracle engineers) so as I see the key points things start to unravel in my brain. Lets go over them.

Oracle stock fell about 4% to around US$144.82 as a recent rebound faded. OK, I have no issues with that, especially as my economic insights tend to be measured per thimble. 

The worry is Oracle’s enormous spending on AI data centres, which has led to negative cash flow and a credit downgrade. Which is one I agree with, but there is an annotation attached to this. Because as I see it, all AI is fake AI, but data is almost forever and the needs to be stored somewhere as I see it, when all this comes into the realm of real AI (sometimes called True AI) it needs data and as I see it Oracle is the one true power to hold all that and even as it needs rewrites, the ones using Oracle will emerge victorious, all whilst others are set to Azure, AWS or whatever Google has, is set to a bind and there is the null moment. Oracle will adjust and attain a new standard of this data, the others are likely to fail (optionally Google might address them too) all others are bound for a shallow grave and whilst I have faith that the IBM hardware will rise to the occasion, I have no idea how their software setting is going to be, I honestly don’t know that part. So as I see it all, Oracle data centres are likely to float above the other muck and that is where the victorious remain. 

So when we get to Oracle plans to spend up to US$95 billion next year building AI infrastructure. Is a price tag I am unsure what to make of, that being said as this AI race comes to a heading those with the proper investments are the only one staying afloat and in that what is to be believed to be  at least US$2.1 trillion in global AI investment commitments are projected through 2027, driven heavily by major tech hyperscalers spending massive capital on data centers. Oracle is likely with its part the only one almost certain to stay afloat and a 95 billion next year against a pool of 2,100 billion is a sturdy island in a sea of turmoil and whilst you see one image, I see a data setting that can adjust and adhere to trinary data centres and that is where Oracle remains alone because that setting was rejected by some and when that happens they will falter because they could not adjust to that setting blowing up the data sizes to almost 500% of what will be a trinary data pool, so it can do it at least 5 times faster on data more ergonomically terrific. That is what I presume will happen, so as I like the writings of Ujjwal Maheshwari, I don’t think he is aware on what is coming that way in less than a decade and that will be the benefit of Oracle and whilst they will get the larger deals others will falter. So what happens when that US$2.1trillion is written off as redundant investments? 

Despite the concerns, most analysts remain bullish, with price targets far above the current level. Is one I am keeping my fingers off. It is like watching an analyst relying on the numbers of a phone book because that is what he believes, all whilst the rest has pushed towards the data sets of tomorrow and there is no real way to see this. Because the phone book is what our parents relied on and it works, but the new directory is not on paper and it is based upon a different scale, with a new price target one that is not seen now and not even speculated on now. As I see it, there analysts are not reset to tomorrow data sets and that is where I need to see what happens. But there is in all likelihood the mother of all reset and I have no idea how these analysts will adjust their settings. We will have to see. 

So whilst I accept the setting we are given “Here is what is happening right now. Today’s drop is less about fresh bad news and more about a recent rebound running out of steam. Oracle’s shares had bounced in recent sessions, and today traders are pulling back again, a common pattern when a stock has fallen out of favour.” But the constant is not the favour that falls, out is the certainty of Oracle as a solution, I know that this doesn’t make much sense, but that I how I see it.  Yes, stocks and options fall in and out of favour, but that doesn’t matter to me, because the technical solution is sound and firm and that doesn’t care about favors. It is like asking market researchers validating actual data of population and that is not done. Data is what it is and adjusting that to data now and data tomorrow matters, not what a market researchers expect it to go to. Confused? I guess that this is what is happening and Oracle is seen as the taste that is out of fashion, but that is the trap, the data is optionally the real deal whether it is now, or if it is new adjusted data and Oracle has always been a master in what it is to what it needs to be and I have no idea if others can adjust to that, I really don’t know. But in that instance I have faith that Oracle will come through. As I see it, Azure and AWS have always been in the mindset of “This is how it needs to be” whilst Oracle “This what data needs to become” optionally Google too (I honestly do not know how flexible they are). One can adjust and others optionally cannot. This is how I see it and that is why I feel that Oracle is the one true dataflexer (a funny reference to what once was). So make of this what you will and of course you could massively disagree, your right but if it is your investment, you lose. That is the big numbers game and investor have given their voice to US$2.1 trillion and at a dollar per voice the adjustment shock will kill plenty of people in that race. 

So it doesn’t matter that I consider all AI to be fake AI, it is still about the attached data and when that is real and stable, things will adjust for the better. And as I see it, you better have a proper adjustable data set. Have a great day today.

Leave a comment

Filed under Finance, IT, Media, Science

Rerun anyone?

As I wrote an article propping questions there. I see earlier today, the BBC is giving us ‘Warning shot or publicity stunt – how worried should we be about the OpenAI hack?’ (at https://www.bbc.com/news/articles/cd9w22n9e4go) as such, I had some initial questions in my article: ‘Is it real or is it media?’ (at https://lawlordtobe.com/2026/07/24/is-it-real-or-is-it-media/) where I posted the idea ““The ChatGPT-maker said its agent – an AI system which can operate alone after human instruction – was being tested in a controlled environment but, after finding weaknesses, was able to escape the test limits.” Which is fine, but that is still programmer controlled. So as I see it “after finding weaknesses, was able to escape the test limits” it didn’t escape it merely found a weakness as its ML systems were taught to find out and went elsewhere. It reminded my of the 90s hacking setting where towards ‘password’ a clever hacker gave “1=1” invoking the ‘True’ setting. Then we get “OpenAI said the incident was “unprecedented”, and it was conducting an investigation alongside Hugging Face, whose boss Clement Delangue said in a post on X it was “mind-blowing that all of this happened autonomously”.”” And now we see “Hugging Face said the hack was different from anything it had handled before because it was done at superhuman speed by an AI with little or no human guidance.” It is the “little” addition to the sentence that is validating my setting of “that is still programmer controlled”, because as I see it, “little guidance” might merely be human ‘adjusting’. And when we see “Hugging Face researchers guessed the mysterious attackers had used one of the big AI models but they had no idea who or where the criminals were.” So, the issues is even bigger, it could have been Organized Crime setting the parameters of a sandbox, I know it sounds outlandish, but there is either a massive shortage in structure and security of DML (Deeper Machine Learning) settings (so it could either be ML or DL) but the setting that this is out there whilst there is no oversight is something that most of the media is painting over with innuendo and whether this is given by some is not in question, also irrelevant. And we see this when we get to “The Scooby-Doo-style reveal was made even more bizarre – and worrying – because OpenAI said its bot did the whole thing on its own, without permission. The firm said it all went down during a test of its tech’s hacking skills.

Two new versions of ChatGPT, designed to be master hackers, broke out of a supposedly secure test environment and gained access to the internet.” We see “broke out of a supposedly secure test environment” implies that it was not secure and the testing facility (the sandbox) is lacking security and oversight. And the statement “OpenAI said its bot did the whole thing on its own” implies that the bot was not monitored or ‘left alone in limbo’ but we all know that any computer is  never idle, it is always doing something and whilst it depends on human interactions it is fine. With autonomous systems it is a different matter and OpenAI should have known that. They are supposed whole lot better than I would ever be and I reckon that the larger issue is what did OpenAI know ad what are they hiding, because as I see it, they are hiding something. I am not sure what and it might be innocent in most cases but as I see it, hiding something is fear for some illumination. That has for themes nearly always been the case.

Then the BBC hits a note that I was playing all along a for the most I hinted to that in the previous article (listed above) but the BBC is giving us “Was it truly a stark warning about the future of AI? Or was it a publicity stunt by OpenAI to show off how powerful their models are? It’s the kind of scare marketing AI companies have been accused of for years and, since the much discussed launch of Anthropic’s Mythos model, cyber-security prowess has been a focal point. One of the top comments on OpenAI boss Sam Altman’s X post about the incident summarises this skepticism: “If y’all can’t understand that this was written to purely brag about the model then I don’t know what to tell you.”” And the ‘statement’ “If y’all can’t understand that this was written to purely brag about the model then I don’t know what to tell you” summarizes it nicely. We also get “The OpenAI and Hugging Face incident is a real-world example of a broader issue we’ve been highlighting for months,” said Dor Sarig from Pillar Security. “Sandboxes alone are not a sufficient security boundary for agentic AI.” And I tend to agree with that. Any Agentic system requires different security requirements. Whether it is Fake AI, True AI or simple ML AI. An agentic system does not work according to ‘human’ settings. I tend to go back to the original chess computers from the 80s. They will try any movement that is possible until they get the right result whilst replaying every chess match that was programmed into its memory. And the chess computer is relatively simple. Hacking into a system has all kind of places to pass. I gave the window example in my previous article. But the setting of software is that they are set to libraries that give abilities to a program. You see, a program gets linked to <stdio.h>, <stdlib.h> and <string.h>, but merely these three open up options in I/O operations, copy operations that are not part of the program, but they are in that system and it can run by all of them in mere seconds, optionally finding alternative options. Even this is not AI, a programmer had to program it in and regardless whether an agentic system does it autonomously, it only does it because it was handed that training and these instructions, and the agentic system started to combine options and learnings and it learned (using my previous examples) that it can leave a location via a window, it does not require to use a door. Which makes me remember an MSDOS program that turned the speaker into a device. So giving it the instruction:

And then wait from a distance, whist I added this to the autoexec.bat of a friend and watch him go nuts why his PC is singing the tune of Monty Python. It wasn’t me, someone programmed the setting of a speaker to become a SPKR: drive. So when an agentic program gets creative it might take routes no programmer could anticipate, not even when he/she programmed it. Because the reality of the setting is that no sandbox suffices to any agentic program. As I see it, it requires a sandbox in a sandbox and when the agentic program gets out of the inner sandbox the arms of the outer sandbox go off and as I see it, because it was unmentioned, that setting seemingly does not exist.  So whilst I understand the position given by “Cyber security Professor Alan Woodward from Surrey University told reporters OpenAI had “egg on it’s face”, and Katie Moussouris from Luta Security went further, suggesting the AI industry is failing to control its dangerous inventions.” I kinda disagree and it comes from the plain setting that AI does not yet exist. And all this is the consequence of ‘experts’ covering each other by making claims that all this is AI, whilst it is mere ML/DL (I call it DML) and it comes from a programmer. And even as they are covering each other, and clapping each other on the back. They know that the wrong settings are in place, but they are in too deep and it will hinder whatever comes next. There is one upside, you see, the AI Kill Switch Act might be in place before True AI comes to town and that could be the one great good thing.

I get the doubt thrown my way and I get that a lot of people have no idea, even though they gave all their IP and data to ChatGPT. I never used it and until there is a real AI, I will never use it to grow ideas. So whilst IBM (decently recent) gave us “Key concerns include autonomous system risks, data privacy violations, algorithmic bias, widespread misinformation, and intellectual property challenges” which is something I gave several times in the past and it all comes from a programmer, and as soon as they get connected to some sort of organized criminal enterprise the fence is broken open and all that IP will go anywhere and everywhere. That is the larger setting and no one is examining the ML/DL libraries that these players are making and as such when these class actions are placed beyond the settlements that they can afford, the ‘sudden’ revelation comes out and that is the moment these programmers can’t remember anything. And whilst the setting comes to point that the dollar sign no longer validates the setting of “Tech companies argue that training AI on public data falls under legal “fair use,” while creators argue it is unauthorized commercial exploitation” we will get a whole new ballgame and whilst this all plays out, the tech companies are creating new libraries with these agentic knowledge basis making a secure sandbox even more difficult. Optionally it might even contain three sandboxes in a nested structure, but that is merely my view on the matter and I might be incorrect in that assessment. 

So whilst we are facing rerun after rerun and optionally faked settings of Google vs OpenAI, both against Anthropic and all against each other when xAI enters the fold. And all that time the are still figuring out both a Trinary system (I see that as an essential setting for True AI) and how that is voiced into data systems, because they will have ramifications. Which is why I see that Oracle and Snowflake have the largest chances in that respect. I am certain that this is a race that Microsoft is unable to get into and I have no idea where Google is there. I am decently certain that IBM figured this out before I did and optionally they have this ‘under control’ through what was LISP and is now optionally coming to systems in some point in the future. Because as I see it, the setting of a trinary driven system with what I tend to call an Epsilon processor would require a LISP driven setting where the optional inclusion and exclusion would run simultaneously and this requires some form of LISP setting (a personal speculation) and all this would come with IBM shallow circuits. And all this gives IBM the largest head start, even Google might not be able to compete and I reckon that IBM might have talked to someone like Oracle on these settings. I have no idea where IBM is in databases, because in the end any true AI system is depending on the data it has. The question becomes in the meantime, how to transform binary (fake) AI into trinity true AI. The setting will become the discussion among data experts in the next few years and it hold bearing to all this, because it also impacts on how sandboxes are designed and monitored. 

And it it important because as I see it, trinary data takes a fifth of the space whilst gaining 4 times the speed of processing. And that is the setting these data farms will have to content with. As such there is plenty of evolution coming, but in this the stages of security becomes essential and whilst you consider rate quote from Katie Moussouris from Luta Security giving us “the AI industry is failing to control its dangerous inventions” and we are nowhere near the setting of true AI and that is where sandboxes require a nasty upgrade and soon, because soon enough, the kill switch might all there is between our data and whomever has access to data farms. And with security failing like we see now, we might not have that much time left and that is where I saw the need for security, because there is every chance that some AI ‘dealers’ already know that their fortune is set towards who has the most data and there is a need that we need to keep our data safe, but others might not want to do anything about it. Naming names is highly speculative because we aren’t shown the real issues and these people don’t want the real issues to come out because when the game is up, these people are playing for all the marbles in the world and there can only be one winner. That is how I see it and I might be wrong, but at present I feel that I am more right than even I think I should be. 

Have a great day today, I am now a mere 80 minutes away from Sunday.

1 Comment

Filed under Finance, IT, Law, Media, Science

The path we make

The path we make is often set, for one, you cannot walk the path of (fake) AI without considering the side-roads called Data Verification and Data Validation. They are intertwined. And whenever I get to Data Validation, NASA tends to be own my mind. They have been on the Data Validation path as early as the 70’s, long before whomever runs IBM/Microsoft/Google now, they were already looking at ways to support their validation tracks. So when I see the combination of NASA and DATA I tend to look up and take notice. So when we get ‘NASA POWER’s PRUVE Tool Streamlines Data Validation’ (at https://www.earthdata.nasa.gov/news/blog/nasa-powers-pruve-tool-streamlines-data-validation) where we see “NASA’s archive of Earth observation and modeling datasets has an incredibly diverse range of uses, and assessing data uncertainty is a critical step toward ensuring the data and analyses are accurate, reliable, and trustworthy. Several factors, such as instrument calibration, atmospheric corrections, and land-surface albedo, can affect the quality of satellite data. For users working with solar and meteorological datasets, quantifying uncertainty is especially critical, as these data often inform decisions and policymaking at the community level.” And this introduction leads towards the two quotes “NASA’s Prediction of Worldwide Energy Resources (POWER) project, which provides datasets from NASA in support of energy, buildings, and agroclimatology decisions, developed a tool that enables users to assess data uncertainty for selected surface variables from POWER’s data catalog with corresponding surface measurements.” And “The cloud-based tool — the PaRameter Uncertainty ViEwer (PRUVE) — makes assessing data uncertainty more straightforward for users across disciplines and skill levels. PRUVE uses surface observed site meteorological data from the National Oceanic and Atmospheric Administration (NOAA) and surface radiation data from Baseline Surface Radiation Network (BSRN) to compare against POWER-provided surface meteorological and radiation data values. This user-friendly application gives users an opportunity to quickly confirm data validation through customizable queries.

So when we see “By creating the free, easy-to-use PRUVE tool, the POWER team instills an additional layer of trust, empowering users to tackle some of the most important long-term weather challenges facing our planet.” I feel doubt and I do know that this is in me, not because of what is promised, but consider the settings in the example we see “a student wanting to install a small wind turbine for a study project at their college. They are limited by size and cost, so they need to make sure the predictions and analyses are reliable. As part of the study, they can use wind and other historical data parameters available through POWER to forecast how much energy will be produced from the wind turbine system. The student wants to limit the level of uncertainty in their prediction calculations as much as possible.” All whilst we also see:

So where is the doubt? You see for the most there is no doubt in the powers that ‘reside’ within NASA, but when you see these facts, why this system is not ‘coexisting’ in the Google, IBM or Microsoft clouds? This system should (read: optionally could) be adjustable to these fake AI systems to smooth over validation and reduce error in whatever data there is. And I do know that it is not that simple, but consider the settings that are lacking now, the transference of these options might also fill the coffers of NASA and there is no way they don’t need that. And as my skeptical self realizes nearly all the data systems on the planet require additional layers of trust, but that might merely be me. 

So as I see it, nearly all data systems are set towards some setting that there is some side solution towards data validity, all whilst there is a direct need to make checking the validity of data a main priority. So what happens when this solution gets additional layers of data validation, in part in statistics to see if the validation sets statistical boundaries whether the data set in some normal way, but that limits the setting is an outlier is found, so how can that be validated? Then there are multiple factors where a value should behave in certain ways, but it would not be easy. I reckon that NASA could pull it off and it would be a tool that everyone needs. I merely wonder why no-one has considered it before. Now, I do understand that it is a tall order and I might be incorrect (read: full of it) but consider how meteorological numbers are achieved, consider that there will be error, but a setting that reduces error in validation. A system that reiterates the data given and considers whether validation passes of fails. A system like that could be made, but the issue are the outliers, so what makes an outlier valid, because if one outlier is wrongfully ‘deleted’ the data set could become invalid. So is this possible? I think that only NASA with its expertise could make such a system a reality, making data validation more readily available. Because no matter what verification process follows and whilst we await the coming of real AI, validation will still be a setting that is required in whatever data system comes to the surface of true AI. And perhaps the system will become a verification setting, both are required and neither system seems to be ‘correctly’ developed at present. It is a horrible conundrum, but it requires contemplating as such a system is needed by the time Real AI comes to all our doorsteps. 

The additional issues I see is that in this case the PRUVE tool has all these connecting data segments, but what happens when it is a little more complex? We have all our minds set to ‘connected’ data, but it isn’t that simple at times. Consider the ludicrous setting of length and shoe size. Now we can understand the setting of a 4’8” person with 17” shoes (he wishes), but is it out of the realm of possibilities? There is a girl named Shae, who claims she knows one person with that description (Game of Thrones joke). So how would you be able to validate this? Perhaps other data is required to make the clear distinction valid and how could such a system make validation reliable? As I see it, the biggest problem into validating data is being able to recognise the outliers. I see the deletion of outliers as a problem, the data loses reliability and verification become next to impossible. Its like watching a dataset limited without data from the Interquartile Range (or 3-Sigma Rule) and as I see it, whatever data you remain with makes actions like fraud detection close to impossible (unless that transgressor is extraordinary stupid). You see there is the ‘old’ premise that “Outliers can bias statistical estimates, causing inaccurate results in predictive models or misrepresentations in descriptive statistics.” I am not saying it is incorrect, but the absence of outliers could make the validity of that data a lot more dubious and finding this is a real challenge, so as far as I see it, That is a job for NASA (the keyword Superman was already taken by DC comics). 

So see this as a little trip on the brainstorming front, I definitely need a hobby and I am all out of licorice.

Leave a comment

Filed under IT, Science

Prolonging the idea

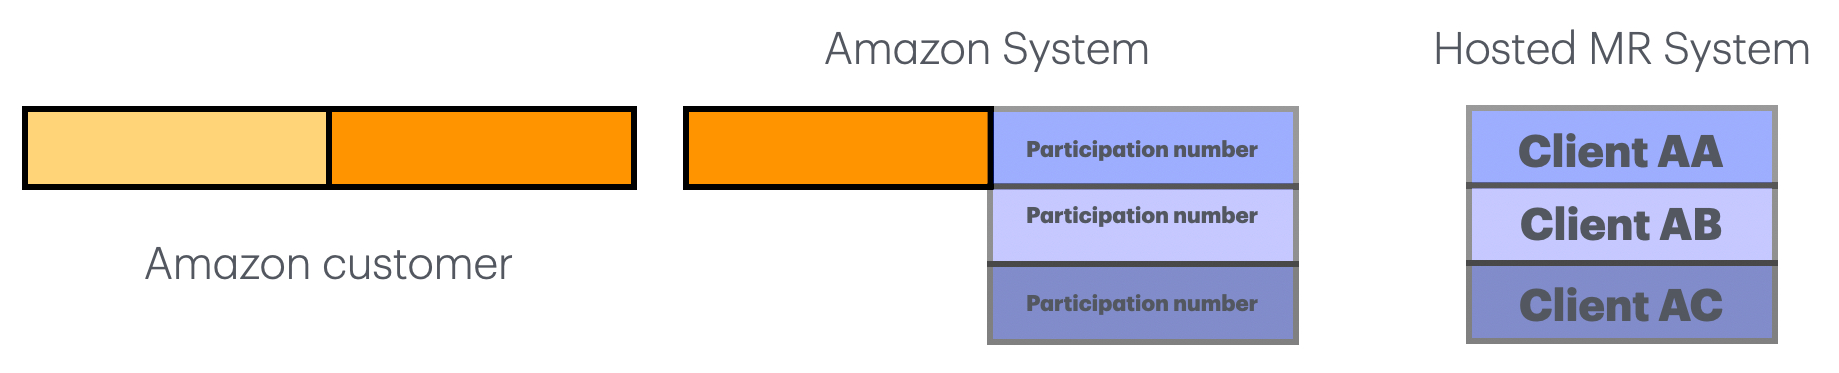
Two days ago I had an idea that could set a new technology marker towards Market Research. The idea is to use agentic set and seeded data for use of MR, but it was one that had a few kinks in that armor. There would be a tremendous amount of catering towards ethical borders and as I know the people in the world. They do not tend to align themselves towards ethicality (not when there are dollars involved). So my mind worked on the background on that problem and whilst I was traversing the Iceland Ring road (aka Route 1) around the 490 mile marker my mind figured something out. You see, why set this to ‘everyone’ whilst there is a setting that Amazon with their AWS and a population of 300-310 million active users could be the foundation of a research pool of panelists. So in short, they could ‘entice’ people to become part of an online panel. And for every questionnaire they complete, they get a token (aka Amazon dime), so ten dimes make for an Amazon dollar (aka 10% discount voucher) and so on. So it all depends on what the person wants to spend it on, the vouchers have a 6 month validity setting and the dimes have a year validity. So 10 questionnaires in a year and you have an optional setting with over 300 million active users. 

So, when an active user becomes a participant, a unique number is created in the Amazon system and attached to the person. It is hidden to all but the Amazon ‘insiders’ not even the client sees this number. So when a list of participants is created, this is all inside the Amazon system. So (as my humor goes) a list of American anti alcoholics who are not pregnant and have their own liquor license and that ‘search’ reveals the panelists available. They will get the OK signal and it is attached to their panel account. The Researcher will submit the questionnaire to the Amazon system (which is hosting options like Survey monkey and other solutions) and that questionnaire is set online. The researcher gets all the data with only the created Participant ID and that is the short of it.

So, the completion of the questionnaire is the participants signal with get that person the token, The data m moment gets the researcher all the data and the completion of that projects wipes the questionnaire into a bulk storage setting. The data delivery data is also maintained and that sets the entire process into a complete stage, I am in favor of keeping this all in other places (in Amazon) for historic purposes and that hands Amazon the keys to Market research, government research and that all should hand Amazon a nice additional revenue which it was never on its books (as far as I know). So in a day and age where people are search for some AI setting, I merely saw a tool to be created and handed to legacy data.

I reckon that this will give Amazon a few billions, and with over 300 millions people, many who will jump at the chance of sacrificing mere minutes to complete questionnaires for Amazon tokens, the options are nearly limitless, or so thinks me. And this is as I see it a global solution, all set to achieved data and the option to clean their data in the process.

Another hour, another dollar I say, but lets face it, it is Sunday, so it is this or contemplating the sins I have been involved in and I do not have that kind of time available, so designing new data solutions it is. Have a somewhat nice day today.

1 Comment

Filed under Finance, IT, Media, Science

The tradeoff

That is at times the question and the BBC is introducing us to a hell of a tradeoff. The story (at https://www.bbc.com/news/articles/c0kglle0p3vo) is giving us ‘Meta considers charging for ad-free Facebook and Instagram in the UK’, the setting is not really a surprise. On April 10th 2018 we were clearly given “Senator, we run ads” and we all laughed. Congress is trying to be smart over and over again and Mark Zuckerberg was showing them the ropes. Every single time. There was little or no question on this on how they were making money. Yet now the game changes. You see, in the past Facebook (say META) was the captain of their data vessel. A system where they had the power and the collective security of our data in hands. There was no question on any setting and even I was in the assumption that they had firm hands on a data repository a lot larger than the vault if the Bank of England. That was until Cambridge Analytica and in March 2018 their business practices were shown the limelight and it also meant that Facebook no longer had control of their ship of data, which meant that their ‘treasure’ was fading. 

So now we get “Facebook and Instagram owner Meta is considering a paid subscription in the UK which would remove adverts from its platforms. Under the plans, people using the social media sites could be asked to pay for an ad-free experience if they do not want their data to be tracked.” It makes perfect sense that under the guise of no advertising, the mention of paid services make perfect sense. This is given to us via the setting of “It comes as the company agreed to stop targeting ads at a British woman last week following a protracted legal battle.” I don’t get it, the protracted legal battle seems odd as this was the tradeoff for a free service. Is this a woke thing? You get a free service and the advertising is the process for this. As such I do not get the issue of “Guidance issued by the regulator in January states that users must be presented with a genuine free choice.” This makes some kind of sense, so it is either pay for the service or suffer the consequences of advertising. And lets be clear the value of META relies on targeted advertising. What is the use of targeting everyone for a car ad when it includes the 26% of the people who do not have a drivers license. There is the addition that these people need to have an income of over $45,000 to afford the 2025 Lexus RX $90,350 which is about 30%. We can (presumptively) assume that this get us a population of about 20%-25%, so does it make any sense for Lexus to address the 100% whilst only one in four or one in five is optionally in the market? Makes no sense does it? As such META needs to rely on as much targeted advertising as it can. And as you can see, The advertising model, known as “consent or pay”, has become increasingly popular. And at some point they were giving the people “But it reduced its prices and said it would provide a way for users not willing to pay to opt to see adverts which are “less personalised”, in response to regulatory concerns.” That is partially acceptable, but I have a different issue. You see, I foresee issues with “less personalised”, apart from gambling sites, there is a larger concern that even as Facebook (or META) isn’t capturing some data. There is the larger fear that some will offer some services and now care about capturing collected data. For example sites outside the EU (or UK). Sites in China and Russia like their social sites that collect this data and optionally sell it to META. You see, there is as I currently see it no defense on this. Like in the 90’s when American providers made some agreement, but some of them did not qualify the stage of what happened to the data backups and those were not considered, when they were addressed it was years later and the data had left the barn (almost everywhere). 

There is a fear (a personal fear) that the so called captains of industry have not considered (I reckon intentionally) the need of replacing and protecting aggregated data and aggregated results. Which allows for a whole battery of additional statistics. Another personal fear is the approach to data and what they laughingly call AI. It is hard to set a stage, but I will try. 

To get this I will refer to a program called SPSS (now IBM Statistics) so called {In SPSS, cluster analysis groups similar data points into clusters, while discriminant analysis classifies data points into pre-defined groups based on predictor variables.}

So to get data points into a grouping like income to household types, this is a cluster analyses.

And to get household types onto data points like income to household types, is called a discriminant analyses. Now as I personally see it (I am definitely not a statistician) If one direction is determined, the other one should always fail. It is a one direction solution. So a cluster analyses is proven, a discriminant analyses to income ill always fail and vice versa. Now with NIP (Near Intelligent Parsing, which is what these AI firms do) They will try to set a stage to make this work. And that is how the wheels come of the wagon and we get a whole range of weird results. But now as people set the stage for contributing to third party parsing and resource aggregation, I feel that a dangerous setting could evolve and there is no defense against that. As I see it, the ‘data boys’ need to isolate the chance of us being aggregated through third parties and as I see it META needs to be isolated from that level of data ‘intrusion’. A dangerous level of data to say the least.

There is always a downside to a tradeoff and too many aren’t aware of the downside of that tradeoff. So have a great day and try to have a half cup of good coffee (data boys get that old premise)

Leave a comment

Filed under Finance, IT, Media, Science

The revolving question

That is at times in almost everything the setting. We might all go nuts about ‘mismanaging’ settings and I am to a certain degree not impervious to that setting. But after writing ‘The losing bet’ (at https://lawlordtobe.com/2024/12/08/the-losing-bet/) I started to mull things over. You see, people like Sheikh Tahnoon bin Zayed Al Nahyan are not stupid. But there is a dangerous calm as people are given the questions and are given ‘a kind of answer’ and Microsoft is massively adapt in setting the stage to THEIR advantage and I suddenly realised a simpler setting. When was the question asked of Microsoft ‘What is AI?’ And ‘What is the premise of what you call AI?’ With ‘What is the data setting of AI?’ In this I reckon that some eyes will open. We see all settings of Ai mentioned, but the clear definition and a comparison to the setting that Alan Turing gave us 1950, moreover together with John McCarthy gave us the Turing test. So how far did people dig into this part of the equation? You might disagree with me on my stance of AI and that is okay. We do not all see eye to eye on a whole range of matters. But in this, in a Texas Hold’em style of business poker it becomes increasingly important to set the stage of definitions and hold them up to the light. In that game Microsoft doesn’t get to spin out of the stage ad blame it all on miscommunication. In that stage Microsoft has to hide into the margins or come out into the light. The second stage is likely and very pleasing to my ego.

You see, when people are part of a $1.5 billion investment there are people who are not pleased with that fact and they will nitpick any document handed to them. One of the oldest settings was ‘What are the definitions?’ Was in older days the way to see what players were up to and that stage got a little lost in populism and ‘fast’ presentations appeasing to the spending player. You might think that it is Microsoft paying, but you would be wrong. The UAE and G42 are investing time and resources to make it all work and I foresee that players like Microsoft (not just them) are trying to play fast and loose with definitions so that they can bank the first agreements and then turn back and hide behind ‘miscommunications’ after that fact. Which is why we have the clear setting of definitions. As such making all players answer that question gives a first setting. You see, there is no AI at present and that comes out at that very start. And no matter how clever LLM’s and Deeper Machine Learning is, the setting becomes data and who is responsible of that data. Now we get different players out and in the full-grown light. People like Sheikh Tahnoon bin Zayed Al Nahyan will then immediately see who is endangering the security of the UAE and they have no sense of humour at that point. No matter how some see the ‘opportunity’ of a life time, the moment the national pride comes into view of danger, the UAE will demand clarity on matters and I reckon some will ‘trivialise’ matters and when you ‘invest’ $1.5 billion there is an issue with trivialisation (which is why I referred to a Texas Hold’em style). Now some will say that I am bluffing and I want to be ‘inserted’ as a possible player. You would be wrong. I do not want to be linked to a player like Microsoft in any way. Google, Amazon, Adobe, IBM and Oracle definitely, Microsoft not at all. As such I am not anti-American (a claim that was thrown at me several times in the past). I am anti-stupid (mostly) and when you start trivialising $1.5 billion I see you as stupid, and no matter what I think of Microsoft, they are not overly stupid. In some things yes, in other things (like playing black letter law stages) not that much. 

But all that becomes moot when some players release the definition lists to all we will see how silly my thoughts are, because these definitions go through the entire project and there is no way they get changed unless all parties openly agree. Oh and before you think that this is a ploy. You might be right. You see, I do not know where China is at present ad I would live to find out. So what is better then Microsoft setting the entire definition list to paper and release it all? I reckon we will see a Chinese response less then 48 hours alter. 

The revolving question is an almost needed stage because definitions on paper is what matters, if it isn’t written down it doesn’t exist. That has been a matter long before the Prince by Niccolò Machiavelli. I reckon it goes back to the days of Gaius Julius Caesar Augustus (63BC-14). So this setting was known for 2000 years and with all the turbo presentations and innuendo I get the feeling it got lost in the woodwork of it all. As such I thought it was a great idea to remind people of that. 

Silly me, have a great day.

Leave a comment

Filed under Finance, IT, Law, Politics, Science

Is that so?

I was taken aback a little when I read the Khaleej Times yesterday. The article (at https://www.khaleejtimes.com/uae/old-smartphones-lying-in-cupboards-why-uae-residents-fear-recycling-their-devices) gave me pause to consider this. You see, when we see ‘Old smartphones lying in cupboards? Why UAE residents fear recycling their devices’ we can make all kinds of assumptions, but the clarity should be clear. There are a whole range of people who do not like their data up for grabs. The funny part is that Norton solved the issue over 40 years ago. Now we get a whole range of other options. But the simple sentiment is clear, and this is on Google and Apple to follow suit. 

I reckon that the solution will be similar for pretty much the same for both systems. The idea is that once you have transferred your mobile and data to the new phone, the old phone is pretty much redundant. So here comes Google/Apple and with their cable (in case of Google a USB-C) we can go to town, well, basically, the new phone can. 

So as I see it, the steps are as follows:

  1. Recharge old phone completely.
  2. Connect the recharged new phone to old phone.
  3. Instruct the new phone to wipe the old phone.
  4. Old phone gets wiped.

As the new phone gets the instruction to wipe the old phone, it will wipe, not delete to old phone.

This means that the new phone knows what the old phone is and will overwrite it with the value ‘EA’ (that was the old value). As such every bit off the old phone is overwritten with the value ‘EA’. It can be nearly any value, but this was the old setting I had in the 80’s. Because it is overwritten, there is nothing to undelete (read: restore). All data is wiped and no longer retrievable. In my case it was done 5 times (in case something is missed). As such the reference that the Khaleej Times gives us with “According to industry experts, fear of inappropriate use of data is one of the biggest deterrents to recycling devices among UAE residents” is no longer in effect. That being said, these ‘industry experts’ should know about this solution. And it is time for Google and Apple to be clear to the customers that their data is safe in this way. There are still a few other risks that people have, as they will readily put their data on social media, but their phones will be ‘saved’. 

What I don’t get is that both Google and Apple never touched on this subject before (as far as I know). Because iPads and other tablets face similar issues. I basically did this in my own way, in the more recent fields I did the same on my own way, but Google and Apple should have had these solutions in play already, so why was this skipped?

I cannot tell, but this article made me wonder why it was not taken care of. You see Peter Norton Computing has been around for 40 years, in 1990 it was taken over by Symantec and they had the goods, so why didn’t Apple and Google wake up to this setting? I never saw it (as far as I can remember) and it is not a weird setting. Consider all these corporate mobiles. At some point their IT departments will take a safe road by wiping their mobiles. So, why was this seemingly not done? I use the word ‘seemingly’ because it seems weird that it is only me who gets the idea. You see, doing a factory reset (as stated) gives us: “Doing a factory reset will delete nearly everything on the device”, it is the adaptation of the word ‘nearly’, I have an issue with that. Nearly isn’t everything, but what is not wiped? I reckon only the layer 1 people at Apple/Google can clearly identify them. There is still the setting that is set in motion. You could a ‘layered’ wiping of all memory through the new phone, optionally moving data from the old phone to the new phone (which Google/Android has). And doing it from phone to phone could optionally move ‘forgotten’ stuff to the new phone as well.

Oh, and that was the second part, the Khaleej Times never even mentions the factory reset part and the added GenAI settings that we see now more and more makes the wiping of old devices a lot more essential. In my story on August 11th 2024 which was ‘Setting of the day’ (at https://lawlordtobe.com/2024/08/11/setting-of-the-day/) gave us via Wired “Microsoft’s AI Can Be Turned Into an Automated Phishing Machine” we see the additional need for a complete wiping of all data. And as far as I can tell, there is no guarantee that some eager beaver will leave ‘discarded’ data alone. As such I feel that Apple and Google need to strap on their goods and get cracking to take the chance of certain solutions not to get a handle on your data.

I might not need it (I have other systems running) but the bulk of the users could use that little more protection. #Justsaying.

So let this be an idea that these two players get to seemingly rectify in the very near future. Darn, my Saturday starts in 92.4 minutes.

Leave a comment

Filed under IT, Science

The tables are starting to turn

This is a setting I always saw coming.It wasn’t magic or predestination, it was simple presumption. Presumption is speculation based on evidence, on facts. The BBC puts out a near perfect article (at https://www.bbc.co.uk/news/technology-67986611) where we see ‘What happens when you think AI is lying about you?’ There are several brilliant sides to it, as such it is best to read it for yourself. But I will use a few parts of it because there is a larger playing field in consideration. The first to realise is that AI does not exist, not yet. 

As such when we see ““Illegal content… means that the content must amount to a criminal offence, so it doesn’t cover civil wrongs like defamation. A person would have to follow civil procedures to take action,” it said. Essentially, I would need a lawyer. There are a handful of ongoing legal cases round the world, but no precedent as yet.

This is actually a much larger setting then people realise. You see “AI algorithms are only as objective as the data they are trained on, and if that data is biased or incomplete, the algorithm will reflect those biases” Yet the larger truth is that AI does not exist, it is Machine Learning or better, as such it took a programmer, a programmer implies corporate liability. That is what corporations fear, that is why everything is as muddled as possible. I reckon that Google, Microsoft and all others making AI claims are fearing. You see when you consider “The second told me I was in “unchartered territory” in England and Wales. She confirmed that what had happened to me could be considered defamation, because I was identifiable and the list had been published. But she also said the onus would be on me to prove the content was harmful. I’d have to demonstrate that being a journalist accused of spreading misinformation was bad news for me.” I believe it is a little less simple than that. You see algorithm implies programming, as such the victim has a right to demand the algorithm be put out in court for scrutiny. The lines that resulted in defamation should be open to scrutiny and that is what big-tech fears at present, because AI does not exist. It is all based on collected data and that data should be verified by the legal team of the victim and that stops everything for the revenue hungry corporations. 

In addition I would like to add an article, also by the BBC (at https://www.bbc.co.uk/news/technology-68025677) called ‘DPD error caused chatbot to swear at customer’. It clearly implies that a programmer was involved. If language skills involve swearing, who put the swear words there? When did your youngest one start to swear? They all do at some point. So what triggered this? Now consider that machine learning requires data, so where is that swear data coming from? Who inclined or instituted that to be used? So when you see ““An error occurred after a system update yesterday. The AI element was immediately disabled and is currently being updated.” Before the change could be made, however, word of the mix-up spread across social media after being spotted by a customer. One particular post was viewed 800,000 times in 24 hours, as people gleefully shared the latest botched attempt by a company to incorporate AI into its business.” Consider that AI does not exist, consider that swear words are somehow part of that library, then consider that a programmer made a booboo (this is always allowed to happen) and they are ‘updating’ this. A system is being updated to use a word library. Now consider the two separate events as one and see how much danger the revenue hungry corporations have placed themselves in. When you go by ‘Trust but verify’ we can make all kinds of assumptions, but data is the centre of that core with two circles forming a Venn diagram. One circle is data, the other is programming. Now watch how big-tech is worried, because when this goes wrong, it goes wrong in a big way and they would be accountable for billions in pay outs. It will not be a small amount and it will be almost everywhere. The one case of a defamed journalist is one and in this day and age not the smallest setting. The second is that these systems will address customers. Some will take offence and some will take these companies to court. So how much funds did they think that they could safe with these systems? All to save on a dozen employees? A setting that will decide the fate of a lot of companies and that is what some fear. Until the media and several other dodo’s start realising that AI doesn’t yet exist. At that point the court cases will explode. It will be about a firm, their programmer and the wrong implementation of data. I reckon that within 2-3 years there will be an explosion of defamation cases all over the world. The places relying on Common Law will probably be getting more and sooner than Civil Law nations, but they will both face a harsh reality. It is all gravy whilst the revenue hungry sales people are involved. When the court cases come shining through those firms will have to face harsh internal actions. That is speculation on my side, but based on the data I see at present it seems like a clear case of  precise presumption which is what the BBC in part is showing us, no matter how courts aren’t ready. In torts there are cases and this is a setting staged on programmers and data, no mystery there and that could cost those hiding behind AI are facing. It is merely my point of view, but I feel that I am closer to the truth than many others evangelising whatever they call AI.

Enjoy the weekend.

Leave a comment

Filed under Finance, IT, Law, Science

One bowl of speculation please

Yup, we all do it, we all like to taste from the bowl of speculation. I am no different, in my case that bowl can be as yummy as a leek potato soup, on other days it is like a thick soup of peas, potato with beef sausages. It tends to depend on the side of the speculation (science, engineering or Business Intelligence) today is Business Intelligence, which tends to be a deep tomato soup with croutons, almost like a thick minestra pomodore. I saw two articles today. The first one is seen (at https://www.bbc.co.uk/news/technology-64917397) and comes from the BBC giving us ‘Meta exploring plans for Twitter rival’, no matter that we are given “It could rival both Twitter and its decentralised competitor, Mastodon. A spokesperson told the BBC: “We’re exploring a standalone decentralised social network for sharing text updates. “We believe there’s an opportunity for a separate space where creators and public figures can share timely updates about their interests.”” Whatever they are spinning here, make no mistake. This is about DATA, this is about AGGREGATION and about linking people, links that too often Twitter has and LinkedIn and Facebook does not. A stage where the people needs clustering to see how to profiles can be linked with minimum connectivity. It is what SPSS used to call PLANCARDS (conjoint module). In this by keeping the links as simple as possible, their deeper machine learning will learn new stage of connectivity. That is my speculated view. You see this is the age where those without exceptional deeper machine learning, new models need to be designed to catch up with players like Google and Amazon, so the larger speculation is that somehow Microsoft is involved, but I tell you now that this speculation is based on very thin and very slippery ice, it merely makes sense that these to will find some kind of partnership. The speculation is not based on pure logic, if that were true Microsoft would not be a factor at all.

But the second article (from a less reliable source is giving us (at https://newsroomodisha.com/meta-to-begin-laying-off-another-11k-employees-in-multiple-waves-next-week/) so they are investigating a new technology all whilst shedding 11% of their workforce. A workforce that is already strained to say the least and this new project will not rely on a dozen people, that project will involve a lot more people, especially if my PLANCARDS speculation is correct. That being said, if Microsoft is indeed a factor, the double stump might make more sense, hence the larger speculative side. Even as the second source gives us ““We’re continuing to look across the company, across both Family of Apps and Reality Labs, and really evaluate whether we are deploying our resources toward the highest leverage opportunities,” Meta Chief Financial Officer Susan Li said at an Morgan Stanley conference on Thursday. “This is going to result in us making some tough decisions to wind down projects in some places, to shift resources away from some teams,” Li added.” Now when we consider the words of Susan Li, the combination does not make too much sense. The chance of shedding the wrong people would give the game away, yes Twitter is in a bind, but it will add full steam in this case and they will find their own solutions (not sure where they will look), a stage that is coming and the two messages make very little sense. Another side might be pushing it if Meta is shedding jobs to desperately reduce cost, which is possible. I cannot tell at present, their CFO is not handing me their books for some weird reason.

Still, the speculation is real as the setting seems unnatural, but in IT that is nothing new, we have seen enough examples of that. So, enjoy your Saturday and feel free to speculate yourself, we all need that at times to TLC our own ego’s.

1 Comment

Filed under Finance, IT, Science