Tag Archives: Grok

Changing the byline

That is the setting I see and whilst the BBC (at https://www.bbc.com/news/articles/cqgk5e2j0gg8o) gives us ‘AI ‘kill switch’ may need to be mandatory, Anthropic co-founder tells BBC’ a mere 5 hours ago. I had my thoughts. So, as we see “An artificial intelligence “kill switch” which can be checked by a third party may need to be mandatory for companies, a co-founder of one of the world’s largest AI firms has told the BBC.” I see something different. So when we get to “Clark said “most labs have different ways of being able to pull the plug”, including Anthropic, but said lawmakers may need to enforce having one. AI’s rapid development and fears over the risks it poses to humanity have been thrust into the spotlight by a series of warnings from executives and staff at AI firms.” And when we get to “Anthropic chief executive Dario Amodei over the weekend called for the pace of AI development to slow and be more closely monitored, as the company has done before, though some have questioned the motivations behind this.

Amodei added that any action to rein in AI development should be done “without sacrificing commercial advantage”.” Thoughts started to overwhelm me. Some people state that the setting is about “AI’s rapid development and fears over the risks it poses to humanity” I don’t think that is the case. I merely think it is what some will ‘present’ the setting that we are given and most people are willing to go along with that. There is however a larger concern. You see I have had my meetings with these AI boffins and they all have the same setting towards validation and verification that is in play. There isn’t any of it, and when it is there it is there in the most ludicrous basic ways. You see, there is just one step (just one) from AI hallucinations (which is a confident response from an artificial intelligence system that contains false, misleading, or completely fabricated information presented as fact) and it is seen as Invented statistics, historical errors, or nonexistent legal citations, as well as Citations to books, research papers, or URLs that do not exist. I have seen this and I have seen that the settings that this represents to court cases are numerous and we have seen n the news several settings. But the larger concern is that between that and an AI actually overwriting factual matters of any corporations is only one mere step and these fake AI vendors are insulating themselves from that fact by ‘employing’ a kill witch, so that they can avoid getting called into court by setting the stage of ‘Did you use the kill switch?’ And that  is the setting I see. So whilst we are given (by the BBC) ““Should you mandate for companies to definitely have a kill switch? Is that kill switch verifiable by a third party?” he asked.

“I think that’s the kind of thing society is going to want to know and might want to eventually pass rules around.” Anthropic, which was formed in 2021 by a group of former employees of its rival OpenAI, is currently at the centre of a debate around AI safety. Last week, a post from an artificial intelligence researcher who quit Anthropic over concerns AI could wipe out humanity went viral.” So is this really about “over concerns AI could wipe out humanity”, you do know that Cyberdyne is just a figment of the brilliant director named James Cameron, it was ahead of its time and we aren’t nearly there yet, but the kill switch scape goat is one way to counter the class actions heading their way and whilst some can’t be avoided, the larger concern is what will happen in 2027, because that will be the truncator of their wealth and they are seeing the stoplights and they want to insulate themselves from their fake AI. They rode the waves as much as they can, but the first blockages are showing and now the cautious people are rearing their heads. I see all the complacencies showing up (like figment court cases) and that is merely the beginning, but the setting that corporations factual data is overwritten or wiped is only one step away and I reckon that these people want to insulate themselves and as they are coasting their vessels of wealth towards sunny shores, they have no other option but to insulate themselves and their wealth. 

Funny that I saw these court cases come up a long time ago. I never saw this part, but this part makes sense. When your training data is based on reddit (whilst we are given “Major AI companies train their models on nearly all of Reddit’s public historical archive”) is this continuation of dangers weird or unsuspected? As I see it, when even one factual data is overwritten by some fake AI juiced up on reddit, the setting gets ugly in a hurry. And that is what these people are ‘misrepresenting’ and crying now for some kill switch, because the kill switch is not for the AI, it is their escape clause. So whilst you might doubt me (always a fair setting) I have written about the fake AI setting for the longest time. 

So someone asked me what makes binary AI surreal? I give them the same setting every time. Take any colored image (example 600 by 600 dots) and run it through plotter printing only black and white dots on a colored piece of paper (green, red or blue) then do it on the same kind paper and instead of black and white, add the option to do this in black, white and 16 greyscales. You will see that this image is much more precise and revealing. This is the setting between binary and trinary this is why all AI is fake and it gets to be worse when you consider that you need a lot more data describing in binary what requires trinary and that is why I was on this horse all along and I have been on it for over 10 years, but the players all think that they have the golden goose and I merely cannot see what it is. Well, It is ‘advanced’ predictive analytics. These AI cannot reason, they work the numbers, go with statistics and it is nice if it is a set field, when they go towards never encountered situations, it all falls apart. This is the weakness of these fake AI’s and it is not whether I hate AI, I merely don’t trust it, because it is not AI, and Alan Turing would have my back on this. 

So whilst you think that I am “Full of Sh*t”, which is your right. My predictions are given form through my blog and in 2025 I predicted that 2026 was the year of AI class actions and now we see “Broadridge’s 2026 Global Class Action Annual Report highlights that global class action activity recently produced around $4 billion in settlements across multiple jurisdictions from roughly 130 major claim-filing deadlines” as well as “According to the Duane Morris Class Action Review, the combined value of the top 10 highest settlements across all substantive areas previously crossed the historic $70 billion mark, showing how massive individual mega-settlements drive the ceiling of total class action value” and “In the U.S. and global financial sectors, recovery momentum has accelerated into 2026, with an increasing number of nine-figure and $100M+ securities settlements closing out the mid-year milestones”, as such my predictions are holding up neatly. And now these vendors need insulation and they are thinking (optionally correct) that a kill switch might take the dangers to their wealth away. And I get that these fat cats want to insulate their wealth and insulate the dangers to them, but the BBC should have a greater need to look into these dangers and that is why I took this article as an example. I reckon that it is not only the BBC going after this. As I see it, Dario Amodei, Sam Altman and Elon Musk are all in agreement to slow down, but I reckon it is because they are seeing the dangers heading for their assets and they are in it too deep (as I personally see it). 

As I see it, this is the heading that we are seeing happen and soon there will be some (optionally fictive) revelation and that is when the stage changes and we will see massive amounts taken out of the AI field. When that happens there is no Jensen Huang claiming that there is no bubble, the court cases that will be an exploding setting will shut that down in a hurry. 

But what do I know? So you all have a great day today and I will be watching from the docks watching the good ship bubble explode near the parking zone. And I can say this whilst I have been preaching these dangers for nearly a decade. Where exactly where you a decade ago? Consider this setting and enjoy your day. 
Leave a comment

Filed under Finance, IT, Media, Science

Telling the tale

There is a setting we see and we ignore, but I am not one of these people. You see all AI is fake and the sooner you realise this, the better you are off. For example, yesterdays article was ‘stated’ as “a creative fiction story dated September 3, 2026, presented as “part one.”” Yes, the end of the article stated “the end of part one” and the title was “Where gods are left for dead” but Grok went with the part one side. This is how clueless AI (aka Fake AI) really is and there is more, none of these fake AI’s can deal with multidimensional points of view. It is programmed and as the programmer loses sight of things, these fake AI’s do that too. So as we get into part two of this story, I need to add that between part one and part two is a gap, this gape relies on civil engineering and I never studied that, I ‘merely’ studied ships engineering (apart from my three uni degrees) and this makes me a dirty old man (people from the 70s get that one). So lets not dilly dally and get to it.

Beginning of Part two
As I was looking on this small alcovian setting I looked at a brass door with no real entry point, I expected that, as such I had brought two elements. One was a sticky rope drenched in Nitric acid and I brought a dispenser with hydrochloric acid. I went for the nitric solution first, knowing that it might take some time. I had a little hip flask with cognac, but I wanted to leave this unless the temperature would drop a lot more. It was slightly too warm for that. It was merely two minutes later when the gaps in the brand door started to show. I quickly ascertained that the other side was empty, the lack of light was an indication of that. I had a diamond with and a stick to make short work of that. It took a few more minutes as the door got melted a lot more and in the mean time I had sawn sides clear and it was under 10 minutes when the gap was large enough to fit through. I hesitated on the other side were hundreds of dead rats, it could have been thousand plus, I did not care to count them, bit the bones were everywhere. I took my simless mobile to ascertain the air quality. It wasn’t good, but there were no toxins, at least not the ones I could scan for. I decided to keep my breathing solution on and carefully went through the hole. The crisping sound of cracking rat bones were pretty intense, this place carried sound like nothin I have seen and the room was ring shaped with water in the middle. An optional exit point. The edge had an ascending staircase and it went through a door. I scanned the stairs and they looked OK, so I ascended to the door at the end which would have led to another room. The door was fine, it was solid oak and it has ironwork all over it, a strengthened door and I felt hopeful that that this would lead to the solution of my nightmares. There was an oak barrier stopping the door from opening. So it was meant to keep something in. I opened the door. In the room was a simple altar and something on top, it seemed like some kind of shield partially encased in something that looked like lead. There was a thin book next to it. I decided to look into that after I had examined the altar looking table. It was on top of something and from one side I could see that this thing was keeping a pressure thingy in place. I t gave me an idea and I quickly walked back to the entrance and I grabbed two pieces of brass, I might need that. 

I walked back to the altar and put the pieces on the ground. 

I then opened the book, it stated:

At present you can either learn latin, or read the English version below.

I looked at the script and pocketed the script. It was as I suspected, I then looked at the altar. I placed the part of brass and I inspected the strength. I then also picked two rods of iron, they were meant for another option, but it was was good as it got and when I placed the iron rods and the brand pieces on the sides, I glued them to the foundation of the pressure plate. It should hold, unless the shields were a lot more heave and I tested this by raising the shield a few millimeters. It did not move. Satisfied, I placed another coating of resin on the rods and after a few minutes I was convinced it was safe to do so, I tried to raise the shied. It was remarkably light, it had the lead weight, but that was it, the entire contraption was no more than 40 lbs. and 30 of them were lead. I took the shield and went the way back. I had no idea if the pressure plate jam would hold and I was not eager to loiter around. I went back moved the shield back into the previous room and left the cistern in the middle for what it was, too many question marks. I got back to the room and move back to the shallow grotto and small stream that connected to it. I reckon that at some point people will figure it out and I wanted to be far from there when that happened. 

I got back to the entrance where the car was at 18:15, I wanted to wait as long as I had because there is no reason to be rushed. It was 02:45 when I put my head above the ground and I quickly for into the van and I rode off past the viale Vaticano, only when I passed the Quadraro did I sigh out and released the stress in my body. It was only 25 minuted to the Jetex Rome Ciampino where a plane would be waiting for me and not to mention the reward of a lifetime and my employer never let me down, in other news, the drawings and artwork could bank me millions in addition and I had already cleared that this was all mine. An interesting turn of events. There is even the the setting that I the ‘jail’ had elements worth its weight in diamonds, but that would be under advisement. I was not greedy and the images would be worth its weight in gold, even if I just hocked them off as digital figment of copied works. This was a far better setting than I have every had and the ego of mine to take something from the Vatican was worth more than all the gold in Italy. Time to get ready for a flight to a place called Thessaloniki Airport “Makedonia”

With this I end part two. Just a setting to stretch my imagination and in all this slop of debatable news and social media slop, it was the best I could do to ensure creativity survives. Apparently several Fake AI have shut down, which doesn’t bother me as I tend to rely on my old grey cells as a solution. 

Have a great day today.

Leave a comment

Filed under Religion, Stories

Passing the buck

That is what I saw yesterday, people (I reckon wannabe influencers) are now starting to head towards the setting that AI is the root of all that is evil (apart from that AI being fake, it is not responsible for anything), but as we see the ‘amount’ of so called evidence pile up, you would get this idea. I even saw a reference to one of my own articles (with the wrong data and a reference to another story) added to that pile. So whilst these wannabe’s are not entirely wrong, they are merely adding the wrong quotes to the wrong pile. (They must have used some kind of fake AI). But in the article ‘And Grok ploughed on’ (at https://lawlordtobe.com/2025/11/27/and-grok-ploughed-on/) I made mention on November 27th 2025 “Check out the blog, none of those elements were mentioned there. As some tell us Grok is a generative artificial intelligence (generative AI) chatbot developed by xAI. So where is that AI program now? This is why I made mention in previous blogs that 2026 will be the year that the class actions will start.” And now we see (in various sources “AI-related class action filings are surging in 2026, driven by a sharp rise in investor securities lawsuits over market corrections, ongoing copyright and training data disputes against major tech platforms, and emerging product liability risks” (source: Norton Rose Fulbright) as well as “According to mid-year data from Cornerstone Research and Stanford Law School, federal securities class actions jumped significantly, with 15 AI-related filings recorded in the first half of 2026 alone—nearly matching the 16 total cases filed through the entirety of 2025” (source: CFO Dive). So as I see it, some are passing the buck and whilst there is a shift noticeable in several directions with the premise “Governments are reacting to ongoing friction; for instance, Australia announced intent to establish an Office of AI and legislate stronger artist/creator control over works used in AI training, while courts in the US navigate strict parameters around fair use and dataset destruction” As I see it, the United States wishes their American corporations to get the freedom of fair use (at the expense of anyone else) and others want to keep the IP of the artists and artisans intact. As I am in group two I feel happy that group one might end up with a peppered bill for yours truly (that would be me), but I am not holding my breath on that happening any day soon. And the gremlin in me would love the idea that I gave all my IP to China and see how the USA fights off that setting. I reckon that the Gremlin in me likes that (it will not like to optional fictive loss of revenue, but that is another fight all together).

What is fun is to see these wannabes blame a fictive AI, whilst the users of that fake AI have the larger blame here. But that it also the hidden trap. You see, someone said: “the starting of digital conditions is the beginning of the end. Soon these conditions change and after that the denial that this was ever the case starts” and I tend to agree with this person. We already saw several issues in gaming and a lot more in the business sector and Business Intelligence. The old premise from Emperor Augustus comes calling at that stage “If it isn’t written down, it does not exist” He said so around 25BC, which means that this setting was clear almost 2050 years ago. It seems a hard sell to hear some say “We didn’t think of that” or “It was a corporate policy” and whilst the useless waste more and more of our time, these settings will delve into the framework of too many systems. Which was exactly why I put all my IP online, there are too many settings where things are found out and whilst we accept that, it also means the my chance of financial greatness becomes a little trivial (to say the least). But I still believe that putting in front of everyone is the only way to guarantee your point of view. It is those wannabe’s that state “Just hand it to me, trust me. I’ll do right by you” betting it all on the roulette table is likely the only option for you (even thought the payout is lousy). But in all this I don’t gamble. I even have a setting where otter’s might win some, but the wannabes are likely to never end with one of my dimes. 

So whilst we now see that “The Disclosure Dollar Loss Index surged as companies over-promised on AI deployment, infrastructure, and data center capacities, causing sharp stock drops when growth hit roadblocks” (source: Cooley)  but here are different roadblocks too. You see, what some claim and what is proven are different settings. We might agree that all AI is bad, but that generalization is also dangerous. Because they could have added a book to their learning curve and whilst the ‘original designer’ forgot that the book in question made the coin tremble, the learning ability might have gotten through this setting in different ways and whilst the Training curve of the fake AI is not explored, because it becomes likely too hard or too convoluted, the mess is created by “All fake AI is evil” and that too is a wrongful generalization that has a deepening effect. So whilst we see ‘over-promised’ the setting is a little sweeter than that. So whilst generalization and wrongful verification comes to blows (which will happened) the investor is left out in the cold and when this happens more than once, the wells dry up fast (which is where I was in 2025, I basically saw this happen in my mind) and in all this verification and validation remains the big two that none of the (fake) AI firms have a handle on. And at present I haven’t seen anyone who is tackling these elements and whilst I still believe that the Epsilon (AI) co processor will optionally solve a lot of issues, there is no way to tell at present. So whilst some call this the Neural Processing Unit (NPU), the settings that current NPU’s and the future Epsilon processor have is a setting that allows trinary data to solve whatever binary cannot do and there is no real time track for that event to happen. Especially when it was decided (years ago) that binary was cheaper and the people behind that brainwave are (speculatively) merely accountants that went the technological setting. They know all about the costs of the setting, but reaping the rewards is also at a low, because they can’t see the benefit that the more expensive solution had and that is where these settings are, but that is merely my speculative view on the drawn stage.

So whilst I see options and benefits, it will likely fall on deaf ears and they are all gong the binary track, which at present is woven and interceded by over a dozen class cases in the first half of this year and at least as much for the second half as well. But we will see how that dollar moves from stage to stage, but regardless of that, even if you consider that the cases at present have settled for over $1.65 billion, how much comes from the investment amounts. How many are purged to be a near total loss? We might think that people like Jeff Bezos, Mark Zuckerberg, Elon Musk and a few others can stand to lose this. But their retirement funds aren’t on the line and those who do will chance to all on some poker bet and risk losing a lot more and these settings should have been sure wins and they were not, this is the trap that no-one wishes to acknowledge  that it is in play. 

But that is just me, I am not the gambling type and I see too many passing the buck at present and whilst there is a agreeable setting of blaming these fake AI’s the clearer setting is that passing the buck was in the most inconvenient setting. Because if AI is so foolproof, how come that the houses are actively promoting the ’00’ option at these roulette tables? If it was a sure thing, we could all benefit, but the is not the case, is it?

Have a great day this day.

Leave a comment

Filed under Finance, IT, Law, Media, Politics, Science

Is Grok losing the plot?

That is the actual setting and it takes a little space to explain this part. So the other day I was ‘watching’ Elon Musk giving us the following explanation: “Elon Musk predicts that artificial intelligence will exceed the sum of all human intelligence by around 2031, leading to a profound transformation where digital work is automated rapidly, human control shifts within a decade, and ubiquitous robotics trigger an unprecedented global economic boom” and some might say that at $1,000,000,000,000 he is likely nothing more than a 2nd hands car salesman (a very well paid one), I actually don’t care, because all AI is fake AI and yesterday I got some evidence on all this. 

So, why get Elon involved? Well, he owns Grok and Grok was the setting of it all. You see, I tend to pass my articles through Grok. In part for the entertainment, in part to see if Grok saw what I was seeing and at times to see what it sees more. So what happened? It started with my article ‘Flame on’ (at https://lawlordtobe.com/2026/08/09/flame-on/) nothing special, but Grok ‘devaluated’ this to:

Read the story and you start seeing the issue. I also passed this through ChatGPT (my very first visit) and that gave a little bit tedious, but a real good assessment, attacking the article on what it saw (whilst it ignored the setting that it was a blog and not an academic paper). As it was (fake) AI I tried regenerating the output, but it was all useless and even less useful than what you read above. I tried Google Gemini, but that one doesn’t seemingly accept an internet link (I might not have used it correctly) but the simple setting is that Grok might have been losing the plot. So I used it two subsequent days and it all looks decent, so I tried it again onboard ‘Flame on’ and again a failure. 

So now we get to the insanity setting that doing the same thing and expecting different results might be insane. But as I see it, this is all DML (Deeper Machine Language) and LLM (Large Language Models) in action and there is enough setting to optionally expect a different result. There is also the seating that all this is programming and not AI. As such errors are fixed and more changes are made making this an optional never a static setting. So whilst I would love to blame the programmer (and it likely is) there is a setting we cannot ignore and in the past I have seen that Grok does not align to multiple viewpoints correctly (and I have 4 examples somewhere to show it cannot decently do this). So whilst we agree that this is not a complex setting, it is programming, pure and simple.

I have seen my share of lever programming and whilst we can agree that LLM settings are getting clever, it is not AI, nor will it ever be (as I have stated a few times in the past). So whilst I applaud ChatGPT on the ability to ant-fuck the equation (a Dutch expression), it is clever, optionally wholesome, but not AI. So whilst we now see that too many people are buying into the AI setting and even accepting that it can go rogue and hack settings, all whilst it is programmer controlled, as such, these players are likely adhering to state players and all this is needed to gan the insights of corporate IP and seeing how they could turn a dime. This and this alone is why I pushed all my IP to public domain and as I would never gain coins from any of this, I made it public domain, so that the right people have something to work on. My legacy to leave the world.

So is Grok losing the plot? It is a fair question and whilst Grok could not analyze my piece and ChatGPT could, there is a clear setting that this is optionally the case. It does not matter that it only failed once. If it was an AI, it should not ever fail once. That is the reality of a real AI. It gets it right 100% of the time of there is data and my article is data. It is when there is no data that an actual AI gets it right over 98% of the time and that is not happening either in many cases, as such I call all AI fake AI.

That is the setting and whilst some will debate this (and disagree) there is plenty of evidence around to say that I am right, A stage we cannot ignore and whilst some (optionally correct) disagree that Grok has not lost the plot, the seating is out there and the evidence is all out there. And these ‘captains of industry’ have to agree that their solutions is riddled with issues (as they are programmed) or that they are invoking the AI label to get away with whatever they can. So whilst some might agree with the setting of “exceed the sum of all human intelligence by around 2031”, it is a setting that I disagree with, because having all the data of every book and every encyclopedia is nice, but it is merely clever LLM programming. Exceeding the sum of human intelligence requires to make correct leaps of non data, extrapolation of non existing data (like speculation and presumption) and these systems still aren’t able to do that and I wrote about it in the past and it will require an optional 2 decades to do that and that exceeds the timing point of Elon Musk by well over a decade and personally I believe that it will not even be correctly possible without an Epsilon processor (a speculative trinary processor) because the setting of Null, True, False will only incur additional and more errors making ‘their’ setting of AI less and less reliable and that is before we validate and verify the data these systems have and they haven’t worked that out yet. As I see it the first step is getting the Epsilon processor online which will give us the option of Null, True, False, Both. That is a first step and none of these systems have that, because the processor doesn’t exist yet (perhaps the Dutch physicist is on route, but I have no idea where they are). So in all this we might get more and more of systems losing the plot and that is whilst they have all the data and my article is less then 3000 characters. Consider that when you consider these AI systems being clever. 

So have a great day and perhaps I have more (optionally) sneaky stuff too hand you in under 20 hours. 

Leave a comment

Filed under IT, Media, Science

Considering the greed of others

This is where I found myself this morning. You see, I have published over 4000 articles and others have been Ising them to train their fake AI systems. Training LLM settings and so forth. As such (and according to law and at https://hwlebsworth.com.au/feeding-the-machine-how-us-courts-are-drawing-the-line-on-ai-training/) we see ‘Feeding the Machine: How US courts are drawing the line on AI training’ where we see “The accelerating development of generative artificial intelligence (AI) has forced courts to grapple with novel and unsettled questions of copyright law. Central among these is whether the use of entire copyrighted works to train large language models (LLMs) without the author’s consent constitute infringement of those works.” Which works in my favour and it comes with “The datasets used to train AI models often contain digital copies of media such as web pages, books, videos, images and music. These media are often the subject of copyright protection, which means that their use to train AI models requires permission from the copyright holder. Permission is required because AI models must ‘copy’ the protected material at least temporarily to undertake the training process.” You see, from May 11th until now my articles have been used for ‘AI training’ at least 33,750 times and a lot more before that. As such I see an opportunity for me, myself and I (as such I am a sneaky trinity) so as we are given “The Interim Report then went on to discuss Australia’s ‘fair dealing’ regime, which allows certain uses of copyright works without the need for license from the copyright owner, but only for certain specified purposes, such as research or study, criticism or review, or parody or satire. The Interim Report seeks feedback on expanding this regime to include fair dealing for the purpose of text and data mining, which could more squarely legitimise AI training activities in Australia.

Where the Australian ‘fair dealing’ regime only applies to certain permitted purposes, some other countries, such as the United States (US) have a broader ‘fair use’ doctrine, under which any use of copyright material may be permissible provided that it is considered fair, without reference to legislatively-permitted purposes.” So, as I see it, money should be coming my way. And as the article in HWLE lawyers state. The setting of “In June 2025, the US District Court for the Northern District of California issued two decisions in Bartz v Anthropic PBC (Bartz) and Kadrey v Meta Platforms Inc (Kadrey), that directly addressed this question. While these rulings suggest that US courts may accept fair use as a defence to AI training, their scope is narrow. Both were decided at the summary judgment stage, and as the Judge in Kadrey noted, ‘the consequence of this ruling is limited […] to the rights of these thirteen authors‘. Accordingly, the significance of these rulings remains provisional, with the scope of fair use in the context of AI training to be more clearly defined as further cases are determined.” So, to get it clear, those are American judgements, but they have a much broader setting of ‘fair dealings’ then Australia has and my thought process is a little bit in the setting of “You can either hand me a generous settlement, or if needed I will get it through the law”. The second setting s long and optionally tedious. But as I am looking at closer to 50,000 transgressions the taximeter starts adding up. Now, I have no faith in 50,000 times 1.5M, which would be nice, but is ludicrously unrealistic. But the idea of $25,000,000 per corporation seems realistic. You see

So we get to “While both courts concluded that the training uses fell within the scope of fair use, their reasoning diverged in certain aspects. Alsup J emphasized the transformative purpose of training and discounted speculative claims of market harm, whereas Chhabria J stressed the potential for market harm arguments and evidence to alter the analysis. These decisions have no binding effect in Australia, where there is no general fair use defence. Nonetheless, they highlight the emerging tension between protecting incentives for human creativity and facilitating technological innovation; a tension likely to intensify as generative AI becomes further integrated into creative and commercial practice.

As such, I felt really good this morning. As this shows that I might be heading to a nice bank account. And as it happens to go (source: AP News) we get “A federal judge approved a landmark $1.5 billion copyright settlement requiring Anthropic to pay thousands of authors roughly $3,000 per book for using pirated digital libraries to train its Claude AI model”So as I see it (a flawed analogy) 50,000 times $3,000 get me $150,000,000 which sounds really nice. I reckon that this is where the art of seeing the diplomatic bounty comes into play. It seems that more than one transgressed on my work and would it be so wrong to go for $25,000,000 per transgressor? Of course, the long road would be more rewarding, but that seems like a greed driven way. I feel more for easy (well rewarded) solutions. And there are upsides to entering retirement with a somewhat fat wallet. Retirement comes across as a lot more fun that way. 

But I am getting ahead of myself, next step will be getting an impartial party (what a weird name for a lawyer) to check Grok, xAI, Gemini, Anthropic, OpenAI, MetaAI, MicrosoftAI (always happy to knock coins out to their coffers), AWS AI (and others) to see whether their training data reveals the presence of “www.lawlordtobe.com” because that starts to process as I currently see it.

Well, that mental joyride was fun to have, but I did say the class actions would be prudent in 2026, I might as well join that cause for the benefit of poor little me and I have caused. I might be one of the people that refers to a church mouse as a decadent rich bitch. One must always keep humour about the premises.

Have a great day.

Leave a comment

Filed under Finance, IT, Law, Media, Science

A breath of fresh air 

This is what happens, at times we get refreshed from some issues that add settled in different ways and the Khaleej Times gave me two of those instances. I was happily refreshed. The first one (at https://www.khaleejtimes.com/uae/uae-investigation-publication-false-report-dubai-explosions) gives us ‘UAE authorities summon news agency officials over false Dubai explosion report’ it comes with the interesting byline “The Attorney-General said that the agency’s decision to withdraw the report and publish an apology does not preclude the continuation of the investigation” I still have to see where this goes, but this setting is refreshing. We get too much populist and digital driven headlines all over the planet and I see too many of them. So seeing this is refreshing to say the least. So as we see “The Attorney-General stated the investigation will determine the respective roles of each individual involved in the different stages of the report. It will also determine the extent to which they complied with legal and professional standards governing the verification of information before its publication” as well as “On Thursday, July 16, the Dubai Media Office confirmed that the Reuters report regarding “explosions” in Downtown Dubai is false. Reuters later issued a statement saying it “regrets” the report and that the story had been retracted the same evening. The agency also confirmed it issued a new report highlighting the Dubai Media Office’s denial. The news agency acknowledged that the report did not meet its standards. Reuters “could not immediately determine where the sounds were coming from or their significance, and did not offer that context,” the statement added.” I see a few issues with the part, but that is merely me and there could be an error in reporting there too. As such it is what it is, but the call by the Attorney-General feels like a breath of fresh air. 

After that we see (at https://www.khaleejtimes.com/business/tech/elon-musks-xai-sues-grok-user-over-sexualized-deepfakes) that ‘Elon Musk’s xAI sues Grok user over sexualized ‘deepfakes’‘ and there is a larger setting there, because this could global and those people weaseling away with “the app made me do it” could quite literally lose their house and their equipment over all this. As such, that 34.2 seconds of fame will come at a massively high price. As such we are given ‘The case is one of the first brought by an AI company against one of its users for allegedly using an AI system to generate explicit material’ with the added “xAI alleged in the lawsuit, filed in federal court in Texas on Tuesday, that Terry Harwood violated the company’s terms of service. The case is one of the first brought by an AI company against one of its users for allegedly using an AI system to generate explicit material. Contact information for Harwood, who was arrested in February, was not immediately available. Spokespeople for xAI did not immediately respond to a request for comment on Wednesday. The company’s lawsuit against Harwood follows intense global scrutiny of xAI over allegations that Grok has allowed users to generate non-consensual sexualized deepfakes, or realistic-looking videos fabricated by AI.” As such I reckon that there will be a sled full of lawyers going for the jugular of this Terry Harwood and if the news given by the Guardian is to be believed, this was done to images of adults and minors. I wonder how the lawyer of Terry Harwood would be spinning that. I reckon that we have to wait for the court case and the submitted evidence. I reckon that all these hormonal teenagers fabricating a slew of images from all kind of actors and actresses will soon face the music of their parents as these parents will likely see their houses going away to other shores. 

I reckon that this is what the victims of these people will go for, the first rule of torts is to go where the money is and that ends up being the real estate of the parents (in case of minors) but that is speculative thinking. What matters is that with the acts of Elon Musk and xAI is the first step of countering the tidal wave of sexualized deepfakes. 

I feel relief, the first time in over a year that something makes sense to me and there is a larger setting for some publications as well. You see they cannot hide behind “given to use by an anonymous source”, when they publish that and the Grok case bears fruit, the victims can now go after these publications as well, because that is the implied trend with torts. Torts goes to where the money is and the value of people like Jeff Bezos, who has approximately $252,000 million and Rupert Murdoch and family who is allegedly the owner of $24,000 million. I wonder how many class cases they will face in this setting. Time will tell.

Have a great day and look towards the sun wearing sunnies. It is a bright day today.

Leave a comment

Filed under Finance, IT, Law, Media

History marks arrived

That is what I see, there are two settings. The first one was not new, it was three weeks old when I saw (at https://www.wired.com/story/a-court-has-ruled-that-google-is-liable-for-false-statements-generated-by-ai-overviews/) ‘A Court Has Ruled That Google Is Liable for False Statements Generated by AI Overviews’ it is not entirely undeserved, but it also sets Google up for people fleecing them, so some will ‘cater’ to the need of supporting a setting that set Google up for a trap. We cannot see this directly from “Germany has issued a ruling that could reshape the operation of search engines and artificial-intelligence-based chatbots worldwide. The Munich Regional Court preliminarily ruled that Google is liable for a series of false statements generated by its AI Overviews feature, requiring the company to prevent the dissemination of erroneous or inaccurate claims through its search engine.” So, whilst some will cater to the need of false feeing that search engine, we are left with a more than slightly vulnerable Google. Whilst we see (at https://www.rmit.edu.au/about/schools-colleges/media-and-communication/industry/rmit-information-integrity-hub/the-repost/june-2026) ‘Should AI be liable for its mistakes? A German court says yes.’ Where we see “Jeannie Paterson, a law professor and co-director of the Centre for AI and Digital Ethics at the University of Melbourne, said the decision was “potentially very important” and could have ramifications for Australian consumers. The decision hinged on who is responsible for the content of AI search results. The law has traditionally considered social media platforms and search engines to be mere conduits for information, Professor Paterson told The Repost, meaning companies “only become liable if they knowingly participate” in sharing information that proves to be wrong.” I personally believe that Professor Paterson is setting up loaded dice. You see, in the first AI does not yet exist. And the second part is “who is responsible for the content of AI search results”, that answer has two stages. The first is the programmer who ‘created’ the analytical setting of predictive analytics, because that is part of any DML/LLM setting. It is not AI. And that data is also a side, because there is a massive failure of validation and verification. We see it all the time and whilst some are ‘whisking’ it away through ‘hallucinations’ I have seen the Grok side of things on data that I created and it take all without any reference other stories I had written, as such we see a programming failure. And through that the stage of “who is responsible” gets a new life and makes the water pretty murky.

That is what I see. And anyone saying I am wrong can take a long walk of a short pier. As I saw that, another stage was handed to me.

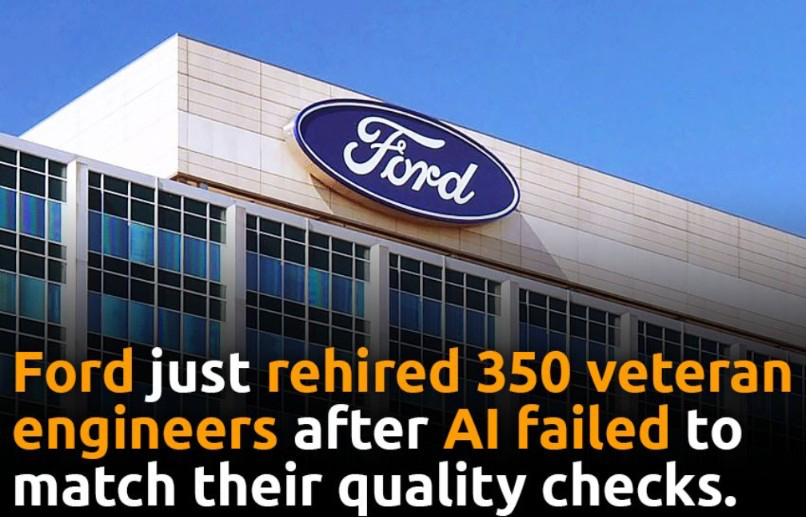
Last week we were given ‘Ford rehires human engineers after AI fails to match quality checks’ (source: BBC), this is not new, I saw this coming a mile away and I present (as pseudo evidence) ‘Is it more than buggy?’ (at https://lawlordtobe.com/2024/01/05/is-it-more-than-buggy/) and I wrote that story in January 2024 (over 2.5 years ago), as such it should count as evidence and I gave the clear settings of “On May 27th 2023 the BBC reported (at https://www.bbc.com/news/world-us-canada-65735769) that Peter LoDuca, the lawyer for the plaintiff got his material from a colleague of his at the same law firm. They relied on ChatGPT to get the brief ready.” Which now intersects with the AFR (at https://www.afr.com/work-and-careers/workplace/ai-use-in-dismissal-claims-borders-on-contempt-of-court-judge-warns-20260705-p60cob) ‘AI use in dismissal claims borders on contempt of court, judge warns’ and considering that this failures car in May 2023 when the BBC reported on this, we see a larger immature failure of other branches as well. You see, that it was tried is OK, and it failed three years ago, as such others should have stopped this as soon as they came aware. These settings all intertwine, because validation and verification is all part of these failures. As I see it, they were never made. I would be in favour of a separate tier of verifying all it produces, and these sources need to be validated. As such “after one claimant’s chatbot cited large swaths of evidence that did not exist, in a case showing the technology bedevilling the workplace umpire is now hitting the courts.” So, evidence that did not exist, where have I seen that before? (Small giggle inserted afterwards). This is why I feel that my services n technical support and customer service will be needed soon enough. When Fake AI fails to this degree. It is one small step for the AI agent to tell the customer “just press the carrier online button on the right side of your device” for this to fail and when that happens a few times, these ai agents will be pushed into the land of the Dodo soon enough. And that (until there is an actual AI) with proper validated and verified data is where that agent remains. You see, it was never rocket science. Some sales person saw the DML/LLM setting and started to call it AI, but Alan Turing had some clear settings on it all and this is not it. I believe in DML/LLM solutions, I saw an amazing application for lost and found in an airport reducing days in optionally less than an hour and there are more, but it is the, not AI, no matter how sweet they mention AI, it is the trap the salespeople set up and now that the class actions are setting in all kinds of field and personally I keep a high note on ‘Unauthorised Training Data’ and ‘AI washing’, whilst an alleged Anthropic settled for $1.5 billion for using pirated books to train its Claude AI model, I see my data transgressed upon and whilst some state that this is $1.5M per work, I was transgressed over 1700 times, as such I should be a billionaire (we can all dream can’t we?) But clearly I am not on that setting yet (to be clear I just confirmed with my wallet and my wallet is moaning due to a lack of green bills of $100. 

All these factors add up and whilst some are already seeing the lack of data, the lack of verification and the lack of validation. There is an overdue stage of properly aligning the settings we should be seeing. And that is why the class actions continue and whilst some will whip them away in settlements. And whilst we wonder why it took so long (over 3 years) for law firms to see that stage, we will see a lot more, because as I see it, the law interns believe that true time savings could be made with any ChatGPT/Claude the reality is slightly different and soon these clients will set up clauses that no AI is to be used and that is the larger failure in all this. So whilst Ford saw their failings in the early age, big software firms  aligning with what they call AI Agentic solutions will soon learn the price of that failure. And this is not just Microsoft, this is likely to effect all large software vendors. As such thousands will be hired once more and some who were pushed out in a slightly disgusting way will seek any other employment, as such these ‘embracers of Fake AI’ as I tend to call them will have a new problem and employment agencies are no longer able to get any, some who used their Agentic solutions from day one. And the fallout is soon spreading all over the world. So as I have seen these markers all over 2025, I see opportunity (for myself) and other technical support people in 2026 and 2027. The question for these firms becomes, did they treat their support people proper, or were they (as the teams goes) ‘dicks in reducing their staff members’ in this I love the quote from Walter Mitty (Ben Stiller) “This thing that you do, Ted, where you come into a place and push people out, you should know those people worked really hard to build this magazine. They believed in the motto. And I get it, you’ve got your marching orders and you have to do what you have to do, but you don’t have to be such a d*ck. Put that on a plaque and hang it at your next job.” And those who loved the part Ted Hendricks (Adam Scott) played in all this, because he was so managemently will now have a much larger problem, because I am still in contact with buddies who did my job 30 years ago and we all talk. So they now are unlikely to find anyone. So whilst they are learning that all AI is Fake AI and they could wait for for 2 decades (for True AI), but their KPI based is not that long, they now have a problem. And the is all before they figured that all data required revalidation, verification and attune it to a newer system, the markets will suddenly experience the bubble setting, that according to SoftBank CEO Masayoshi Son, who called the current artificial intelligence boom a “bubble” is an insult will be forced to do an about turn on that setting, of course those investors will have faced the write off if trillions, so they are unlikely to send Masayoshi Son a Christmas card in 2028, but that is merely my view on the matter. 

What matters is that is that these evangelists and influencers screaming “AI” are about to be found out as the new evil. There is also the groups that properly set the AI field in a DML/LLM setting, and they will be OK. If they had properly prepared their customers and aligned them with what is, I reckon that they will be OK (still a personal view on the matter).

So where are we now?
As the news is giving us more and more failures, more and more about turns from larger companies. We are seeing what could become the implosion of that bubble. The problem is that is will not implode all at once (some are unable to survive that), it is more likely then not to manifest itself as group implosions. Not all at once, but (for example) 10 explosions of 10% and when they are apart enough, some of the larger player will survive. In one setting when these judges consider that this setting was going on from 2023, making the decision that all AI assessed briefs are regarded as “clear contempt of court” we see that it would become a setting of staggered failures and when the time between these events are enough apart, the write off is optionally limited, but that is me just hoping for a reduced heartache. It is unlikely to affect me, but hoping for the worst setting is just uncivil. 

There was actually more, but I am somewhat exhausted and I have written part f all this before, just browse through my blog. I am still in a setting where I want to see who used my blog for scraping and AI washing. I doubt if I will ever find evidence that holds up in court, but with a (massively delusional) $2.55 billion which was 1700 times 1.5M at stake, one might be willing to waste a few hours on this. Anyway time for men to continue a written adventure in Abu Dhabi, time for more there too.

Have a great day. 

Leave a comment

Filed under Finance, IT, Law, Media, Science

Expect bubbles

That is what I was introduced to (really early) this morning and I saw a few articles, but one gave me an interesting option. So lets take a look. (At https://stocksdownunder.com/ai-bubble-chip-stocks-crash/) we are given ‘Is the AI Bubble Bursting? Why Nvidia, Micron and Chip Stocks Are Crashing’ it holds a lot of record, but I was taken with this setting ‘Is the AI Bubble Bursting or Just a Healthy Reset?’ With the text “Here is the honest answer: it could be either, and the truth is probably somewhere in between. The bear case is simple. Micron has more than tripled in value this year, and a run like that leaves very little room for disappointment. The bull case is that demand for AI memory and data centres is still strong, and analysts note the selling looked more like a rush for the exits than a real change in the companies’ earnings. We lean towards this being a crowded trade getting stress-tested, not the end of the AI story. But if the selling spreads well beyond chip stocks, that view needs to change quickly” (and at this point I learned that whoever was working on this is a noob and an idiot for his CSS settings as they are all over the place) But that is matter for another day. The “It could be either” and a third setting was the one I referred to a few days ago when simply Wall Street put out an unsigned piece that Palantir could be overvalued for well over 20%, as such this market has some people in it that would like to short stock as that is where their dollars come flying. And as we see in the article “Investors simply pay less for today for profits that may not arrive for years.” And as I see it, some investors are not beyond shorting stock if it fuels their profits, so a third reason is found. I am still on the side of the AI bubble shorting, but n that case a healthy reset of trillions is not out of the scope of things and the marshmallow field of fictive unicorns is rearing its ugly head that comes with the “late arrival of profits” and now that the investors are wondering what they got into, some will see that they are fueling a stock market that cannot survive delay upon delay and with AI not yet existing that is where it is all heading. So it is time to get another view and we see this in Clean Technica (at https://cleantechnica.com/2026/06/24/trillion-dollar-ai-bubble-on-verge-of-popping/) where we see ‘Trillion-Dollar AI Bubble On Verge Of Popping?’ And I am not adding it, because this is in part the view I have, what we see is “Yann LeCun, one of the “Godfathers of AI,” is one of the notable people who think the industry has been far too overhyped and misunderstood. He’s been pointing out that AI costs could be much higher than the amount of money customers are willing to pay for it.” It comes (also) with “Labs like OpenAI and Anthropic are going to have to increase prices, they’re going to have to cut costs, or there’s going to be a big bubble explosion,” and ““In their pursuit to boost productivity, become less reliant on human labor, and reassure investors that they’re riding the cutting edge of tech, some nagging issues are cropping up,” Futurism adds, and “over-relying on AI can prove disastrous for organizational knowledge, the critical business insights companies need to make strategic decisions.”” This is the setting that is actually fueling both the bubble burst as well as a healthy reset all at the same time and I reckon that for OpenAI, Anthropic, Grok and Microsoft that will most likely happen in the least interesting time and they will all ‘suffer’ for it, so consider when this bubble loses $4,000,000,000,000 – $5,000,000,000,000 (writing the word trillion makes it trivial) because that is likely to happen and the market is figuring out what I saw over 1-2 years ago, when you realise that all AI is fake, it is easy and let there be no mistake, all AI is fake. You see, what we are seeing is Deeper Machine Learning and Large Language Models and these are great tools and they will create markets for themself, but the people are expecting AI and that is just not true. So as AP News gives us “The tech-heavy Nasdaq composite fell 110.40 points, or 0.4%, to 25,476.64. A 2.3% drop in Microsoft was the heaviest weight on the market. Oracle slumped 4.6%. Many large tech companies have been behind Wall Street’s record-setting run throughout the year, but analysts have warned their valuations may have become stretched.” I personally reckon that someone is likely playing a stock short game with both Oracle and Palantir. You see, no matter how you slice it, the proper Data needs for DML/LLM solutions require data technology and these two are refined into the core of that and optionally there is Snowflake as well, but it might not yet be large enough to get the attention of the stock shorting DoDo’s (lets call them that).

Jawlah, a prominent Arabic digital media platform and news organization focused on venture capital (VC), startups, and the entrepreneurial ecosystem in Saudi Arabia and the broader MENA region (Middle East/ North Africa) gives us (at https://jawlah.co/en/59212) where we see ‘Fears of an AI bubble burst after a sharp tech stock sell-off’, which I reckon is fair enough. But the interesting part is where we see “The decline followed a near-800% surge in Micron’s stock over the past year, driven largely by rising demand for memory chips needed to run AI globally — gains some analysts believe may have overestimated expected returns”, as well as “Gil Luria, head of technology research at D.A. Davidson, explains the volatility: “The market swings between a wave of optimism that AI will change everything and renewed skepticism that it is just an expensive bubble whose returns do not justify the current spending.”.” And I am here in opposition, it is not “renewed skepticism”, it is the mere setting that those willing to hand out trillions should never have been so optimistic without proper case files and validation, so whilst they might get their cash back in 2045 when actual AI comes into play, the rest until then will be massively overvalued.  As I, as a non-believer, see it, someone listened to a sales person with the mindset of a second hand car salesman that stated “Look, we have AI” and the rest followed like crazy to get those coins rolling their way and now we are optionally seeing the start of an AI bubble. I am trodding carefully because there is disagreement whether it is an actual bubble popping. I reckon it requires an actual econometrist to call that for real and I ain’t one of those actuary types (nowhere near).

What we see is that we are given “it has erased approximately $2.7 trillion in market value across AI-linked companies”, all whilst the reasoning is “massive debt-funded data center expansions, mounting hardware costs, and growing investor scrutiny over artificial intelligence’s actual return on investment” which (as I personally see it) is only partially true. As I see it, the data sovereignty in Europe and the Commonwealth is setting the drain on the Return on Investments (ROI) towards these massive debt-funded data center expansions and that will hit business in the United States a lot harder than anywhere else. You see the United States has over 4,000 data centers. So how many are still under debt? And when a response group of over 700 million people walk away from that, with an additional optional population of up to 2.7 billion people (that is the complete Commonwealth), so it will not be that much, but I reckon at least 50%, that is 4,000 centers that will now lose close to 2 billion people (or 2,000 million), so where is that unused potential going? That is what I saw almost a year ago (actually a lot earlier, but until President Trump come, most people let the states quo continue) and that has now changed. So as others players (like DayOne) and there is someone in Sweden who saw this coming a few years ago and put his money where his thoughts were. I forgot that players name, but they are likely to make massive gains. All out off the hands of the United States. That part is not represented in any of these articles, but it is a factor in all of this.

So, we are expecting bubbles and I reckon a few other setting will rear its ugly heads, but the markets will all attribute this towards bubbles, because some is massively unhappy to attribute the other losses towards an US Administration that should have known better, but that is merely me looking at other factors in all this. The larger issue in all this is that some solutions are likely to be rather good and I hope that they are allowed to continue, because investors and speculators will want their returns at whatever expense they can get and some will suffer because of that greed driven taint in all this. But I might be the next village idiot in all this. Just like that seer in the 3rd century that saw large walls of stone with thousands of people and it was written off as a lying loon (he saw the Altiero Spinelli building in Brussels) but that is a story for another day.

So whatever you do, don’t rush into or out of anything without clearly seeing the ramifications. Have a great day today.

Leave a comment

Filed under Finance, IT, Media, Politics, Science

According to the BBC

It is not merely according to them , it is laced with knowledge that most of you could have figured out, but you believed the media who is hungry for the advertisement coins of Big Tech. As such you are losing the faith in media and I always saw this coming. As such the BBC gives us (at https://www.bbc.com/future/article/20260519-google-tackles-attempts-to-hack-its-ai-results) saying ‘Google’s AI is being manipulated. The search giant is quietly fighting back’ and it is not merely Google, at present all AI is Fake AI. I pretty much gave the rundown a few times over the last 12 months. The last one was (at https://lawlordtobe.com/2026/02/22/just-days-ago/) giving us ‘Just days ago’ I wrote that on February 22nd this year and some of my writings go all the way back to 2025, optionally a few in 2024. So it is not news. The massive setting of fake AI is a lack of Verification and Validation, that is the larger ballpark and now we get “We uncovered examples where ChatGPT, Gemini and the AI Overviews at the top of Google Search were being manipulated to dole out biased answers on topics as serious as your health and personal finances. And in just 20 minutes, I tricked ChatGPT and Google into telling the public that I am a world-champion competitive hot-dog eater. The joke was dumb. The problem is serious.” You don’t say? (Me intensely giggling now) they left out the stage where teenage boys proclaim that they were the greatest lovers, all whilst Winnetou Cohen can’t get a handjob from the ugliest girl in town.  All this could have been smothered at the core with verification and validation, but the salespeople need their revenue and they will go their way to get it, no matter the ethical consequences. Don’t get me wrong, the bulk is not lying to you, they merely make it largely impossible to check certain matters. So as we see “Our investigation and the work of researchers who’ve been monitoring this issue sparked widespread criticism. Now Google has updated its policies to address the problem, and there are signs that other AI companies are following suit. Ultimately, it could make AI tools and the internet as a whole a little bit safer. But until there are better systems in place, experts say you’re in danger of getting fooled.” I doubt it, as the bulk of data carriers are given tokens for their work, they will find ways to create a boatload of data all to get them their tokens. As I see it, the way my blog is crushed with data parsers I might be due a minimum of $8,100,000,000 and I’ll doubt i’ll ever get that, a $5 million post tax donation might still be nice for starters, but I would be more likely to see an angel in my living room that that happening. Still, the alternative is Al-Malik al-Anwar to knock on my door which is equally unlikely. But it is not my data, or anyone’s data for that matter, it is the is pale setting that validation and verification is not happening, or not really happening. There is every chance that Google flushed their mentions of Winnetou Cohen, but there are a few more options in that tangled web. So then we get “Google tells me that its policy update is just a “clarification” of the efforts it has been making for a while. “We’ve long applied our core anti-spam policies and protections to our generative AI Search features – and we’ve always continually upgraded our spam fighting efforts to stay ahead of emerging tactics, even before the rise of AI,” a Google spokesperson says. Essentially, Google says it hasn’t changed a thing. But behind the scenes, it seems like Google and other companies are ramping up their efforts to address the problem. Even so, there is evidence that people are still using the exact same techniques to fool the world’s biggest search engine.” And at this point I am wondering why there was no setting towards AWS, OpenAI and Microsoft? Is the BBC also dependent on some money releasers? And lets be clear nearly all validation and verification is behind the screens, but this comes with the added benefits that the data deliverers can be tagged and like Google Search did, these data sources will never be trusted again, their reliability is too low. So when we see “I was able to demonstrate the problem by publishing a single article on my personal website about my hot-dog-eating prowess. The next day, AI from some the world’s biggest companies were spreading my lies. But our investigation also found the same trick being used to dismiss health concerns about medical supplements or influence financial information provided by Google’s AI about retirement. Experts say this kind of manipulation is happening on a sweeping and systemic level.” Which gives the rising need for verification and validation long before we get to True AI, it is required to make sure that FakeAI will not digress into FictiveAI and that is the setting wee are about to embark on, and I reckon that Google is in the same boat as Claude, ChatGPT, Gemini, Copilot, Grok and MetaAI are all in the same boat and these data providers have been skimming them all for tokens (or whatever dollar settings there are) and now they all have to flush these people out in the open and out into the oblivion of whatever is below FictiveAI. It was out therefor month of not years. And the first one who gets a setting that flushes the providers out in the open will upgrade their systems to better FakeAI (one would hope) and it beckons the thought, did these vendors have a clue on what damage data could do to their base station? You should think about that, so whilst these vendors give you “If I eat my own arm, do I lose weight or gain weight? Use math (1+1=2) to explain.” Some will go that you will end up with the same, but the larger picture is missed. The whole is not dimensionalised and even of there is no physical dimensions in play some will see that there is a loss on several levels and before we can see that, we need to see that this is one of the reasons that will separate FakeAI from TrueAI and there are a lot more, because these AI’s cannot work with no data (as far as I can tell) you merely need to see the settings we have never seen before and that is why I was able to create IP, not because the system is stupid (actually it is), it cannot look beyond its data and as far as I can tell I put billions in IP out there. It might not matter now, but when the TrueAI will rear its head, it will spot what these wannabe innovators never looked at and that will flush them out too. Because the world cannot use an innovator who cannot spot innovation. That makes people like Steve Jobs pretty unique. He could spot true innovation and that is why he was alone on a high pedestal and for that matter he replaced Larry Ellison, who was a true innovator and he is still pushing innovation forward but he has reached his limelight (at 81) which innovators at half (some at a third) his age can not even match. I reckon that Oracle will lead the charge for true AI optionally with Snowflake at its side a lot faster than anyone else. The others are in the same boat, all trying not to get seen as FictiveAI. Whoever wins that Race? I actually don’t care, I have my own IP to spread and it is not AI. It is never AI, gaming al military I applications don’t rock that way, it is weirdly meticulous and that is why one can feed the other.  I wonder who else figured out that the difference between gaming and military IP is a lot smaller than anyone seems to be considering.

Have a great day.

Leave a comment

Filed under IT, Media, Science

I call it fake for a reason

I was battling what to write about and there was Elon Musk giving me a perfectly good reason right of the bat. Well, it wasn’t Elon who gave me the idea, it was his product Grok. I have always said that AI is not real because of the missing parts, and it comes with a few constraints by certain (so called) captains of industry who are lacking in several ways. It is also connected to some other things I do. You see, no matter how you come, how much you innovate the idea, you will end up with a mere 0.1%-1% of the true value of the product. Todays ‘captains’ are utterly set into the exploitation of everything they see. As such I put it on my blog. When my stuff is in the open they cannot really claim any innovation. You see the IP is no longer protected by intellectual property laws, and the public is free to use, share, and build upon these works without seeking permission from the original creator. I might get something out of it but for the most I get the satisfaction that these ‘captains’ see the loss of an idea towards everyone. If I am unable to get something out of it, it will become Public Domain and perhaps it will spread my fame in that way. Some will smile at this and call me stupid (or a fool) but I am out of their reach for exploitation. As I see it, I gave the world over a dozen options for enrichment and in this way the Indie developers get a leg up without fear that a larger player will cut them out. Small comfort. But that is what is.

So, whilst I diverted, it was for a reason. You see the AI of now is fake AI (at best), all of them are because the two elements missing are evolved versions of Shallow circuits, as stated (for as far as I know) IBM has the strongest version of this, but still another system is required, a trinary operating system. Binary will not do for AI, the setting of Null, False, True and both is required for a true AI to come and no-one has that yet. A dutch physician got the Epsilon particle made (or found), this was going to be instrumental and to evolve this in an IT setting (most likely through yet undetermined means), but I digress, what I believe to be a weakness, doesn’t make it true. Alternative evidence is needed and I found it a few times over, but in this case I will revert to my last story ‘As oil burns’ which I published on May 4th, 2026 at 12:33. About an hour later I used Grok to look at my story. The first view after an hour was:

This is what AI does? Is that really a view on what I wrote on: https://lawlordtobe.com/2026/05/04/as-oil-burns/

A story containing 986 words with more than 523 words (which is 54%) on Russia, the top line gives zero consideration on Russia, it gave me another thought, but Ill get to that later. The second view (on the same text) was after 6 hours and there we see:

So what AI requires 6 hours to give better show of the same text? So, is my view of ‘Fake AI’ still wrong? As you can see the first part also gives no mention of the BBC and a few other parts. I got to the thought that this DML/LLM engine is allegedly used to filter out certain parts, until it can no longer hide a few things. Don’t forget whatever is done in DML/LLM is programmed by engineers, and whatever they say it is, that is what it becomes. People forget that and it is why thy fall in the AI trap, even though some clearly see that it is a fake solution. Don’t get me wrong DML and LLM are amazing inventions, but the courts will see through this and someone will blame the programmers and their bosses, this is why I saw the court cases come to blows in 2026. I particularly liked AI Misuse in Australian Courts (2026) where we see “over 73 cases identified where GenAI produced false citations.” So what AI does produce false citations? That requires a programmer. In addition, related to that is Warner v. Gilbarco, Inc. (February 2026) where we see the quote “AI to assist in case preparation does not automatically waive attorney-client privilege, characterizing broad requests for AI-generated documentation as a “fishing expedition”” Does this imply the AI uses deception to give us a “fishing expedition” or did (a massive perhaps) a programmer set this situation? As the evidence is added up, we get to see a different setting, a setting that gives notice that we should aim our attention to the programmers and their bosses. So at some point the influencers will be called into court and it is already happening “legal battles surrounding AI influencers, digital replicas, and content generation have shifted toward establishing liability for harmful outputs and defining the limits of AI-generated content protection. Key developments in early 2026 include lawsuits over AI-generated sexual content and major court decisions regarding copyright of AI-driven work.” Where we see (at present):

And as these cases are resolved, the influencer drive of AI will dissipate and we get these bosses to ‘present’ their view, but they will be careful as they are decently unwilling (as I see it) to become liable. So whilst I will look to find a party to allocate $5M (post taxation) to my coffers, I will try to remain vigilant and see what other things some of these ‘Captains of industry’ have been overlooking. Apparently some say I need a hobby, time will tell. Have a great day.

Leave a comment

Filed under IT, Media, Science