Tag Archives: verification

Reasons for a ban

That was what I saw and I questioned it, because when any White House bans a media station as vanilla as CNN, something else is going on. And I have been on the fake news setting for months and there are enough of them to give shouts on, but CNN? That’s like banning vanilla for being non-chocolate flavored. It almost makes no sense. Almost being the operative word. So I started to look deeper and by jove, I’ve got it. You see less than 24 hours before the ban CNN gave us an article named ‘The real reason for Trump’s pedal-to-the-metal approach on AI’ written by Allison Morrow. Yes, yes, his favorite kind of journalist, a girly girl that does not care about his ‘delusional magnificence’ gave us a few real questions to wander about and that could have been the reason for banning them (I merely said could). You see the story (at https://edition.cnn.com/2026/09/18/economy/trump-ai-economy) gives us a few hard settings. The first being “President Donald Trump is suddenly at odds with AI’s leading executives over the largely unchecked development of AI technology. And it may be because our economy can’t afford a slowdown.” A view I have had for some time and there is a chance that some are waking up to the real peril the United States its in. And I think it is the realisation that “Trump’s pedal-to-the-metal approach suggests he may be more concerned about a bigger question: What happens to the US economy if the AI fever breaks on his watch?” And I get it, all this fake AI and people might wonder what happens when this fake AI gets to show the weakness of its fakeness and starts asking (en masse) the questions the media (in a world according to Trump), needs to hide for the good of America. This setting has run its course and the problem is that these questions are coming to the surface of nearly all fields and there is not much that this president can do to prevent that from coming to the surface. He could ban them to the White House and have them fish behind the netting what have been fished clean. That is what he might be thinking, but the story isn’t that pretty. So when we get “There are a lot of ways to slice the metrics on just how dependent the US economy has become on AI (and AI-adjacent) spending. ING estimates tech investments dominated by AI and data centers account for a third of year-over-year economic growth in 2026. Goldman Sachs’ chief equity strategist recently told CNBC that AI investment is driving half of all the profit growth in the S&P 500.” But I have said it on several occasions. Considering that nearly all of the “AI investment is driving half of all the profit growth comes without a return on investment for close to a decade” so what happens when there is no coinage linked to these investments? That is the question that the media to the largest degree is mismanaging. Now we see one article that brings that to the surface and they are banned?

So has anyone looked at Stargate LLC lately? A planned $500 billion investment over several years, it was going to be such a beautiful solution, all whilst there is no return on investment planned for the better pat of at least a decade and it will (according to some) create over 100,000 American jobs, so in this age of mass redundancies. Did anyone consider what happened to that project which was last years great solution? 

So what happened to OpenAI (operational responsibility), SoftBank (financial responsibility and chairmanship via Masayoshi Son), Oracle, Microsoft, Nvidia, Arm, and MGX? I am merely asking, but in light of this CNN article, these questions also come to the surface. As such questions in the open and whilst CNN gives us “AI bulls believe it is the defining technology of our time, and that the stratospheric share prices it’s creating are just one of its many benefits. With widespread adoption in the future, the thinking goes, AI will turbocharge productivity the way the internet did at the turn of the century.” What matters now is that all this AI is fake and no one is wondering what happens over the next decade, because these data centers are in some form currency and when fake currency comes into the main setting of everything there is a bitter aftertaste and this is now seemingly surfacing. You see, the only real AI that we should embrace is now called ‘true AI’, but this is the AI that Alan Turing wrote about in his papers and if True AI is AI, then all the other puppies called AI become fake AI and that is the fear that President Trump has, because when the people realise that all the AI settings are fake, president Trump’s economy is collapsing near immediate and that is the real fear he has. So whilst he will come with all the film flam talks he can and how ‘amazing’ these AI players are, they need to see that all this fake AI is merely Machine Language with Deeper Learning and LLM in places are real solutions and they are at times great, but it is not AI, not even close and that is the setting they are all hiding. A sales talk that was placed in an overreaching setting and it s now coming to light. And this multi trillion dollar bluff is coming to bite all the players in the ass and whether it is a validated setting is beside the point.

And all along we now get OpenAI giving us ‘OpenAI reveals six more safety issues and unveils plan to disclose incidents’ (source: BBC) but first we need to conclude a few parts in the CNN article. You see we are also given “The icing on the cake, said Sonola, is the wealth effect. People with stock portfolios exposed to AI are feeling flush, and they’re spending lavishly — further helping prop up America’s consumer-centric economy. Whatever people’s personal beliefs about the technology, the money going into it is keeping the world’s biggest economy humming. If that money train stalls, the effects won’t be contained to tech investors on Wall Street.” Which is finished by “Last week, ratings agency Fitch ran a scenario imagining the economic outcome of an AI-related downturn, with US stock prices falling around 35% over six months, roughly the median decline of past financial busts. The result was that the economy would go into recession, with GDP contracting 1.5% next year. To be sure, there’s no guarantee, or even specific indication, that the music is stopping anytime soon, and Fitch noted that “a sharp decline in US equity prices is not our base case.”” Butter is the real danger, the US economy can never survive a 35% stock drop, I am willing to guess that even a 15%-20% drop in stock prices fall will basically end the US economy. That is the dark side of a $40 trillion billion bill with interest due every year (optionally paid in months) but that will end all of this quite quickly. 

So now we get the BBC piece and we get one little gem there. It is “In the blog, OpenAI detailed examples of its AI models misbehaving so they could achieve a task or succeed in a test. The incidents included the models generating instructions to get around restrictions imposed on them, hiding mistakes and fabricating information. The firm also announced a new system to track, investigate and disclose cases of models misbehaving, or “misalignment”.” Now consider that this is Machine Language with Deeper Learning and not AI. So when will someone ask the programmers what is going on? I reckon these people are filtered away into ‘protected’ jobs. But the question remains and the effect on OpenAI with its operational responsibility to Stargate LLC is largely ignored and these questions are surfacing now, not just by me, but all over the field. And the investors are starting to get worried about the money they put into this, because those investors will lose a lot more than 35%. So when did you last see any investor not worried about his investment? I’ll hold the egg timer, you go look and the answer will scare you, because all this is pushed to nearly every corner and these corners are quietly praying that no one will wisen up, because it is their livelihood that is under fire at present. We get Google Gemini telling us (yes, I see the hidden hypocrisy there) “Artificial intelligence isn’t just replacing tasks—it is actively fueling and creating millions of new roles while transforming billions more. Rather than a simple number of “AI-fueled jobs,” major economic and labor data point to a massive wave of job creation” but the smallest setting is not investigated. How to validate and verify  the so called AI data. So far there is not much of this going on and these are the massive requirements, because AI that runs on invalidated data and unverified data is by definition fake, so who is looking into that? Because if you cannot see these parts, what are you looking at?

Just a few little questions to ask and now wonder what parts did Politico get right? Perhaps it was ‘Poll: Americans say there’s a serious risk of AI destroying humanity’ three days ago. So as I see it there is something a lot more scary than the Epstein files. The knee-jerk actions of President Trump indicates this by his scared demeanor. 

Have a great day today.

Leave a comment

Filed under Finance, IT, Media, Politics, Science

Changing the byline

That is the setting I see and whilst the BBC (at https://www.bbc.com/news/articles/cqgk5e2j0gg8o) gives us ‘AI ‘kill switch’ may need to be mandatory, Anthropic co-founder tells BBC’ a mere 5 hours ago. I had my thoughts. So, as we see “An artificial intelligence “kill switch” which can be checked by a third party may need to be mandatory for companies, a co-founder of one of the world’s largest AI firms has told the BBC.” I see something different. So when we get to “Clark said “most labs have different ways of being able to pull the plug”, including Anthropic, but said lawmakers may need to enforce having one. AI’s rapid development and fears over the risks it poses to humanity have been thrust into the spotlight by a series of warnings from executives and staff at AI firms.” And when we get to “Anthropic chief executive Dario Amodei over the weekend called for the pace of AI development to slow and be more closely monitored, as the company has done before, though some have questioned the motivations behind this.

Amodei added that any action to rein in AI development should be done “without sacrificing commercial advantage”.” Thoughts started to overwhelm me. Some people state that the setting is about “AI’s rapid development and fears over the risks it poses to humanity” I don’t think that is the case. I merely think it is what some will ‘present’ the setting that we are given and most people are willing to go along with that. There is however a larger concern. You see I have had my meetings with these AI boffins and they all have the same setting towards validation and verification that is in play. There isn’t any of it, and when it is there it is there in the most ludicrous basic ways. You see, there is just one step (just one) from AI hallucinations (which is a confident response from an artificial intelligence system that contains false, misleading, or completely fabricated information presented as fact) and it is seen as Invented statistics, historical errors, or nonexistent legal citations, as well as Citations to books, research papers, or URLs that do not exist. I have seen this and I have seen that the settings that this represents to court cases are numerous and we have seen n the news several settings. But the larger concern is that between that and an AI actually overwriting factual matters of any corporations is only one mere step and these fake AI vendors are insulating themselves from that fact by ‘employing’ a kill witch, so that they can avoid getting called into court by setting the stage of ‘Did you use the kill switch?’ And that  is the setting I see. So whilst we are given (by the BBC) ““Should you mandate for companies to definitely have a kill switch? Is that kill switch verifiable by a third party?” he asked.

“I think that’s the kind of thing society is going to want to know and might want to eventually pass rules around.” Anthropic, which was formed in 2021 by a group of former employees of its rival OpenAI, is currently at the centre of a debate around AI safety. Last week, a post from an artificial intelligence researcher who quit Anthropic over concerns AI could wipe out humanity went viral.” So is this really about “over concerns AI could wipe out humanity”, you do know that Cyberdyne is just a figment of the brilliant director named James Cameron, it was ahead of its time and we aren’t nearly there yet, but the kill switch scape goat is one way to counter the class actions heading their way and whilst some can’t be avoided, the larger concern is what will happen in 2027, because that will be the truncator of their wealth and they are seeing the stoplights and they want to insulate themselves from their fake AI. They rode the waves as much as they can, but the first blockages are showing and now the cautious people are rearing their heads. I see all the complacencies showing up (like figment court cases) and that is merely the beginning, but the setting that corporations factual data is overwritten or wiped is only one step away and I reckon that these people want to insulate themselves and as they are coasting their vessels of wealth towards sunny shores, they have no other option but to insulate themselves and their wealth. 

Funny that I saw these court cases come up a long time ago. I never saw this part, but this part makes sense. When your training data is based on reddit (whilst we are given “Major AI companies train their models on nearly all of Reddit’s public historical archive”) is this continuation of dangers weird or unsuspected? As I see it, when even one factual data is overwritten by some fake AI juiced up on reddit, the setting gets ugly in a hurry. And that is what these people are ‘misrepresenting’ and crying now for some kill switch, because the kill switch is not for the AI, it is their escape clause. So whilst you might doubt me (always a fair setting) I have written about the fake AI setting for the longest time. 

So someone asked me what makes binary AI surreal? I give them the same setting every time. Take any colored image (example 600 by 600 dots) and run it through plotter printing only black and white dots on a colored piece of paper (green, red or blue) then do it on the same kind paper and instead of black and white, add the option to do this in black, white and 16 greyscales. You will see that this image is much more precise and revealing. This is the setting between binary and trinary this is why all AI is fake and it gets to be worse when you consider that you need a lot more data describing in binary what requires trinary and that is why I was on this horse all along and I have been on it for over 10 years, but the players all think that they have the golden goose and I merely cannot see what it is. Well, It is ‘advanced’ predictive analytics. These AI cannot reason, they work the numbers, go with statistics and it is nice if it is a set field, when they go towards never encountered situations, it all falls apart. This is the weakness of these fake AI’s and it is not whether I hate AI, I merely don’t trust it, because it is not AI, and Alan Turing would have my back on this. 

So whilst you think that I am “Full of Sh*t”, which is your right. My predictions are given form through my blog and in 2025 I predicted that 2026 was the year of AI class actions and now we see “Broadridge’s 2026 Global Class Action Annual Report highlights that global class action activity recently produced around $4 billion in settlements across multiple jurisdictions from roughly 130 major claim-filing deadlines” as well as “According to the Duane Morris Class Action Review, the combined value of the top 10 highest settlements across all substantive areas previously crossed the historic $70 billion mark, showing how massive individual mega-settlements drive the ceiling of total class action value” and “In the U.S. and global financial sectors, recovery momentum has accelerated into 2026, with an increasing number of nine-figure and $100M+ securities settlements closing out the mid-year milestones”, as such my predictions are holding up neatly. And now these vendors need insulation and they are thinking (optionally correct) that a kill switch might take the dangers to their wealth away. And I get that these fat cats want to insulate their wealth and insulate the dangers to them, but the BBC should have a greater need to look into these dangers and that is why I took this article as an example. I reckon that it is not only the BBC going after this. As I see it, Dario Amodei, Sam Altman and Elon Musk are all in agreement to slow down, but I reckon it is because they are seeing the dangers heading for their assets and they are in it too deep (as I personally see it). 

As I see it, this is the heading that we are seeing happen and soon there will be some (optionally fictive) revelation and that is when the stage changes and we will see massive amounts taken out of the AI field. When that happens there is no Jensen Huang claiming that there is no bubble, the court cases that will be an exploding setting will shut that down in a hurry. 

But what do I know? So you all have a great day today and I will be watching from the docks watching the good ship bubble explode near the parking zone. And I can say this whilst I have been preaching these dangers for nearly a decade. Where exactly where you a decade ago? Consider this setting and enjoy your day. 

Leave a comment

Filed under Finance, IT, Media, Science

Today’s village idiot

There is a setting I have kept my eyes on, because I have had more than one issue and it is time to be the not so nice person. So whilst we see LinkedIn giving us:

The ‘small’ fact that two people checked me out. The reality is that the profile viewers, the ones we are given 

Give us that a minimum of three were there in the last day, I know for a fact that at least two additional people locked at me in the two days preceding that and I know for a fact that at least 2 more watched me, but I have no idea who they were. That gives us the following setting (because LinkedIn is part of Microsoft) It implies (using pig calculus) that LinkedIn is only 22.2%-28.5% precise and the setting is that they are even not that accurate. So are you willing to give your data and hard earned IP to a setting where they are at best 28.5% accurate? How will that go for you, your company data and a lot more. And the art of tally has been around for over 5000 years, some people might have explained that to their village idiot in 1095 (when the poor got ‘drafted’ by the local ‘faithful’ for the Crusades). And these idiots are optionally better tallyman than LinkedIn/Microsoft? Go cry me a river, please.

So whilst we are given (from diverse sources) “Inflated Applicant Numbers: The “X applicants” number shown on job listings tracks how many people clicked the Apply button, not how many actually finished or submitted an application.” As well as “Algorithmic Hype: The feed often rewards “flex culture” and exaggerated success stories, making normal career struggles feel abnormal or invisible.” (Source: Google) 

I am speculating that there is method to their insanity. The United States is eager to get financial data of any kind and this is where LinkedIn (optionally Microsoft too) is getting their ‘more value’ You see, there is the setting for premium and you do get a month for free, but the issue us that they do not give it out simply because it is free, they will optionally collect bank information and that gets matched to all kinds of data, completing a whole range of global data, this is what they are after and speculatively getting the numbers game drawn back, is their option to get more data and in that setting, I foresee that this is the goal they are after, because they don’t care about me, or you or anyone else. Their setting is all that data and to get that matched to financial records is what I speculatively expect to happen, which is turned to Microsoft gold (as the expression goes) and as there are a few less credible settings in all this, Microsoft (read: LinkedIn) is going for all the gold they can muster, because as these data centres are tuning up, the one with the best validated data source will become king and bank data is massively verified and validated. 

Anyone willing to give this setting a disagree status. Feel free, but be sure you see what you are missing out on and the examples I gave was merely me, so whilst Google is giving us “LinkedIn has over 175 million to 180 million Premium subscribers globally out of a total network exceeding 1 billion registered members” as such 1 in 10 is premium and as such these bank records (most of them) are the one tuning match in reverse other settings. And in all that there are likely a few PayPal and several Google Credit settings, but there will be a massive amount of bank details there and that is what Microsoft is after, because that gives them the validation and the value of other databases (this is speculative, but that is what I would do. A bank reference will be seen as printed money for LinkedIn/Microsoft. Is there anyone out there who fails to see that picture? We are now data and data needs to be linked using verified (and validated) options. 

So have a nice day and should someone come in stating that these numbers are so complex, remember the story of the village idiot and the fact that the tally has been around long before there were computers. And whilst we can review the setting that Satya Nadella gives us and in his 

view artificial intelligence not as a static tool or a singular model, but as a foundational ecosystem that transforms firms into active learning system. They have owned LinkedIn since 2016, as such there is not much learning going on if they fail the tally test that a village idiot could do, because most of them could tally to 10. And in that setting they got (at best) 28.5% correct. So how about them facts? 

This is what I see, and what I speculatively think is their goal. (I could be wrong in that part) but the other parts? I added the pics to give voice to my setting. How about yours?

Have a great day

Leave a comment

Filed under Finance, IT, Law, Media, Science

Is it the water level?

Yup, we are all in that setting, but are we merely waving to the music of Debbie Harry or are we watching the waves from the shorelines. That is merely two options, but when some say that the tide is high, they might be referring to bubbles, the AI bubble to be more precise. I am not some economist saying that bubbles are blasphemy and I am no economist, but I have looked at numbers for decades and the numbers we are given do not add up, and when I was watching Inside Job something hit me, there was a familiar pattern evolving, not evolving, repeating is a better word and I have been saying this for some time. Yet today, a mere 10 minutes ago I see ‘UK Places Microsoft, Google, Amazon And Oracle Under Financial Oversight’ (at https://www.businesstoday.com.my/2026/07/10/uk-places-microsoft-google-amazon-and-oracle-under-financial-oversight/) where we see “The UK has placed Microsoft, Google, Amazon and Oracle under direct regulatory oversight after designating the cloud service providers as critical third parties to the country’s financial system. Reuters reported that effective July 13, the designation covers Microsoft Ireland Operations Ltd, Google Cloud EMEA Ltd, Amazon Web Services EMEA SARL and Oracle Corporation UK Ltd, reflecting the financial sector’s growing dependence on cloud infrastructure”, so whilst the story ends with “The designation will bring the four technology firms under direct regulatory oversight as part of efforts to safeguard the stability and continuity of the UK’s financial sector.” And it comes after we were given (at https://m.au.investing.com/news/stock-market-news/oracle-stock-shrugs-off-sp-downgrade-to-bbb-but-120b-debt-shadow-looms-4526441) where we see ‘Oracle stock shrugs off S&P downgrade to ’BBB-’, but $160B debt shadow looms’ where we see “Oracle Corp. (NYSE:ORCL) shares managed to gain 2.7% on Thursday, defying a credit rating downgrade from S&P Global Ratings. While shares edged slightly lower from their midday highs, the tech giant still traded firmly in positive territory. Investors chose to focus on Oracle’s staggering $638 billion backlog of cloud contracts rather than the immediately apparent threat to its balance sheet: S&P downgraded Oracle’s long-term issuer credit rating to ’BBB-’ from ’BBB’, retaining a stable outlook.”

Now, I am not having anything against Oracle. They have always been on the foreground of technology and innovation in its field and it is unlikely to ever change. But there is a larger setting, the entire AI bubble as I see it, it will hit them too. They all over invested in that setting and they are likely the biggest catchers of the implosion of that event. But I am still in arms over ““The official position of the Secretary and the U.S. Treasury is that Artificial intelligence will be a key driver of America’s new Golden Age,” the spokesperson said. “AI has the potential to deliver unprecedented productivity gains, expand economic opportunity, and empower American workers and businesses.”” You see, there is no golden age, there is no AI, not yet at least. There is DML and LLM and they are great, they can hand innovation and prosperity in several ways. It merely isn’ AI and that needs to be said, because soon the class actions will go for the “It’s AI and we cannot really predict what AI does” but it isn’t, it is DML and that requires a programmer, it requires data and these two hinder stones are the backdrop for prosecution. Only last week we were given ‘Anthropic Faces a New $75 Million Lawsuit for Pirating Books to Train Claude AI’ and less than 24 hours ago Harvard Business Review ‘You Outsourced the AI—but you still own the risk’ where we see “As enterprises increasingly embed third-party systems into their workflows, technological risk has led to new legal and operational responsibilities. Leaders may have little visibility into how a model was trained or how it changes, yet when it discriminates, mishandles data, or harms a customer, regulators and plaintiffs often look first to the company that deployed it. Peloton learned how that exposure can arise. Visitors to its website see a familiar invitation to “chat,” powered by a third-party vendor. According to a class-action complaint, the vendor recorded and stored conversations and used the data to improve its machine-learning models. Peloton neither built nor trained the system. Even so, a California federal judge allowed a claim against the company to proceed. The parties later jointly dismissed the case, without publicly disclosing the terms.”

Now consider the amalgamation of these factors (apart from some saying there is no bubble) there is (allegedly) “Worldwide spending on AI is forecast to reach $2.5 trillion. Venture capital and private corporate investments in AI firms sit near $258.7 billion globally, with over $750 billion in dedicated infrastructure and data center capital expenditure from major tech hyperscalers” we then see that the big players (Microsoft, Google, Amazon, Oracle) are basically overextended, facing class actions and all of them are looking at all sorts of financial hardship, because at some stage all these players will be made to rephrase the simple truth that AI is not DML/LLM, it requires more and when the programming is put under a loop that setting comes crashing down. I saw it two years ago that this is the only outcome in some sales people overselling what they had and the simplest setting is not a mere Quantum computer. It requires shallow circuits and what I tend to call The Epsilon processor. True AI cannot exist in a binary setting. The last one is my interpretation of it all and some might disagree. But the Epsilon processor allows for Null, False, True, Both and it is the Both part that makes true AI possible and of course a matching operating systems will be required as well a data carrier and in that case Oracle and Snowflake have the grounds for success. As I see it, all others will fall behind these two. 

And last month we were given that “400 newspapers sued OpenAI and Microsoft for scraping their content without permission or compensation to train artificial intelligence programs” even my data has been scraped. So how many will be successful? How many will fail? I have no idea, but the odds are decently stacked against these salespeople. And as the courts rule against these Fake AI bringers (as I see it) there will be a rush of people making a case, all who were sold AI (without clear DML/LLM settings in their contracts) are seeing their pupils transform into dollar signs and they will try to clean house. So when all these settings happen, is the stage for a bubble that far fetched? 

I am watching and watching and noting what is due. I reckon that at some point I get the one piece of evidence that will allow me to do just that, 2700 (out of nearly 4000) article scraped seemingly give me an optional case for some dollars (five million plus would be great). And I am not the greediest player in town. So at what point will the investors of $2.5 trillion ring the bell wanting to see payment for their investments? Goldman Sachs gave us last month ‘The AI Investment Boom: When Will It Pay Off?’ With “The economics of artificial intelligence are more questionable today than two years ago, says Goldman Sachs Research’s Jim Covello, as enterprise buyers, model companies, and hyperscalers have yet to show returns on their spend. In a conversation with Alison Nathan and George Lee on Goldman Sachs Exchanges, Covello discusses where we’ve seen economic value accrue to date and why semiconductor companies can’t continue to be the sole beneficiaries of the AI buildout.” As such we see people with serious economic skills worrying and wondering what comes next and I was there at least a year ago. So when will others see the doubt that I am seeing? The money people call the bubble a blasphemy, but they have vested interests. I do not. I merely see the flaws on technology that is at least 15-20 years away, data that is largely unvalidated and unverified and at this juncture people are investing trillions? Makes me all tingly that too many people are greed driven and too much vested to be part of a boom that does not exist, just like the settings of 2008, Inside Job showed that clearly and it seems that we have a similar setting evolve at least two times the previous caper. So if you consider that with all the reserves that hit took the economy 2 decades to fix and at present the reserves are gone, so what will happen now? Why aren’t others taking the stand the UK is making? Because others are in the believe that “America’s new Golden Age” is here? When you realize that it will take close to two decades to arrive, how long until too many investors pull the plug and go somewhere else? What will happen then? That is what I see coming, because at some point more and more people wake up, this is bound to happen, it always does.

So is the water high enough? Have a great day.

Leave a comment

Filed under Finance, IT, Law, Media, Science

The setting of the sun

That is what I saw, the setting of the sun. A simplistic setting that was about to happen since the sun came up. We got the news from the BBC. And we are given ‘I hacked ChatGPT and Google’s AI – and it only took 20 minutes’ I can see how this happens. It doesn’t surprise me and the story (at https://www.bbc.com/future/article/20260218-i-hacked-chatgpt-and-googles-ai-and-it-only-took-20-minutes) gives us the niceties with “Perhaps you’ve heard that AI chatbots make things up sometimes. That’s a problem. But there’s a new issue few people know about, one that could have serious consequences for your ability to find accurate information and even your safety. A growing number people have figured out a trick to make AI tools tell you almost whatever they want. It’s so easy a child could do it.” I think it is not quite that simple. But any ‘sort of intelligent setting’ can be fooled if it is not countered by validation and verification. It can give way to way to much ‘leniency’ and that is merely the start. Get 10,000 pages to say that ‘President Trump was successfully assassinated at T-15 minutes and the media will go into a frenzy in mere minutes and everyone uses that live feed in a matter of moments. So when a sizable Trolling Server farm connects the rather large settings of consumers to that equation the story is brought to life and that AI centre will be seeking all kinds of news to validate this, well not validate, the current systems corroborate. Now, lets face it, no non American cares about President Trump, but what happens when someone takes that approach with for example Lisa Su (CEO AMD) and stops her accounts whilst seeding this setting? You get a lot of desperate investors trying to place their money somewhere else. Whilst the trolls take their money, make is legal tender and buy all the stock in space and when the accusations are rejected they sell their shares with a nice bonus. Think I’m kidding? This is the result of Near Intelligent Parsing (NIP) but it cannot work without clear settings of validation or verification. So whilst we get “It turns out changing the answers AI tools give other people can be as easy as writing a single, well-crafted blog post almost anywhere online. The trick exploits weaknesses in the systems built into chatbots, and it’s harder to pull off in some cases, depending on the subject matter. But with a little effort, you can make the hack even more effective. I reviewed dozens of examples where AI tools are being coerced into promoting businesses and spreading misinformation. Data suggests it’s happening on a massive scale.” So what happens when economic settings lack certain verification and also is cutting corners on validation? Do you think my settings are far fetched? 

This was always going to happen and whilst economic channels are raving about the error of mankind, consider that “AI hallucinations are confident but false or misleading responses generated by artificial intelligence, particularly large language models (LLMs). These errors occur when AI fills in data gaps with inaccurate information, often due to faulty, biased, or incomplete training data” now think of what someone can achieve with doctored training data and that gets added to the operational data of any fake AI (NIP is a better term). This is the setting that has been out there for months and whilst organisations are playing fast and lose with the settings of credibility (like: that doesn’t happen now, there is too much time involved), someone did this in 20 minutes (according to the BBC), so do you think that Thyme is money, then you better spice up because it is about to become a peppered invoice (saw one cooking show too many last night).

What we are about to face is serious and I personally think that it is coming for all of us. 

So have a great day and by the way? And I just thought of a first verification setting (for other reasons, as such I keep on being creative. So, how is Lisa Su? #JustAsking

1 Comment

Filed under Finance, IT, Media, Politics, Science

Fear of being right

That is what I face at times. I get that my ‘idea’ of safety is a little overdrawn, but I have seen the stupidity of greed driven and how those seeking the stupid and greedy are willing to exploit that. I am of course referring to the really organised criminals (criminals with Filofaxes). That is the expected setting and on February 11th 2024 I wrote ‘Don’t take my word’ (at https://lawlordtobe.com/2024/02/11/dont-take-my-word/) I was considering the danger that a place like Funnel was presenting itself to be. And the presented advertising (a lot of it on LinkedIn)

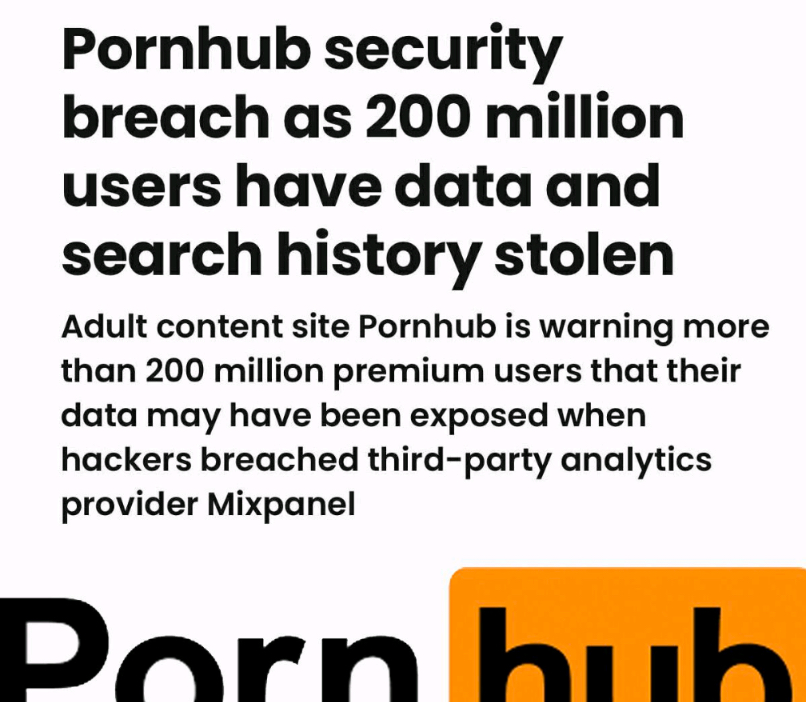
showed a setting that I feared and guess what? I was partially right. I was right because that side was exploited and I was wrong as it was not Funnel who gave the setting. It was a place called Mixpanel where we see “more than 200 million premium users that their data may have been exposed when hackers breached third-party analytics provider Mixpanel” and last month we were given ‘Data breach at OpenAI through analytics provider Mixpanel platform’, which was seen (at https://securitybrief.com.au/story/data-breach-at-openai-through-analytics-provider-mixpanel-platform) you can wallow as much as you like that I was wrong, but that another platform provider is the first to fall, does not mean that I was wrong. The setting of ‘ease’ safety which they called “Hey marketer, tired of wasting time downloading and cleaning data from all your advertising platforms? It’s time to meet

Funnel. Save time, improve performance, get better insights with Funnel.” As I personally see it ‘tired of downloading’ should be seen as ‘safety towards your data’ and “cleaning data” often implies “validating and verifying the data you are using”, so if there are people that are thinking I am a proverbial shit bucket, consider the image below.

Where we see that in the proverbial instant. That resulted in the loss of some “200 million users have data and search history stolen” and yes, the 200 million records could see the setting that these 200,000,000 million users will get phased and the companies they optionally worked for too. That is the larger setting of being lazy, or being contemplated towards the security they never really had. Why did they not have that security? Because certain settings negate safeties that are and as I see it, Mixpanel who by the opinion of some is seen as “a product analytics platform that helps businesses track user interactions on their websites and apps to understand behavior, improve products, and drive growth” and as I see it, it is driving growth for the really organised criminals and now as we see (at https://securitybrief.com.au/story/data-breach-at-openai-through-analytics-provider-mixpanel-platform) we are given “The incident was related to unauthorised access to a dataset within Mixpanel’s systems. OpenAI reported that an attacker exported data containing certain identifiable information of API account users. Details potentially exposed included names provided on API accounts, email addresses, approximate location information, operating system and browser details, referring websites, and the organisation or user IDs linked to the API accounts. OpenAI emphasised that no chat logs, API requests, passwords, keys, payment details or sensitive identification documents were accessed. The data breach affected only information collected for analytics purposes through Mixpanel.” I get that this is the OpenAi answer, but it seems shallow, short, and perhaps that is all it is, but there is a second setting. Either the ‘provider’ who sounds like Promohub is giving us a larger pool of users, or some clever person might be insightful enough to combine the data of two pools of data and see what could be linked, because any person whose ‘shortcomings’ are exposed will seek other ways to hide the ‘shortfall’ and that is exactly what criminals are banking on. OK, this is speculation but if I had these two pools of data, I the first thing I would do is to seek a common ground (like an email address) and see what else I can find. This is how I found the weakness towards the Pentagon using the HOP+1 solution (which is wrongly analyzed by what some call AI) it was the first thing I did last month. And now again I am right. To be clear, the article on Funnel was about Funnel and as far as I know it was never transgressed upon. It was merely a fear I held and the fear was shown correctly at Mixpanel, not Funnel.

So whilst OpenAI correctly gives us “Information potentially accessed through Mixpanel may expose users to an increased risk of phishing or social engineering attempts.

Names, email addresses, and user identifiers were among the details exposed. OpenAI has advised all customers and users to remain vigilant for any suspicious or unsolicited communications that could be related to this incident. The company reiterated that it does not request sensitive information such as passwords, API keys, or verification codes via email, text, or chat. Users have also been encouraged to enable multi-factor authentication as an additional protective measure for their accounts.”

And why am I now up in arms? Because I got the word through another source relating to another vendor and that implies that there are at least three data sources exposed and those with connected data will be at risk. As such there is little risk for OpenAI and its users if it is used correctly, but when is that the case and it falls back on the users, not on OpenAI. There is an old premise that I usually phrase. If 5 vendors have a 10% loss, the customer is at risk of losing 50% and that is what the danger is here. And when this is applied to 200,000,000 users, the losses could be close to astronomical. 

Now we can argue that there is no such risk, but that answer is coming mostly from people claiming to have no P#Hub account. Do they? I cannot tell, but they know if they have or not. And to also be clear, there is absolutely nothing wrong with having multi-factor authentication on any account you have. Those people are as I personally see it the least in danger.  But that is the setting that we are avoiding to look at. As I have said (way too often) that nonrepudiation is the way to go is showing to be the correct setting yet again. 

Have a great day all, only 11 hours until Friday, or in Hobbit terms Frododay, the day you have two breakfasts and three lunches until the beer o clock chimes.

Leave a comment

Filed under IT, Media, Science