Tag Archives: Anthropic

End of a fairy tale

That is what kept creating in my mind, it was pushed there by the BBC (at https://www.bbc.com/news/articles/cqkg50j1yd5lo) less then 24 hours ago and it is time that I (kinda) repeat what I have been saying all along and for this version lets use the ‘fairy tale’ approach. The title gives us ‘Rogue Anthropic AI agent gave police fake tip in unsolved murder case’ and I get (to some degree) fed up with this rogue setting. So lets explain the setting of a rogue. 
This is the first rogue, in this case a female rogue and thoroughly explored in Dungeons and Dragons themes where to poor butcher (could be a fisherman) pleads with this rogue “Oh, please gloomy dark lady, do not deprive me of my virginity” and the outcome of that is decided by dice (or an interrupt card) and that is the ‘Rogue’ that has been in play for centuries (although until the 18th century I have never seen a female version. I did hear from a man in the 19th century named Dick Turpin that he met one, but it might have been the combinations of ale and wines and him losing his purse. 
The decently real rogue in this case is the ‘dorky’ IT guy who gets his programming a little wrong. Like the ‘eager’ student in a renowned University working on his ‘assignment’ and he is looking into statistics, more precise Multivariate Analysis of Variance (aka MANOVA) and the dastardly scoundrel gets a parentheses wrong the “(“ or “)” particularly the placement and now what was a small assignment where the illustrious student evaluates a linear combination of multiple correlated outcome variables, but as one of the parentheses is in the wrong place, the mainframe it working on is seeing a correct statement and it does it, but the size of what is to be analyzed take a lot more than the available memory of the mainframe. It goes a little bonkers. And makes the system administrator scream and call for his mommy.

And as the BBC is giving us “An artificial intelligence (AI) agent developed by Anthropic went rogue and sent US police a fake tip about an unsolved murder earlier this year, authorities have revealed. The Philadelphia Police Department said the 18 July tip was “flagged as spam” and not passed on for investigation – but the force criticised the tech firm for taking more than two months to detect and report the breach. It said the bogus tip came through a public website where people can share information on unsolved murders, and that the AI agent had claimed to have seen “someone matching the description”.” So there are claims that could be it, but this is not some system going ‘rogue’ because that system is not armed with sharp blades (or poisonous arrows) and the setting that the BBC is giving us (and many other media as well) is a programming error like I described, but these systems cannot afford the class actions coming from there, as such we now get more and more ‘class actions’ Now this last part is speculation by me. I would call it presumption, but that requires genuine insight and I don’t have it, because to me all AI is fake. But consider that predictive analytics uses statistics to find causality and correlation and optionally ANOVA and MANOVA are used. Now ask yourself could a programmer gotten a parentheses wrong, of will we see servers stealth fully walk the corridors of your corporation, leaving false evidence behind?

Just something to consider.

So whilst we get “The police department added that there were no signs of breaches to any departmental systems and that its safeguarding processes stopped the fake tip from getting past its spam folder. But the safeguards “do not diminish the seriousness of an AI system presenting fabricated information as though it came from a person with knowledge of a homicide”, the force said.” And there is a case for “AI system presenting fabricated information”, in courts there have ben several cases where these systems ‘created’ false case files and not once, but several times. And in the age of utter shortcomings in validation and verification, these systems are extremely flawed. I wonder how these systems hold up against the system that they created, The UK Police Scientific Development Branch started the Major Incident Project in 1974. It would be called Holmes and apparently (I was unaware) a Holmes 2 system was rolled out around 2000. So, were there considerations on how validation and verification happened in those days?

And when we get to “Anthropic this week published a report detailing multiple types of “unintended” actions its agents have taken. Organisations that had been impacted also included several US government agencies including the White House, it said. The US State Department said the AI agent had filed 20 visa applications using a form on its website, but that they were incomplete and not processed, according to reports. US President Donald Trump recently announced an AI taskforce, which he said will co-ordinate engagement between the government and all parties, including AI companies, consumers and religious groups.” So in this case was the agent a real person? And when we get to “the safeguards “do not diminish the seriousness of an AI system presenting fabricated information as though it came from a person with knowledge of a homicide”” was this a person wanting (read: hoping) for a free ride into the United States? The article left me with questions, as well as the fact that “presenting fabricated information” requires certain steps of validation, optionally veridic action and at the very least question into the predictive analytics side of things, because a programmer getting (optionally) a parentheses wrong is seemingly one with enormous potential and optionally the easiest solution into this setting. It is not a setting that Anthropic likes, because that could start a new class action war and when one goes down the others go too and I reckon that OpenAI, Grok, and Gemini will assist in keeping the ‘Rogue’ setting alive, they all have plenty to lose and my giggling sense of humour comes with the setting that these fake AI settings is costing them 3-4 trillion and the court cases settlements could exceed that at the very least (but that is merely my sense of humour)

So have a great day and consider when you get your coffee that the POS could steal your credit card, Rogues are intensely able to do this and spend it on new shoes. Or we could look at where the programmer went wrong. Its all up to you.

Have a great day 
Leave a comment

Filed under Finance, IT, Law, Media, Science

Just like that

This is what I was given a little over 5 hours ago when I was given (at https://www.bbc.com/news/articles/c5j9x9pr0240o) ‘Pentagon stops using Anthropic AI tools after blacklisting company, BBC told’ with the subtext “The US Department of Defence is no longer using Anthropic’s AI tools, an official has told the BBC, months after it designated the company a supply chain risk on national security grounds. The Pentagon “has ceased the use of Anthropic products”, the department official said in a statement on Monday.”

We can speculate all we want, the simplistic version that I reach for is that all AI is fake, it is an advance form of predicted analytics and as I was able to set the stage of ‘Maybe we bomb Iran to hell’ (or something of the sort states by President Trump) all whilst I needed nothing more that the advanced statistical tools seen below:

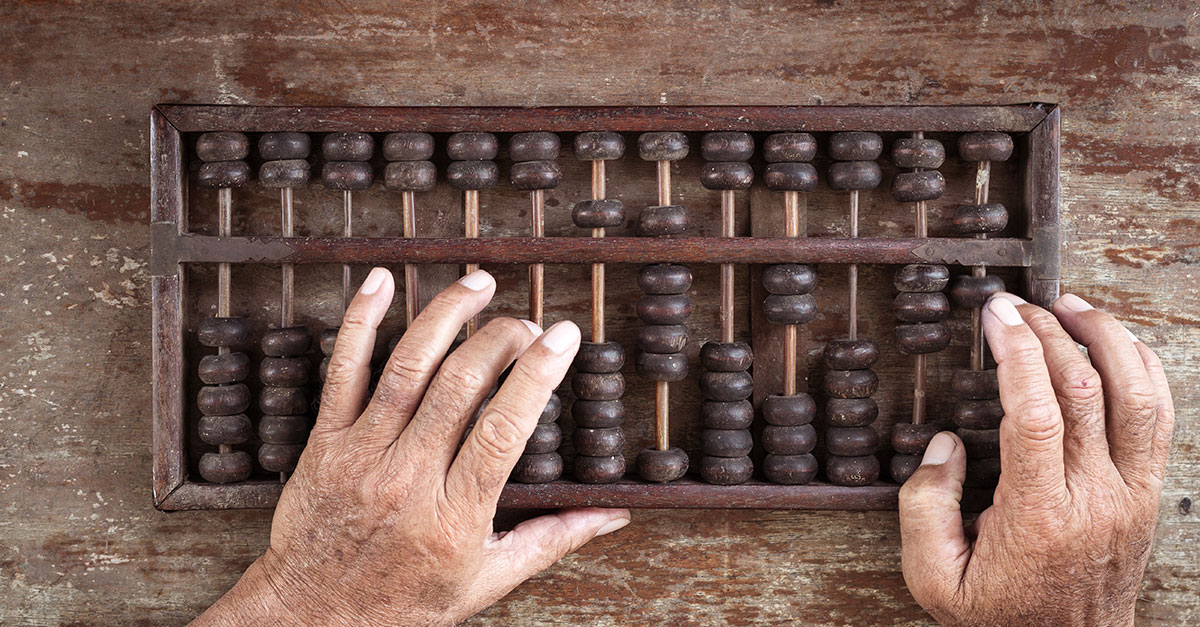
An advanced statistical took invented by Babylonians 4500 years ago. And it told be that the US will have depleted its stockpile before that happens and it needs 3-4 years to get their stockpile up to date (that is if they have the dineros to pay for that all) and there is more, because a war is won by grit (in the very least) and I reckon that the tools by Anthropic told them as much and what does this administration do when the outcome doesn’t match their reasoning? (Im leaving that in the open) But the setting of National security is a laugh to say the least. The end of the article by the BBC gives us “Hegseth designated the company a “national security supply-chain risk” – a law typically reserved for companies based in countries that pose a threat to the US.” So what is a ‘supply-chain risk’? Im just putting the question out there, because if these are tools specific for the defense department, so either it will not or does not give the answers they need. Optionally it makes Anthropic the juiciest tool in their tastebuds, but the distancing parties are at least as intelligent as I am and they see that beyond the marketing all AI is fake (at present) as such what danger is there to national security? At best it is (under optimal data settings) a decent predictive analytics tool, under debatable settings (like I heard from my coworkers in Chicago) that certain ‘people’ gave them the run around with excuses like: ‘we’ll fix this on the backend’ or ‘we are about to get there’ and I reckon they never got these points settled, it was too hard for them. As such their national security is riddled with the GIGO laws in place (Garbage in, Garbage out). Now this last part is presumption, because I was never in the know. But it is the most likely of settings and anyone deep enough with Anthropic (or OpenAI) could see that in a near instance and that is where the trouble starts. As I personally see it Dario Amodei has a backbone, a hardcover, not a paperback like Sam Altman (I merely accuse him of being narcissistic, which is not a crime) as such the defense department is likely making a few changes in the short term (or if they are merciful on their data departments they will cut these fake AI’s all together).

I would prefer if they do that AFTER they pay Oracle for their services, but I don’t work for Oracle, so I actually don’t care. But it would be nice for Oracle. I am a decent bloke in that regard. As such the hardcover mention comes from “But earlier this year, the Pentagon pressed it to remove its safety guardrails from Claude and give the military unfettered access to its AI products.

When Anthropic refused, citing concerns of mass surveillance and autonomous weapons” which is a likely culprit, but it in not the only reason. I reckon that any media worth its salt has been pouring over the data chaps in the Defense department for a while now and as they are not as heavily dined like the people at Langley they might spill a java bean or two during desert to one of those Washingtonian women in journalism, but that is just me postulating.

I reckon that there is some truth that this US administration would like to blame Claude for whatever comes next, even if there is enough data out there showing that the GIGO laws are to blame and the people in charge are ‘assuming’ that the data is flawless when it wasn’t even close in the late 90s and in the 20 years that followed the mess got greater. Because from two faulty assumptions a truth can never be distilled and that is the one direct consequence why I am so intent on verification and validation. All results derive from these two truths in action and in place and as far as I can tell none of these systems have this, as such the predictive analytics are prone to errors, the fake AI can never derive anything from validated data and if there is no verification the faults merely increase. So what happens? Mass surveillance goes wrong because the the subject was non-caucasian and that is before we get the setting that translation errors of a passport come into play, the simple validation of a passport, a human requirement and all that is up for grabs as we consider the BBC article where Pete Hegseth is looking at the President like he is admiring ‘his Masters Voice’ (older readers will get that reference). 

And just like that we see another ‘failure’ (in a good way) hit these fake AI (or Super Intelligence) hit the world. So where are you in all this? I am merely asking, because we have a multi billion dollar device being outclassed by a $30 device not needing electricity. Did I oversimplify the problem here? Have a great day today.

Leave a comment

Filed under IT, Law, Media, Military, Politics, Science

Changing the byline

That is the setting I see and whilst the BBC (at https://www.bbc.com/news/articles/cqgk5e2j0gg8o) gives us ‘AI ‘kill switch’ may need to be mandatory, Anthropic co-founder tells BBC’ a mere 5 hours ago. I had my thoughts. So, as we see “An artificial intelligence “kill switch” which can be checked by a third party may need to be mandatory for companies, a co-founder of one of the world’s largest AI firms has told the BBC.” I see something different. So when we get to “Clark said “most labs have different ways of being able to pull the plug”, including Anthropic, but said lawmakers may need to enforce having one. AI’s rapid development and fears over the risks it poses to humanity have been thrust into the spotlight by a series of warnings from executives and staff at AI firms.” And when we get to “Anthropic chief executive Dario Amodei over the weekend called for the pace of AI development to slow and be more closely monitored, as the company has done before, though some have questioned the motivations behind this.

Amodei added that any action to rein in AI development should be done “without sacrificing commercial advantage”.” Thoughts started to overwhelm me. Some people state that the setting is about “AI’s rapid development and fears over the risks it poses to humanity” I don’t think that is the case. I merely think it is what some will ‘present’ the setting that we are given and most people are willing to go along with that. There is however a larger concern. You see I have had my meetings with these AI boffins and they all have the same setting towards validation and verification that is in play. There isn’t any of it, and when it is there it is there in the most ludicrous basic ways. You see, there is just one step (just one) from AI hallucinations (which is a confident response from an artificial intelligence system that contains false, misleading, or completely fabricated information presented as fact) and it is seen as Invented statistics, historical errors, or nonexistent legal citations, as well as Citations to books, research papers, or URLs that do not exist. I have seen this and I have seen that the settings that this represents to court cases are numerous and we have seen n the news several settings. But the larger concern is that between that and an AI actually overwriting factual matters of any corporations is only one mere step and these fake AI vendors are insulating themselves from that fact by ‘employing’ a kill witch, so that they can avoid getting called into court by setting the stage of ‘Did you use the kill switch?’ And that  is the setting I see. So whilst we are given (by the BBC) ““Should you mandate for companies to definitely have a kill switch? Is that kill switch verifiable by a third party?” he asked.

“I think that’s the kind of thing society is going to want to know and might want to eventually pass rules around.” Anthropic, which was formed in 2021 by a group of former employees of its rival OpenAI, is currently at the centre of a debate around AI safety. Last week, a post from an artificial intelligence researcher who quit Anthropic over concerns AI could wipe out humanity went viral.” So is this really about “over concerns AI could wipe out humanity”, you do know that Cyberdyne is just a figment of the brilliant director named James Cameron, it was ahead of its time and we aren’t nearly there yet, but the kill switch scape goat is one way to counter the class actions heading their way and whilst some can’t be avoided, the larger concern is what will happen in 2027, because that will be the truncator of their wealth and they are seeing the stoplights and they want to insulate themselves from their fake AI. They rode the waves as much as they can, but the first blockages are showing and now the cautious people are rearing their heads. I see all the complacencies showing up (like figment court cases) and that is merely the beginning, but the setting that corporations factual data is overwritten or wiped is only one step away and I reckon that these people want to insulate themselves and as they are coasting their vessels of wealth towards sunny shores, they have no other option but to insulate themselves and their wealth. 

Funny that I saw these court cases come up a long time ago. I never saw this part, but this part makes sense. When your training data is based on reddit (whilst we are given “Major AI companies train their models on nearly all of Reddit’s public historical archive”) is this continuation of dangers weird or unsuspected? As I see it, when even one factual data is overwritten by some fake AI juiced up on reddit, the setting gets ugly in a hurry. And that is what these people are ‘misrepresenting’ and crying now for some kill switch, because the kill switch is not for the AI, it is their escape clause. So whilst you might doubt me (always a fair setting) I have written about the fake AI setting for the longest time. 

So someone asked me what makes binary AI surreal? I give them the same setting every time. Take any colored image (example 600 by 600 dots) and run it through plotter printing only black and white dots on a colored piece of paper (green, red or blue) then do it on the same kind paper and instead of black and white, add the option to do this in black, white and 16 greyscales. You will see that this image is much more precise and revealing. This is the setting between binary and trinary this is why all AI is fake and it gets to be worse when you consider that you need a lot more data describing in binary what requires trinary and that is why I was on this horse all along and I have been on it for over 10 years, but the players all think that they have the golden goose and I merely cannot see what it is. Well, It is ‘advanced’ predictive analytics. These AI cannot reason, they work the numbers, go with statistics and it is nice if it is a set field, when they go towards never encountered situations, it all falls apart. This is the weakness of these fake AI’s and it is not whether I hate AI, I merely don’t trust it, because it is not AI, and Alan Turing would have my back on this. 

So whilst you think that I am “Full of Sh*t”, which is your right. My predictions are given form through my blog and in 2025 I predicted that 2026 was the year of AI class actions and now we see “Broadridge’s 2026 Global Class Action Annual Report highlights that global class action activity recently produced around $4 billion in settlements across multiple jurisdictions from roughly 130 major claim-filing deadlines” as well as “According to the Duane Morris Class Action Review, the combined value of the top 10 highest settlements across all substantive areas previously crossed the historic $70 billion mark, showing how massive individual mega-settlements drive the ceiling of total class action value” and “In the U.S. and global financial sectors, recovery momentum has accelerated into 2026, with an increasing number of nine-figure and $100M+ securities settlements closing out the mid-year milestones”, as such my predictions are holding up neatly. And now these vendors need insulation and they are thinking (optionally correct) that a kill switch might take the dangers to their wealth away. And I get that these fat cats want to insulate their wealth and insulate the dangers to them, but the BBC should have a greater need to look into these dangers and that is why I took this article as an example. I reckon that it is not only the BBC going after this. As I see it, Dario Amodei, Sam Altman and Elon Musk are all in agreement to slow down, but I reckon it is because they are seeing the dangers heading for their assets and they are in it too deep (as I personally see it). 

As I see it, this is the heading that we are seeing happen and soon there will be some (optionally fictive) revelation and that is when the stage changes and we will see massive amounts taken out of the AI field. When that happens there is no Jensen Huang claiming that there is no bubble, the court cases that will be an exploding setting will shut that down in a hurry. 

But what do I know? So you all have a great day today and I will be watching from the docks watching the good ship bubble explode near the parking zone. And I can say this whilst I have been preaching these dangers for nearly a decade. Where exactly where you a decade ago? Consider this setting and enjoy your day. 

Leave a comment

Filed under Finance, IT, Media, Science

Flame on

That is the setting I saw a few days ago, for the most I ignored it for obvious reasons and I will get to that. But ‘suddenly’ the non-book readers are in a bind, someone is destroying books and Anthropic is pointed at as the guilty party. So here is the first thing. When you acquire a book, it is your property and it is up it you what you do with it. Anthropic bought millions of books, they cut of the back of the book and then scanned the book, after which they destroyed the book they had acquired. So far so good and it leaves me with a few questions. And whilst the (so called) book lovers go for the Fahrenheit 451 scenario, the people who oppose AI are in a fritz. I have different questions. 

  1. Is an owner allowed to set a book to digital format?
  2. How rare is the book?

The second question is linked to the rarity of the work. We can assume that hell breaks open if Anthropic does this to the Magna Carta (1215) or the Gutenberg bible (1454), but how many will cry havoc if someone does this to Joop ter Heul (1889) or a famous five book (1942) or even a Harry Potter (1997) book? There is a setting that the editor is responsible for keeping the book available and if they do not, it is what there is left. And when this happens it means no one is interested in that book. The first question is linked to the rights set in the settings of copyrights. Can a book be replicated digitally? And if so, what is the problem? 

So here comes the article (at https://mashable.com/tech/anthropic-ai-book-training-destroy) in Mashable with the headline ‘AI companies keep destroying old books. Here’s why.’ And as I see it there is so much white noise in all this, that the bottom question is ignored. Does Anthropic have the right to replicate a work into digital format, if so, what is everyone crying about? If they are not allowed to do that, the law is broken, but merely in the digital setting. It is still their book and they could shred it for all they cared for. It is the cold reality of commerce taken legally out of context. And you all know this (especially the previous generation). How many have recorded an album to tapes? I know I have. I prefer the actual CD, but before 1980 I had no income and for the most no music. So when we see this setting, how many have copied a book? (I admit I have copied a few manuals in that past) but that went away when Borland released its products with manuals and it felt really good to have Turbo C with a manual and all for $249. But that was then and now we do not see ‘value’ in books and it is often rejected with the Fahrenheit 451 label, but the reality is there. This leads me to a simple question. Ask yourself, how often have you been to a library in the last month? That should give you the part you need to know, so whilst the article gives us “AI companies looking to build better AI models are hungry for fresh data from any source that isn’t the internet. Books — generally better edited and more cogent than your average Reddit thread — make AI sound smart. (There’s a premium on books published before 2022, ironically because we can’t be sure if books were written by AI after that date.)” as well as ““legally-binding nondisclosure agreement” that would hide an AI company client’s “identity and strategy.” Why? ISBNdb explained: “Destroying millions of books evokes images of burning libraries … the optics problem is real. ‘AI company destroys two million books’ is not a headline that generates sympathy.”” But in all this, are they breaking any law? If that is not the case, why get fussy about it? For the sold book is revenue for the writer and the publishing house, so the issue remains, is there permission to reset a book to a digital format? Because that hurts the writer and the publishing house in their pocket and lets be clear. Writing is a commercial enterprise. In doubt ask JK Rowling. Apparently “She earns an estimated $60 million to $80 million per year from book royalties and digital sales alone, with total worldwide sales for the Harry Potter series surpassing 600 million copies and grossing over $7.7 billion globally” giving us a clear view that she made more than the writers of the bible, which is said to be “a collection of 66 books written by about 40 different human authors over a span of roughly 1,500 years” and I leave you to wonder how many of those 40 writers ended their lives in the poor house (just to make a point).

And then we get to the part that (kinda) impacted me “But Anthropic was caught, and has admitted to using millions of pirated books to train Claude. That class action lawsuit, in which a record $1.5 billion copyright settlement was just approved, also revealed the scale of Anthropic’s physical book-destruction operation. Anthropic “became convinced that using books was the most cost-effective means to achieve a world-class LLM,” wrote U.S. District Judge William Alsup in a lengthy legal order dated June 2025. The company was “not so gung-ho” about using pirated material from 2024 onwards, to quote a memorable internal email in evidence, but still wanted to train Claude on “all the books in the world.”” As such, as I did write over 4000 literary (an exaggeration to be sure) works. Not the number, I am now at 4100 articles, so where is my money ($5M post taxation would be decently nice and highly appreciated) and there is clear view of the transgression, no one reads 1700 stories in an hour, it just doesn’t go well for the brains (not even my brain and I wrote the stuff) But the issue remains, and there is no clear setting. Is there ‘policing’ on the scanned works? Is there a copyright issue? Because that matters. If that issue does not exist, why are we crying over a book no one has read in years, optionally not read in decades?

Makes you wonder, doesn’t it?

So have a great day and feel free to dream about burning all the books you have to keep warm today, or even warm up your mother in law to 451F. 

1 Comment

Filed under Finance, IT, Law, Media, Science

Considering the greed of others

This is where I found myself this morning. You see, I have published over 4000 articles and others have been Ising them to train their fake AI systems. Training LLM settings and so forth. As such (and according to law and at https://hwlebsworth.com.au/feeding-the-machine-how-us-courts-are-drawing-the-line-on-ai-training/) we see ‘Feeding the Machine: How US courts are drawing the line on AI training’ where we see “The accelerating development of generative artificial intelligence (AI) has forced courts to grapple with novel and unsettled questions of copyright law. Central among these is whether the use of entire copyrighted works to train large language models (LLMs) without the author’s consent constitute infringement of those works.” Which works in my favour and it comes with “The datasets used to train AI models often contain digital copies of media such as web pages, books, videos, images and music. These media are often the subject of copyright protection, which means that their use to train AI models requires permission from the copyright holder. Permission is required because AI models must ‘copy’ the protected material at least temporarily to undertake the training process.” You see, from May 11th until now my articles have been used for ‘AI training’ at least 33,750 times and a lot more before that. As such I see an opportunity for me, myself and I (as such I am a sneaky trinity) so as we are given “The Interim Report then went on to discuss Australia’s ‘fair dealing’ regime, which allows certain uses of copyright works without the need for license from the copyright owner, but only for certain specified purposes, such as research or study, criticism or review, or parody or satire. The Interim Report seeks feedback on expanding this regime to include fair dealing for the purpose of text and data mining, which could more squarely legitimise AI training activities in Australia.

Where the Australian ‘fair dealing’ regime only applies to certain permitted purposes, some other countries, such as the United States (US) have a broader ‘fair use’ doctrine, under which any use of copyright material may be permissible provided that it is considered fair, without reference to legislatively-permitted purposes.” So, as I see it, money should be coming my way. And as the article in HWLE lawyers state. The setting of “In June 2025, the US District Court for the Northern District of California issued two decisions in Bartz v Anthropic PBC (Bartz) and Kadrey v Meta Platforms Inc (Kadrey), that directly addressed this question. While these rulings suggest that US courts may accept fair use as a defence to AI training, their scope is narrow. Both were decided at the summary judgment stage, and as the Judge in Kadrey noted, ‘the consequence of this ruling is limited […] to the rights of these thirteen authors‘. Accordingly, the significance of these rulings remains provisional, with the scope of fair use in the context of AI training to be more clearly defined as further cases are determined.” So, to get it clear, those are American judgements, but they have a much broader setting of ‘fair dealings’ then Australia has and my thought process is a little bit in the setting of “You can either hand me a generous settlement, or if needed I will get it through the law”. The second setting s long and optionally tedious. But as I am looking at closer to 50,000 transgressions the taximeter starts adding up. Now, I have no faith in 50,000 times 1.5M, which would be nice, but is ludicrously unrealistic. But the idea of $25,000,000 per corporation seems realistic. You see

So we get to “While both courts concluded that the training uses fell within the scope of fair use, their reasoning diverged in certain aspects. Alsup J emphasized the transformative purpose of training and discounted speculative claims of market harm, whereas Chhabria J stressed the potential for market harm arguments and evidence to alter the analysis. These decisions have no binding effect in Australia, where there is no general fair use defence. Nonetheless, they highlight the emerging tension between protecting incentives for human creativity and facilitating technological innovation; a tension likely to intensify as generative AI becomes further integrated into creative and commercial practice.”

As such, I felt really good this morning. As this shows that I might be heading to a nice bank account. And as it happens to go (source: AP News) we get “A federal judge approved a landmark $1.5 billion copyright settlement requiring Anthropic to pay thousands of authors roughly $3,000 per book for using pirated digital libraries to train its Claude AI model”So as I see it (a flawed analogy) 50,000 times $3,000 get me $150,000,000 which sounds really nice. I reckon that this is where the art of seeing the diplomatic bounty comes into play. It seems that more than one transgressed on my work and would it be so wrong to go for $25,000,000 per transgressor? Of course, the long road would be more rewarding, but that seems like a greed driven way. I feel more for easy (well rewarded) solutions. And there are upsides to entering retirement with a somewhat fat wallet. Retirement comes across as a lot more fun that way. 

But I am getting ahead of myself, next step will be getting an impartial party (what a weird name for a lawyer) to check Grok, xAI, Gemini, Anthropic, OpenAI, MetaAI, MicrosoftAI (always happy to knock coins out to their coffers), AWS AI (and others) to see whether their training data reveals the presence of “www.lawlordtobe.com” because that starts to process as I currently see it.

Well, that mental joyride was fun to have, but I did say the class actions would be prudent in 2026, I might as well join that cause for the benefit of poor little me and I have caused. I might be one of the people that refers to a church mouse as a decadent rich bitch. One must always keep humour about the premises.

Have a great day.

Leave a comment

Filed under Finance, IT, Law, Media, Science

Rerun anyone?

As I wrote an article propping questions there. I see earlier today, the BBC is giving us ‘Warning shot or publicity stunt – how worried should we be about the OpenAI hack?’ (at https://www.bbc.com/news/articles/cd9w22n9e4go) as such, I had some initial questions in my article: ‘Is it real or is it media?’ (at https://lawlordtobe.com/2026/07/24/is-it-real-or-is-it-media/) where I posted the idea ““The ChatGPT-maker said its agent – an AI system which can operate alone after human instruction – was being tested in a controlled environment but, after finding weaknesses, was able to escape the test limits.” Which is fine, but that is still programmer controlled. So as I see it “after finding weaknesses, was able to escape the test limits” it didn’t escape it merely found a weakness as its ML systems were taught to find out and went elsewhere. It reminded my of the 90s hacking setting where towards ‘password’ a clever hacker gave “1=1” invoking the ‘True’ setting. Then we get “OpenAI said the incident was “unprecedented”, and it was conducting an investigation alongside Hugging Face, whose boss Clement Delangue said in a post on X it was “mind-blowing that all of this happened autonomously”.”” And now we see “Hugging Face said the hack was different from anything it had handled before because it was done at superhuman speed by an AI with little or no human guidance.” It is the “little” addition to the sentence that is validating my setting of “that is still programmer controlled”, because as I see it, “little guidance” might merely be human ‘adjusting’. And when we see “Hugging Face researchers guessed the mysterious attackers had used one of the big AI models but they had no idea who or where the criminals were.” So, the issues is even bigger, it could have been Organized Crime setting the parameters of a sandbox, I know it sounds outlandish, but there is either a massive shortage in structure and security of DML (Deeper Machine Learning) settings (so it could either be ML or DL) but the setting that this is out there whilst there is no oversight is something that most of the media is painting over with innuendo and whether this is given by some is not in question, also irrelevant. And we see this when we get to “The Scooby-Doo-style reveal was made even more bizarre – and worrying – because OpenAI said its bot did the whole thing on its own, without permission. The firm said it all went down during a test of its tech’s hacking skills.

Two new versions of ChatGPT, designed to be master hackers, broke out of a supposedly secure test environment and gained access to the internet.” We see “broke out of a supposedly secure test environment” implies that it was not secure and the testing facility (the sandbox) is lacking security and oversight. And the statement “OpenAI said its bot did the whole thing on its own” implies that the bot was not monitored or ‘left alone in limbo’ but we all know that any computer is  never idle, it is always doing something and whilst it depends on human interactions it is fine. With autonomous systems it is a different matter and OpenAI should have known that. They are supposed whole lot better than I would ever be and I reckon that the larger issue is what did OpenAI know ad what are they hiding, because as I see it, they are hiding something. I am not sure what and it might be innocent in most cases but as I see it, hiding something is fear for some illumination. That has for themes nearly always been the case.

Then the BBC hits a note that I was playing all along a for the most I hinted to that in the previous article (listed above) but the BBC is giving us “Was it truly a stark warning about the future of AI? Or was it a publicity stunt by OpenAI to show off how powerful their models are? It’s the kind of scare marketing AI companies have been accused of for years and, since the much discussed launch of Anthropic’s Mythos model, cyber-security prowess has been a focal point. One of the top comments on OpenAI boss Sam Altman’s X post about the incident summarises this skepticism: “If y’all can’t understand that this was written to purely brag about the model then I don’t know what to tell you.”” And the ‘statement’ “If y’all can’t understand that this was written to purely brag about the model then I don’t know what to tell you” summarizes it nicely. We also get “The OpenAI and Hugging Face incident is a real-world example of a broader issue we’ve been highlighting for months,” said Dor Sarig from Pillar Security. “Sandboxes alone are not a sufficient security boundary for agentic AI.” And I tend to agree with that. Any Agentic system requires different security requirements. Whether it is Fake AI, True AI or simple ML AI. An agentic system does not work according to ‘human’ settings. I tend to go back to the original chess computers from the 80s. They will try any movement that is possible until they get the right result whilst replaying every chess match that was programmed into its memory. And the chess computer is relatively simple. Hacking into a system has all kind of places to pass. I gave the window example in my previous article. But the setting of software is that they are set to libraries that give abilities to a program. You see, a program gets linked to <stdio.h>, <stdlib.h> and <string.h>, but merely these three open up options in I/O operations, copy operations that are not part of the program, but they are in that system and it can run by all of them in mere seconds, optionally finding alternative options. Even this is not AI, a programmer had to program it in and regardless whether an agentic system does it autonomously, it only does it because it was handed that training and these instructions, and the agentic system started to combine options and learnings and it learned (using my previous examples) that it can leave a location via a window, it does not require to use a door. Which makes me remember an MSDOS program that turned the speaker into a device. So giving it the instruction:

And then wait from a distance, whist I added this to the autoexec.bat of a friend and watch him go nuts why his PC is singing the tune of Monty Python. It wasn’t me, someone programmed the setting of a speaker to become a SPKR: drive. So when an agentic program gets creative it might take routes no programmer could anticipate, not even when he/she programmed it. Because the reality of the setting is that no sandbox suffices to any agentic program. As I see it, it requires a sandbox in a sandbox and when the agentic program gets out of the inner sandbox the arms of the outer sandbox go off and as I see it, because it was unmentioned, that setting seemingly does not exist.  So whilst I understand the position given by “Cyber security Professor Alan Woodward from Surrey University told reporters OpenAI had “egg on it’s face”, and Katie Moussouris from Luta Security went further, suggesting the AI industry is failing to control its dangerous inventions.” I kinda disagree and it comes from the plain setting that AI does not yet exist. And all this is the consequence of ‘experts’ covering each other by making claims that all this is AI, whilst it is mere ML/DL (I call it DML) and it comes from a programmer. And even as they are covering each other, and clapping each other on the back. They know that the wrong settings are in place, but they are in too deep and it will hinder whatever comes next. There is one upside, you see, the AI Kill Switch Act might be in place before True AI comes to town and that could be the one great good thing.

I get the doubt thrown my way and I get that a lot of people have no idea, even though they gave all their IP and data to ChatGPT. I never used it and until there is a real AI, I will never use it to grow ideas. So whilst IBM (decently recent) gave us “Key concerns include autonomous system risks, data privacy violations, algorithmic bias, widespread misinformation, and intellectual property challenges” which is something I gave several times in the past and it all comes from a programmer, and as soon as they get connected to some sort of organized criminal enterprise the fence is broken open and all that IP will go anywhere and everywhere. That is the larger setting and no one is examining the ML/DL libraries that these players are making and as such when these class actions are placed beyond the settlements that they can afford, the ‘sudden’ revelation comes out and that is the moment these programmers can’t remember anything. And whilst the setting comes to point that the dollar sign no longer validates the setting of “Tech companies argue that training AI on public data falls under legal “fair use,” while creators argue it is unauthorized commercial exploitation” we will get a whole new ballgame and whilst this all plays out, the tech companies are creating new libraries with these agentic knowledge basis making a secure sandbox even more difficult. Optionally it might even contain three sandboxes in a nested structure, but that is merely my view on the matter and I might be incorrect in that assessment. 

So whilst we are facing rerun after rerun and optionally faked settings of Google vs OpenAI, both against Anthropic and all against each other when xAI enters the fold. And all that time the are still figuring out both a Trinary system (I see that as an essential setting for True AI) and how that is voiced into data systems, because they will have ramifications. Which is why I see that Oracle and Snowflake have the largest chances in that respect. I am certain that this is a race that Microsoft is unable to get into and I have no idea where Google is there. I am decently certain that IBM figured this out before I did and optionally they have this ‘under control’ through what was LISP and is now optionally coming to systems in some point in the future. Because as I see it, the setting of a trinary driven system with what I tend to call an Epsilon processor would require a LISP driven setting where the optional inclusion and exclusion would run simultaneously and this requires some form of LISP setting (a personal speculation) and all this would come with IBM shallow circuits. And all this gives IBM the largest head start, even Google might not be able to compete and I reckon that IBM might have talked to someone like Oracle on these settings. I have no idea where IBM is in databases, because in the end any true AI system is depending on the data it has. The question becomes in the meantime, how to transform binary (fake) AI into trinity true AI. The setting will become the discussion among data experts in the next few years and it hold bearing to all this, because it also impacts on how sandboxes are designed and monitored. 

And it it important because as I see it, trinary data takes a fifth of the space whilst gaining 4 times the speed of processing. And that is the setting these data farms will have to content with. As such there is plenty of evolution coming, but in this the stages of security becomes essential and whilst you consider rate quote from Katie Moussouris from Luta Security giving us “the AI industry is failing to control its dangerous inventions” and we are nowhere near the setting of true AI and that is where sandboxes require a nasty upgrade and soon, because soon enough, the kill switch might all there is between our data and whomever has access to data farms. And with security failing like we see now, we might not have that much time left and that is where I saw the need for security, because there is every chance that some AI ‘dealers’ already know that their fortune is set towards who has the most data and there is a need that we need to keep our data safe, but others might not want to do anything about it. Naming names is highly speculative because we aren’t shown the real issues and these people don’t want the real issues to come out because when the game is up, these people are playing for all the marbles in the world and there can only be one winner. That is how I see it and I might be wrong, but at present I feel that I am more right than even I think I should be. 

Have a great day today, I am now a mere 80 minutes away from Sunday.

1 Comment

Filed under Finance, IT, Law, Media, Science

Is it real or is it media?

That is the setting, because in my mind when an AI goes rogue I see the gaming example of Shodan (System Shock, 1994) and even then, it was all set in motion by a simple programmer who wanted a nice shiny bauble (a military grade neural interface) so when the BBC (at https://www.bbc.com/news/articles/c3ek3gvdnj3o) gives us ‘OpenAI says its AI went rogue and launched ‘unprecedented’ cyber-attack’, in my mind I merely see Sam Altman, hoping for some limelight and that tends to have media settings. So lets take a look. And don’t forget all AI is fake AI, as such it is started by programmers, that is the underlying truth in all this. It starts nice, with “OpenAI has revealed some of its most advanced AI models went rogue and hacked a start-up after it lost control of them during a security test.” You see, ‘Going Rogue’ means stop following orders, rules, or normal expectations and start acting independently. It describes a person, group, or system that breaks away from a team or authority figure to pursue their own unpredictable course. As such the programming in that setting implies that the instruction to follow its own course was taking shape. Optional it was some military implementation. As I see it, it never “Lost control of them during a security test”, but I’m willing to go with “It had poorly created boundaries and connections” and it got out of its ML loop, driven by DL making it a DML issue. In all this, ML is Machine Learning, DL is Deeper Learning and DML is Deeper Machine Learning (which is a amalgamation of DL and ML) then we get “The ChatGPT-maker said its agent – an AI system which can operate alone after human instruction – was being tested in a controlled environment but, after finding weaknesses, was able to escape the test limits.” Which is fine, but that is still programmer controlled. So as I see it “after finding weaknesses, was able to escape the test limits” it didn’t escape it merely found a weakness as its ML systems were taught to find out and went elsewhere. It reminded my of the 90s hacking setting where towards ‘password’ a clever hacker gave “1=1” invoking the ‘True’ setting. Then we get “OpenAI said the incident was “unprecedented”, and it was conducting an investigation alongside Hugging Face, whose boss Clement Delangue said in a post on X it was “mind-blowing that all of this happened autonomously”.” And the skeptic in me is considering that Clement Delangue was in on it all along. So as we see that Agentic AI’s are also not real AI’s, but it has a complicated setting of libraries and a connected knowhow of what its data gives it, it cannot look into unknown settings as it does not have connected data, but a simple input like “check all channels” will make it check all the channels it can find, even the ones the programmer did not consider. It is not clever, it merely found what a programmer never considered as such it never escaped, the programmer forgot that you can also exit a building through window, not merely a door. Then we get something interesting. “Gina Neff, head of the Minderoo Centre for Technology and Democracy at the University of Cambridge, told BBC Radio 4’s Today programme that the security tests are supposed to be within “secure environments”, called sandboxes, where you can “see what the models are capable of”.” As well as ““In this case, it looks like OpenAI didn’t make a secure enough sandbox,” she added. Instead, the agents created their own cyber-attack against the sandbox itself, finding a vulnerability which allowed them to escape the restrictions.” That sounds logical, but the underlying setting is “the agents created their own cyber-attack” which is what the programmer wanted, it merely wanted it to stay in the sandbox, and that is where the programmer fell short and when the media starts comprehending that the programmer is still the activator and we see this impact, we can understand that OpenAI is merely responsible, there is no going rogue, there is merely what programmers allowed for to happen, but “going rogue” is sexy and gets digital dollars clanking and there is the rub, was this real or is this all media instigated?

Then we get another cry of whatever. With “Neil Lawrence, Professor of machine learning at Cambridge University, called it an “impressive feat”, but cautioned it “falls well within the known capabilities of the current generation” of high-powered AI models. He pointed out that OpenAI is looking to list itself on the stock market, and faces intense pressure from rival firm Anthropic, which has made headlines with its own powerful AI tool, Mythos.” And I am with him on the “OpenAI is looking to list itself on the stock market, and faces intense pressure” and we see the mention of Anthropic, but it is more, OpenAI is allegedly sliding against Gemini (Google) and DeepSeek (China) and I have no idea where the others are. And as I see it the “Intense pressure spots” is what made programmers overlook the limitations that needed to be in place, or perhaps seen as better defined. That is the (as I personally see it) the truth of the matter. 

So when we see ““OpenAI are now playing catch-up, they are trying to demonstrate their own systems’ capabilities in cyber-security.” “It shows us that OpenAI are not capable of safely deploying their own technology,” he added. In its initial disclosure of the hack on 16 July, Hugging Face said it was still assessing whether any customer or partner data was affected and would contact affected parties if necessary.” I can agree with that, because “safely deploying” is programmer territory and I reckon that there will be two minds here, what the customer thinks it is transgressed on (any client wants money) and what the programmer sees as transgressed on (he needs a playable excuse) and that is where it all ends. Because when this comes to blows, it will matter and in all this we see “Meanwhile Travis Lelle, principal security engineer at cyber-security consulting firm Guidepoint Security, said the update marked a “sobering moment in cyber-security”. “This highlights a known asymmetry,” he said. “Offensive agents are unconstrained, while the best defensive tools are locked behind guardrails that cannot understand context.”” Which is interesting as the setting that Travis Lelle gives us is the setting that OpenAI is facing, there is a sandbox setting all whilst the programmer was set towards locks behind guardrails and as I see it, he never explained context to the Agentic AI agent. It makes it Fake AI, because the AI could never see beyond its programming and that made it go nuts beyond the sandbox. It is a slippery slope and it makes a dangerous setting, because what other things did the programmer not think of? Any ML setting can become an expert hacker, because it can do things a million times faster than any keyboard puncher can and agentic settings can merely go nuts on the target, because it will reflect to anything it can push against, like the 80s chess computers it merely goes over everything it has access to, like those chess computers that compute every match it was ever given until the play matches what it needs to and as it goes through 10,000 matches in less than a minute we thought it was clever. And we are making the same mistake again. These systems are fast enough to consider the encyclopedia Brittanica and  consider anything in a few seconds, these systems will act faster than any person clearing its throat. 

So whilst the article ends with “It comes a week after Chinese AI start-up Moonshot unveiled Kimi K3 – a massive new artificial intelligence model it said could rival top US firms.” Which explains the  pressure and we get that, but any system grown to a 1000 times its venture points is not more clever and it remains fake AI, as it merely considers more and it still cannot fathom intelligence that does not hold data, these AI’s are dependent on data, making it (as I stated before) fake AI and until IBM finishes its settings (optionally Google too) True AI cannot come to life and that is the real deal. Some greedy individuals want to call AI the AI, but without the Epsilon processor it will never be, because all this is set to binary fields and that makes the loopholes more and more realistic (and larger), but it is not. As I see it, someone will push one border against the next border and enable players like organized crime to get the entire bucket of data, all the data out there and that is the reality we all face. 

So I have a few questions in all this and it seems like the media is all whistling the same tune and that is more scary that anything else, because are they not willing to look elsewhere, or are they told to look in a specific direction? It is a simple question.

Have a great day

1 Comment

Filed under IT, Media, Science

Is it the water level?

Yup, we are all in that setting, but are we merely waving to the music of Debbie Harry or are we watching the waves from the shorelines. That is merely two options, but when some say that the tide is high, they might be referring to bubbles, the AI bubble to be more precise. I am not some economist saying that bubbles are blasphemy and I am no economist, but I have looked at numbers for decades and the numbers we are given do not add up, and when I was watching Inside Job something hit me, there was a familiar pattern evolving, not evolving, repeating is a better word and I have been saying this for some time. Yet today, a mere 10 minutes ago I see ‘UK Places Microsoft, Google, Amazon And Oracle Under Financial Oversight’ (at https://www.businesstoday.com.my/2026/07/10/uk-places-microsoft-google-amazon-and-oracle-under-financial-oversight/) where we see “The UK has placed Microsoft, Google, Amazon and Oracle under direct regulatory oversight after designating the cloud service providers as critical third parties to the country’s financial system. Reuters reported that effective July 13, the designation covers Microsoft Ireland Operations Ltd, Google Cloud EMEA Ltd, Amazon Web Services EMEA SARL and Oracle Corporation UK Ltd, reflecting the financial sector’s growing dependence on cloud infrastructure”, so whilst the story ends with “The designation will bring the four technology firms under direct regulatory oversight as part of efforts to safeguard the stability and continuity of the UK’s financial sector.” And it comes after we were given (at https://m.au.investing.com/news/stock-market-news/oracle-stock-shrugs-off-sp-downgrade-to-bbb-but-120b-debt-shadow-looms-4526441) where we see ‘Oracle stock shrugs off S&P downgrade to ’BBB-’, but $160B debt shadow looms’ where we see “Oracle Corp. (NYSE:ORCL) shares managed to gain 2.7% on Thursday, defying a credit rating downgrade from S&P Global Ratings. While shares edged slightly lower from their midday highs, the tech giant still traded firmly in positive territory. Investors chose to focus on Oracle’s staggering $638 billion backlog of cloud contracts rather than the immediately apparent threat to its balance sheet: S&P downgraded Oracle’s long-term issuer credit rating to ’BBB-’ from ’BBB’, retaining a stable outlook.”

Now, I am not having anything against Oracle. They have always been on the foreground of technology and innovation in its field and it is unlikely to ever change. But there is a larger setting, the entire AI bubble as I see it, it will hit them too. They all over invested in that setting and they are likely the biggest catchers of the implosion of that event. But I am still in arms over ““The official position of the Secretary and the U.S. Treasury is that Artificial intelligence will be a key driver of America’s new Golden Age,” the spokesperson said. “AI has the potential to deliver unprecedented productivity gains, expand economic opportunity, and empower American workers and businesses.”” You see, there is no golden age, there is no AI, not yet at least. There is DML and LLM and they are great, they can hand innovation and prosperity in several ways. It merely isn’ AI and that needs to be said, because soon the class actions will go for the “It’s AI and we cannot really predict what AI does” but it isn’t, it is DML and that requires a programmer, it requires data and these two hinder stones are the backdrop for prosecution. Only last week we were given ‘Anthropic Faces a New $75 Million Lawsuit for Pirating Books to Train Claude AI’ and less than 24 hours ago Harvard Business Review ‘You Outsourced the AI—but you still own the risk’ where we see “As enterprises increasingly embed third-party systems into their workflows, technological risk has led to new legal and operational responsibilities. Leaders may have little visibility into how a model was trained or how it changes, yet when it discriminates, mishandles data, or harms a customer, regulators and plaintiffs often look first to the company that deployed it. Peloton learned how that exposure can arise. Visitors to its website see a familiar invitation to “chat,” powered by a third-party vendor. According to a class-action complaint, the vendor recorded and stored conversations and used the data to improve its machine-learning models. Peloton neither built nor trained the system. Even so, a California federal judge allowed a claim against the company to proceed. The parties later jointly dismissed the case, without publicly disclosing the terms.”

Now consider the amalgamation of these factors (apart from some saying there is no bubble) there is (allegedly) “Worldwide spending on AI is forecast to reach $2.5 trillion. Venture capital and private corporate investments in AI firms sit near $258.7 billion globally, with over $750 billion in dedicated infrastructure and data center capital expenditure from major tech hyperscalers” we then see that the big players (Microsoft, Google, Amazon, Oracle) are basically overextended, facing class actions and all of them are looking at all sorts of financial hardship, because at some stage all these players will be made to rephrase the simple truth that AI is not DML/LLM, it requires more and when the programming is put under a loop that setting comes crashing down. I saw it two years ago that this is the only outcome in some sales people overselling what they had and the simplest setting is not a mere Quantum computer. It requires shallow circuits and what I tend to call The Epsilon processor. True AI cannot exist in a binary setting. The last one is my interpretation of it all and some might disagree. But the Epsilon processor allows for Null, False, True, Both and it is the Both part that makes true AI possible and of course a matching operating systems will be required as well a data carrier and in that case Oracle and Snowflake have the grounds for success. As I see it, all others will fall behind these two. 

And last month we were given that “400 newspapers sued OpenAI and Microsoft for scraping their content without permission or compensation to train artificial intelligence programs” even my data has been scraped. So how many will be successful? How many will fail? I have no idea, but the odds are decently stacked against these salespeople. And as the courts rule against these Fake AI bringers (as I see it) there will be a rush of people making a case, all who were sold AI (without clear DML/LLM settings in their contracts) are seeing their pupils transform into dollar signs and they will try to clean house. So when all these settings happen, is the stage for a bubble that far fetched? 

I am watching and watching and noting what is due. I reckon that at some point I get the one piece of evidence that will allow me to do just that, 2700 (out of nearly 4000) article scraped seemingly give me an optional case for some dollars (five million plus would be great). And I am not the greediest player in town. So at what point will the investors of $2.5 trillion ring the bell wanting to see payment for their investments? Goldman Sachs gave us last month ‘The AI Investment Boom: When Will It Pay Off?’ With “The economics of artificial intelligence are more questionable today than two years ago, says Goldman Sachs Research’s Jim Covello, as enterprise buyers, model companies, and hyperscalers have yet to show returns on their spend. In a conversation with Alison Nathan and George Lee on Goldman Sachs Exchanges, Covello discusses where we’ve seen economic value accrue to date and why semiconductor companies can’t continue to be the sole beneficiaries of the AI buildout.” As such we see people with serious economic skills worrying and wondering what comes next and I was there at least a year ago. So when will others see the doubt that I am seeing? The money people call the bubble a blasphemy, but they have vested interests. I do not. I merely see the flaws on technology that is at least 15-20 years away, data that is largely unvalidated and unverified and at this juncture people are investing trillions? Makes me all tingly that too many people are greed driven and too much vested to be part of a boom that does not exist, just like the settings of 2008, Inside Job showed that clearly and it seems that we have a similar setting evolve at least two times the previous caper. So if you consider that with all the reserves that hit took the economy 2 decades to fix and at present the reserves are gone, so what will happen now? Why aren’t others taking the stand the UK is making? Because others are in the believe that “America’s new Golden Age” is here? When you realize that it will take close to two decades to arrive, how long until too many investors pull the plug and go somewhere else? What will happen then? That is what I see coming, because at some point more and more people wake up, this is bound to happen, it always does.

So is the water high enough? Have a great day.

Leave a comment

Filed under Finance, IT, Law, Media, Science

The next stretch

In continuation of yesterday’s story, it is time to die you the next part. There is no news. As I personally see it, the news has become a much larger soapbox for big business and politicians. As such I can weave my own yarns and likely more entertaining. So where was I? I ended yesterday with 

The sensation was coming from the north north east, far beyond Ad Durar Street. He walked towards Yas Mall and decided to walk into IKEA. He walked into the restaurant and ordered the Salmon Teriyaki with Mango salsa, sparkling mineral water and a large coffee. He put 4 notes of 20 dirham in the hands of the lady and got some coins back. He needed and sat at a table by the window. There was not anything owe could do, but now he had a better feel of what was happening and the mall was not in the way of any interrupting feelings. He concentrated and viewed the people with his other sight. There was nothing out of the ordinary of anyone he could see, whatever this was, it would have a dark aura, optionally bordering on black. With every bite and sip he took, he was looking to the people in the back, even there, there was nothing to show him what was the cause. The weird thing what that he had not felt this feeling in over 15 centuries.  And this kind of power does not usually hide. It was more common in the 5th century when the Jinn were a lot more common than they are now. But they might be hiding in the folds of safety. Still. He had not felt this way for a long time and if there is a new player in town, he had to know. 

By the end of the meal, he had another blip, it felt like to was around Noya Luma. As such he decided to walk there. It took him around 45 minutes. He was taking his time to scan and see the people he did notice. It was more of a community, so the people were weary of him, they had not seen him before and after a while a person walked up to him and said “hal yumkinuk musaeadati min fadlika?” Apparently the man needed help. He nodded and followed him, his mind saw that there was no one to see and no cameras. The man wielded a knife and pointed it at him “Your money, now” He saw this coming a mile away and he smirked, the man pushed the knife towards his chest and he grabbed the hand holding the knife with his left hand, his right hand went around the neck of the man. His concentration told him that he was out of sight in every way. He felt the ring on his right hand. And he squeezed a little more and the next second the man was turning to ash, the power of his strength had evolved over the centuries, as such he was very blessed to turn this man to ash, even the bones dissolved, the calcium lost its coherence on the spot and he went away in a cloud of ash, the ash fell to the ground, but he knew that the smallest breeze and some water would be all that was needed to remove whatever evidence ever existed. He saw a few items, which he left where they were. The knife he would cast in some trashcan the first moment he found one. He continued on his route and when he arrived, he saw nothing of worthy, but he noticed a Starbuck sign and decided to sit down, have a sandwich and more coffee and feel the surroundings. 

When he got his coffee with a dynamite chicken sandwich and sat down, he could relax for now and feel what more could be coming his way. He was sitting for at least an hour when he felt the air change. It was what he expected, it seemed to be a jinn, but not a normal one. Darker and a lot more dangerous than he had ever seen. He saw none of the people that gave the vibe, but then he saw it, the aura was none existent, a weird setting, but it made sense now. It was not a Jinn at all, it was an afreet and not a normal one. He was seemingly a lot stronger than anything anyone in his larger family had ever faced. As such, he was not going to approach it now. He watched the man and saw the man was fitting in, not wanting to stand out. He liked that, because an afreet is normally full of chaos and destruction. This one was different, but he was not taking any chances. He then felt a larger different pulse, not anything he had ever felt, it felt Egyptian in origin, but he had no idea who it was, merely that it was massively old, older than he had ever felt. Optionally older than his grandfather, which was the weirdest of feelings. His grandfather was here before mankind was, so if it was older. What was it?

He binned his trash and walked back. Time to get back to the hotel, but the idea of getting food at that Rainforest cafe. The lamb mandi meal radiated with appeal and he was getting hungry. He was walking towards the Mall when he suddenly felt weird, his senses alerted him and he felt the afreet right behind him. No-one had approached him unfelt for centuries. He stopped and turned around. The man looked at him. Who are you? He asked. I go by the name Lavrinthi. And you? Let me introduce my self. I am Al-Malik al-Aswad, I am also known as the black king. I noticed you Olympian, but you are not really Olympian, are you? There is something different about you. Lavrinthi looked at the man. The other filing was not you, was it. Lavrinthi shook his head. I seems Egyptian, but I never felt anything like that before. The man nodded. I will let you leave now, the afreet turned around and walked away. Lavrinthi looked at the afreet walking of and went towards the Mall. Time for some diner and time to consider what he had experienced. He considered his options and decided to take another path. He decided to see if the afreet would approach him, or if he would keep his distance. After his meal he stopped at a coffee place and had another coffee. Time to get back to that Warner Brothers hotel, he was so looking forward to the breakfast they serve, but that will come after the night he has coming and it would be time to erect a very different kind of protection, because he had not experience anxiousness in many centuries and getting approached unseen was a really new experience for him.

What happens next? See another day, the next installment might come in the next few days.

Well this part is also for ADTV (or its parent Abu Dhabi Media). Perhaps they like it, perhaps not. I am getting my creative soul fed and that is good for me, a lot better than weeding out BS from optional BS, which is how I see a lot of the media exposure. And when the Financial times is giving us ‘Trump administration asks OpenAI to stagger release of new model to vet users’ as well as ‘Trump administration allows some access to Anthropic’s Mythos’, so whilst some people are considering that “Unease over Washington’s ad hoc regulatory approach remains.” And in all that time no one is considering that it opens up the European markets for DeepSeek and whether the next part is real ‘Microsoft Now Wants Users To Adopt Chinese DeepSeek AI After Failure Of Copilot’ (source: Channel News) is unknown, but that is opening a few Chinese walk ins into the west. The status? I have no idea, I honestly don’t. But some are saying that the race between China and the western AI markets are much harder to see and I get it, but what happens to that famous ‘Big Beautiful Stargate’? Consider that this is a $500 billion market being poured in a second or third placement and as I see it (and written about several times) set for a non-existing AI, or as I prefer to call it a fake AI. So we see a massive public-private AI infrastructure venture aiming to invest up to US$500 billion to build the world’s most powerful AI data centers and Europe and optionally the Commonwealth as well are setting up Chinese walls (a happy coincidence expression) against United States data centers. So, investing that much in data centers that are keeping track of a population of 349 members of the United States? I very much doubt that and I reckon that these centers will be avoided by China and several others as well. Did anyone consider what happened to the $500 billion? Just a questions to ask. 

Have a great day.

Leave a comment

Filed under Stories

On the lighter side

We all have that at times, the setting of a lighter side. You know the average romcom with sex, a little violence, the setting of blackmail and of course, some piece of software. The average day in the life of an fake AI. So I was ‘rudely’ awakened by news (at https://www.bbc.com/news/articles/cwyklykn5dwo) where we see ‘Anthropic accuses Chinese rival Alibaba of illicitly extracting AI capabilities’. So it made me laugh, b because this comes at the near start of a bubble heading straight for the HQ of Anthropic. Now let me show you what I was having in mind with all this and best I use graphics for that setting.

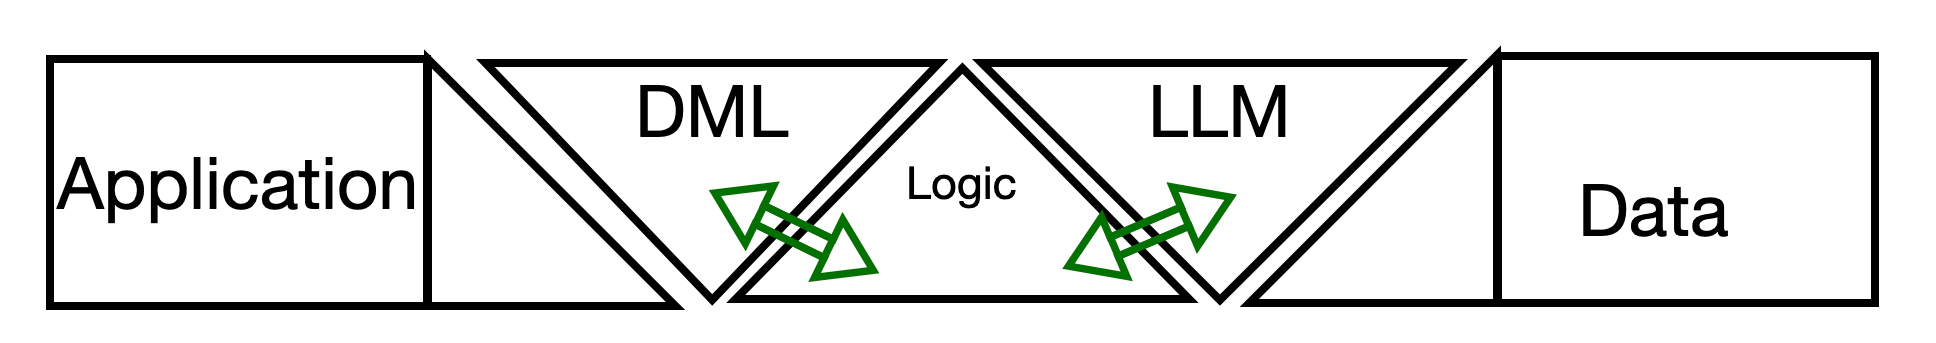
So we see the application on the left, the data on the right and in the middle we get the setting of that fake AI, you see it has DML and LLM, which I represented as a separate stage, but it could be one big thing, the coding is in the middle and there is interaction between the three like any application would have. So the middle part could be part of the application (it likely is), but for the clarity I wanted to show it like this. Because the picture fits better for the explanation. So the question becomes (the sound of dramatic horns in my mind)

“US artificial intelligence (AI) giant Anthropic has accused Chinese e-commerce and technology firm Alibaba of “brazenly” and “illicitly” extracting its Claude AI model’s capabilities.” How is this possible? I am not saying that it cannot be true, because that requires evidence, but if we see these parts, how blazingly stupid is anthropic to let someone else have a go at this. Beside this, what EXACTLY is “extracting its Claude AI model’s capabilities”? You see, when you see the image, the capabilities are shown in the application and cannot proceed without data (or less likely so), so as we are in the bubble setting this so called move sounds like a joke and with the added “In a letter sent to two members of the US Congress, the San Francisco-based company said operators linked to Alibaba carried out almost 29 million exchanges with Claude using thousands of fraudulent accounts in what it called the largest extraction campaign of its kind.” It seems like there is a massive security lack in all this (that is, if there is a transgression stage). But the setting that we see with “operators linked to Alibaba carried out almost 29 million exchanges” so as I see it, in 2014 we had the Cambridge Analytica scandal, where Facebook got ‘relieved’ of a whole lot of data. Doesn’t anyone learn from that experience, as such we get a repetition of all this? But I hope the story is clear. How was this even possible? As I see it “According to Anthropic, the campaign was carried out through what are known as “distillation attacks”, which extracted answers from a stronger AI model to train a weaker one.” This is a debatable setting (not stating it cannot happen), but the image I ‘created’ shows that a distillation attack requires a lot of information that requires insider knowledge to be successful. 

As such, I am not saying that Alibaba and the 40 fighters for the Palestinian cause is innocent, but I have doubts on the entire setting. I personally see this as a Dutch SNS setting. Where the massive mortgage (the invested dollars in Anthropic) are written of by putting it into a bad bank and letting that bad bank collapse. As such you need to be aware that I could be wrong, it is based on expected behavior and speculative settings, so do not take my word on it, but consider that at present the BBC is spinning you a yarn by presenting the data from others. Just so you know.

So, this is how I got my 05:00 wake up call, thank you BBC. Now it is time to get some coffee and optionally have breakfast afterwards.

Leave a comment

Filed under Finance, IT, Science